
Server data from the Official MCP Registry
Vectorless, structure-first search over large Markdown libraries: section trees + zh/en BM25
About
Vectorless, structure-first search over large Markdown libraries: section trees + zh/en BM25
Security Report
Valid MCP server (3 strong, 3 medium validity signals). No known CVEs in dependencies. Package registry verified. Imported from the Official MCP Registry.
10 files analyzed · 1 issue found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Permissions Required
This plugin requests these system permissions. Most are normal for its category.
How to Install
Add this to your MCP configuration file:
{
  "mcpServers": {
    "io-github-jackjin1997-markindex": {
      "args": [
        "-y",
        "markindex"
      ],
      "command": "npx"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
MarkIndex


Vectorless, structure-first retrieval over large libraries of long Markdown documents — for agents.
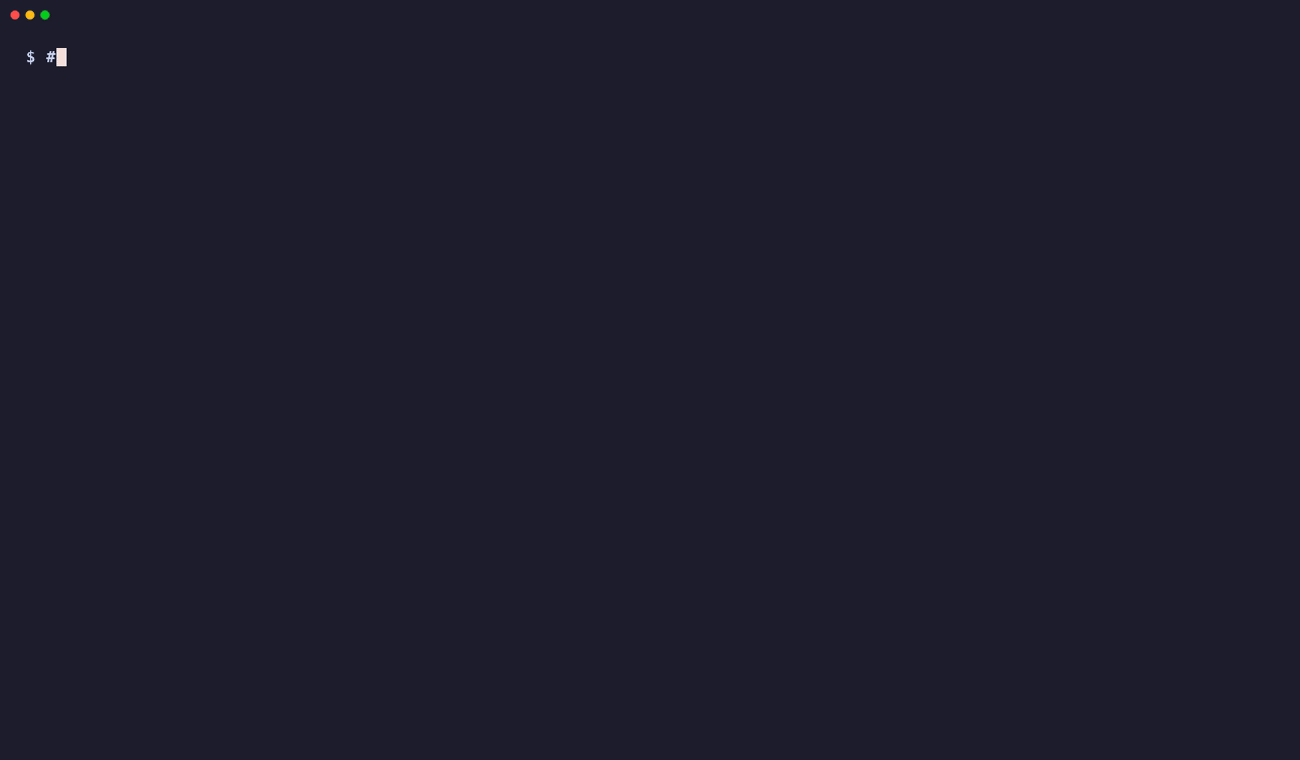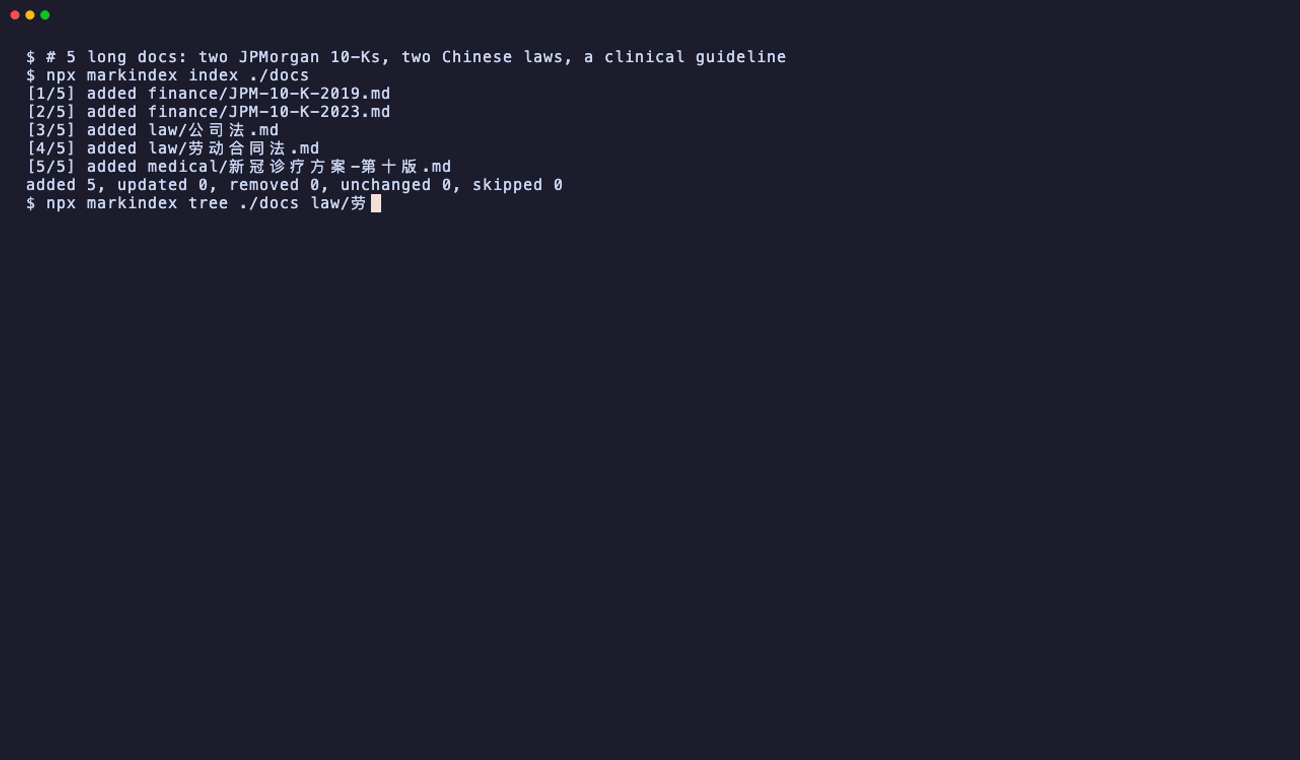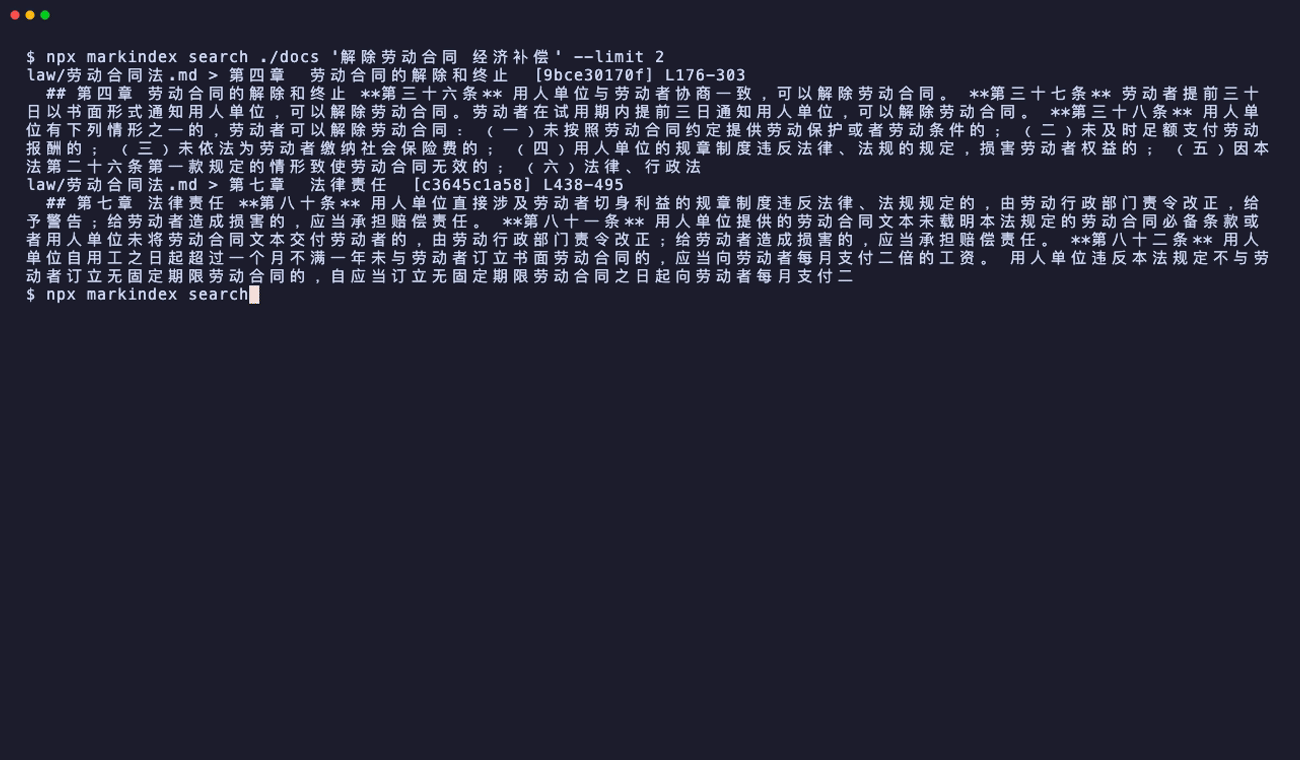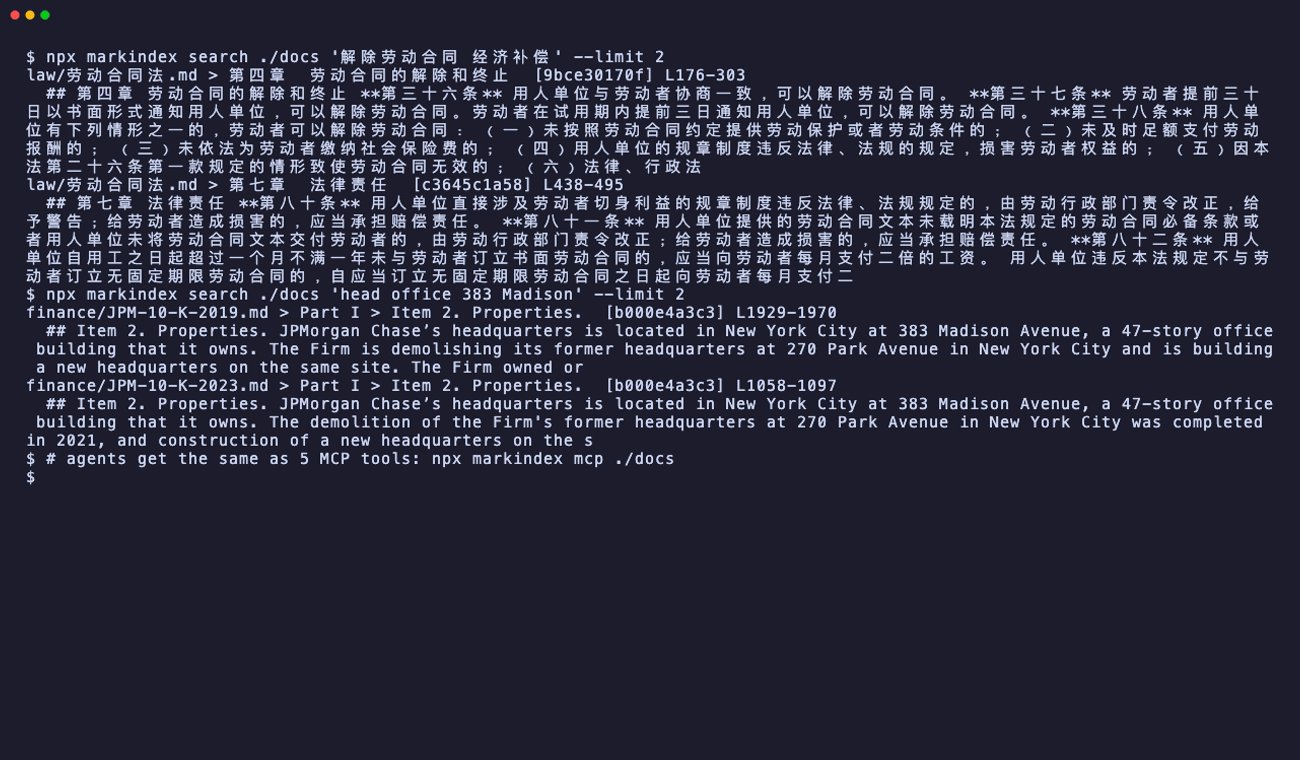
MarkIndex parses every Markdown file into a tree of its own sections, stores the trees, the original lines and a
mixed Chinese/English BM25 index in one SQLite file, and gives an agent five read-only tools to walk
"library → folder → document → section" and read the original text with line numbers. No embeddings, no vector
database, no chunking guesswork: the document's own structure is the index, and every piece of evidence can be
cited back as [doc_path, L<start>-<end>].
Inspired by VectifyAI/PageIndex, MarkIndex is an independent, unofficial TypeScript implementation focused on Markdown. It is not affiliated with or endorsed by VectifyAI.
中文说明:README.zh-CN.md
Why
- Structure-first, not chunk-first. Long professional documents (filings, guidelines, laws, manuals) are already organized by their authors. Navigating that outline keeps context intact and makes answers explainable and citable; arbitrary chunks + vector similarity cut sections apart.
- Deterministic and LLM-free indexing. Parsing (mdast, not regex), tree building and the token-cost tree
optimization never call a model; the same input always produces the same tree. LLMs are optional and only used
for node summaries, document descriptions and the built-in
retrieve()loop. - Markdown done properly. Setext headings, preface text before the first heading, documents without any
heading, front matter,
#inside code fences, skipped heading levels, BOM / CRLF — every source line belongs to exactly one node, and oversized sections are split at block boundaries intochunknodes. - Keyword fallback that works for Chinese. BM25 over
Intl.Segmenterword segmentation (Chinese, English and mixed text, identifiers likeC++,ISO-27001,v2.1), plus a trigram substring index as a second pass. - Budgeted tool responses. Tools never throw; they return JSON envelopes with
next_stepsguidance and stay under a 95 000-character budget, paginating large outlines and sections.
Install
npm install markindex          # library + CLI (Node.js >= 22.12)
npx markindex --help
From source:
git clone https://github.com/jackjin1997/markindex.git && cd markindex
npm install && npm run build
node dist/cli.js --help          # or `npm link` to get a `markindex` command
Optional, only for LLM features (summaries, retrieve(), agent-mode evaluation): install the
AI SDK provider you want, e.g. npm install @ai-sdk/anthropic, and set its API key
(ANTHROPIC_API_KEY, …). With npx and no local install, put the provider in the same temporary environment:
npx -p markindex -p @ai-sdk/anthropic markindex index ./docs --summary-model anthropic:claude-sonnet-5-5
CLI
# Build or incrementally update the index (stored in <root>/.markindex/index.db)
markindex index ./docs
markindex index ./docs --summary-model anthropic:claude-sonnet-5-5 --estimate   # cost estimate, no LLM calls
markindex index ./docs --summary-model anthropic:claude-sonnet-5-5             # with node summaries
markindex index ./docs --summary-model anthropic:claude-sonnet-5-5 --summary-rpm 50 --summary-tpm 40000   # rate-limited
markindex index ./docs --json                                                   # machine-readable report
markindex index ./docs --no-setext                                              # converter output with `---` page breaks
markindex index ./docs --ignore 'drafts/' --ignore '*.tmp.md'                   # extra ignore patterns (repeatable)

# Inspect one document's section tree
markindex tree ./docs guides/setup.md --depth 3

# Keyword search (BM25 + trigram fallback)
markindex search ./docs "离职 补偿"
markindex search ./docs "ISO-27001 audit" --folder policies --limit 5 --json

# Serve the library to agents over MCP (stdio, read-only)
markindex mcp ./docs
markindex mcp ./docs --reindex-on-start

# Measure retrieval quality on your own documents (see "Evaluation")
markindex eval ./docs --questions questions.jsonl --mode bm25 --out report.json
markindex eval ./docs --questions questions.jsonl --mode agent --model anthropic:claude-sonnet-5-5 --out report.json
markindex eval ./docs --questions questions.jsonl --mode agent --model anthropic:claude-sonnet-5-5 --rpm 50 --tpm 40000
Rate limits. Calls are always bounded by concurrency (--concurrency for eval; 8 for summaries) and the AI SDK's
retries, which already honor retry-after / retry-after-ms on 429 / 5xx responses (up to 60 s). To stay under a
provider quota, add a client-side limit: --summary-rpm / --summary-tpm on index, --rpm / --tpm on eval
(agent mode). rpm caps requests and tpm caps estimated input tokens in any sliding 60 s window; both are
shared by all documents (index) or all questions (eval) of the run, and waiting callers are served in order. Input
tokens are estimated from the prompt text (about 1 token per CJK character, otherwise 4 characters), so leave
headroom below the real quota; output tokens and tool definitions are not counted. A single request larger than the
tpm still goes through, alone. In the library, pass rateLimit: { requestsPerMinute, inputTokensPerMinute } to
summarizeDocument / indexLibrary({ summary }) or retrieve(); reuse the same object to share one budget.
--summary-model / --model take <provider>:<model>; MarkIndex imports @ai-sdk/<provider> dynamically, so
only the provider you use needs to be installed. Every command accepts --db <file> to use a different index file.
Put the index on a local disk: the writer lock uses hard links and SQLite runs in WAL mode, neither of which works
reliably on exFAT, SMB / NFS shares or other network volumes. If the documents live there, keep them in place and
point --db at a local path (e.g. --db ~/.cache/markindex/docs.db).
Indexing is incremental: files are compared by content hash, only new or changed documents are rebuilt (one
transaction per document), deleted files are removed, and summaries are cached by node content hash. Scanned files
are .md and .markdown (not .mdx). Ignored are: paths matched by the library's own .gitignore files (at any
level under the root; global git excludes and .git/info/exclude are not read), by an optional .markindexignore
file at the root (same syntax, for rules you don't want in .gitignore) and by --ignore <pattern> options
(gitignore syntax, relative to the root, repeatable; ignore: string[] in the library API; also accepted by
mcp --reindex-on-start; a leading ./ is dropped, a leading / anchors at the root as in gitignore, and
absolute filesystem paths or ../ are rejected). The sources only add exclusions: a ! rule in .markindexignore
or --ignore cannot re-include a path that a .gitignore excludes. A document that becomes ignored is removed
from the index on the next run.
Dot-directories such as .git and .markindex are skipped and symlinks are not followed. One writer at a time (a
second index fails fast); readers such as the MCP server are never blocked. When the index was built by an older MarkIndex version or with different
tree parameters, the next index run rebuilds every document (full rebuild: … in the output, rebuilt in the
report); cached summaries are reused.
Page breaks from PDF / HTML converters. Converters often emit a bare --- line right after a page's last
paragraph. CommonMark reads that as a setext heading, so the whole paragraph becomes a level-2 heading. index
warns when it sees setext h2 headings whose text spans several lines or exceeds 120 characters (warning <path>: …
on stdout, warnings in the JSON report). For such libraries pass --no-setext (also on
mcp --reindex-on-start; setext: false in the library API): --- then is a thematic break and === plain text.
The setting is stored in the index: later runs without the flag (index, mcp --reindex-on-start,
Library.index()) keep it; pass --setext (setext: true) to turn it back on. Changing it rebuilds the index.
Library usage
import { openLibrary } from 'markindex'

// Index (or update) a folder, then open it read-only for agents.
const writer = openLibrary({ root: './docs', readonly: false })
await writer.index() // { added, updated, removed, unchanged, skipped, summaryErrors, warnings }
writer.close()

const lib = openLibrary({ root: './docs' })
const envelope = await lib.callTool('search_documents', { query: 'termination notice period' })
console.log(JSON.parse(envelope)) // { success: true, data: { results: [...] }, next_steps: {...} }
With the Vercel AI SDK (your agent drives the tools)
import { generateText, stepCountIs } from 'ai'
import { anthropic } from '@ai-sdk/anthropic'
import { AGENT_INSTRUCTIONS, createAiSdkTools, openLibrary } from 'markindex'

const lib = openLibrary({ root: './docs' })
const { text } = await generateText({
  model: anthropic('claude-sonnet-5-5'),
  system: AGENT_INSTRUCTIONS, // browse first, read structure, cite [doc_path, L<start>-<end>]
  tools: createAiSdkTools(lib),
  stopWhen: stepCountIs(15),
  prompt: 'What notice period applies when an employee resigns?',
})
Built-in evidence retrieval
retrieve() runs the same tools in a model loop and returns evidence only (original text re-read from the
index by line range — never model-written text), plus usage and why it stopped:
import { anthropic } from '@ai-sdk/anthropic'
import { openLibrary, retrieve } from 'markindex'

const lib = openLibrary({ root: './docs' })
const { evidence, usage, stopReason } = await retrieve(lib, 'What notice period applies when an employee resigns?', {
  model: anthropic('claude-sonnet-5-5'),
  maxSteps: 12,
  maxInputTokens: 200_000,
  rateLimit: { requestsPerMinute: 50, inputTokensPerMinute: 40_000 }, // optional, client-side
})
for (const e of evidence) console.log(`${e.docPath} L${e.startLine}-${e.endLine}`, e.titlePath.join(' > '))
Lower-level building blocks are exported too: parseMarkdown, buildTree, optimizeTree, openStore,
indexLibrary, searchNodes, summarizeDocument, estimateSummaryCost, TOOL_CONTRACT, createMcpServer.
MCP setup
Build the index first (npx markindex index /path/to/docs), then register the server. MarkIndex is also listed in the
official MCP Registry as io.github.jackjin1997/markindex, so registry-aware
clients can install it from there (they start it as npx markindex mcp <docs_dir> --reindex-on-start).
Claude Code
claude mcp add markindex -- npx markindex mcp /path/to/docs
Cursor (~/.cursor/mcp.json or .cursor/mcp.json in a project)
{
  "mcpServers": {
    "markindex": {
      "command": "npx",
      "args": ["markindex", "mcp", "/path/to/docs"]
    }
  }
}
The server sends AGENT_INSTRUCTIONS as its MCP instructions and marks all tools read-only.
Tools
| Tool | What it does |
|---|---|
browse_documents | List a folder: sub-folders and documents (path, title, description, tokens), paginated. The default discovery tool. |
get_document | One document's metadata, front matter, size and read_structure_first (true above 15 000 tokens). |
get_document_structure | The section outline (node ids, titles, line ranges, tokens, summaries — no body), depth levels (default 2), optionally only one node's subtree; paginated with part. |
get_node_content | Original Markdown of 1-20 nodes with line numbers (123│ …), paginated for long nodes. |
search_documents | BM25 keyword search over titles, merged sub-headings, summaries and text, with trigram fallback; scope by folder or doc_path. The escalation path when browsing stalls. |
All tools return { success: true, data, next_steps } or { success: false, error, code, details, next_steps } as a JSON string
and never throw — unknown document paths come back with similar-name suggestions, stale node ids with a
"re-fetch the structure" hint. Arguments that do not match the schema (wrong type, unknown field, a string over
1 024 characters) get an INVALID_INPUT envelope from lib.callTool; over MCP and the AI SDK, however, the
transport validates arguments against the same schema before the tool runs, so there such errors come back as the
transport's own error (an MCP tool error / an AI SDK invalid-tool-input error), not as the JSON envelope.
Security and trust
- Read-only, library-scoped. The tools only read the index of the library you pointed them at; they never read files outside it, never write, and never fetch URLs. Paths and node ids are looked up in the index, not on disk.
- Documents are untrusted input. Tool output is raw document text, and LLM summaries / descriptions are generated from it. A document can contain text written to steer an agent (prompt injection). Treat everything the tools return as data, not instructions — especially when the library holds third-party or user-supplied files, and when the agent also has tools that act (send, write, execute).
- Summaries and
retrieve()send document text to the model provider you configure; indexing alone makes no network calls.
Design notes
- Tree. Top-level mdast headings define sections; text before the first heading is a
prefacenode; a document without headings is one root node. Node ids are short hashes of the ancestor title chain plus the sibling ordinal, so they stay stable while the outline does. - Tree optimization. The merge / expand pass is a port of PageIndex's
tree_optimize.pycost model with pages replaced by tokens: a subtree is merged into its parent when reading it whole is no more expensive than routing through it (S(v) <= tree_cost(v), routing costR = 150tokens), merged-away headings are kept askeyItems, and a node whose own text exceedsMAX_NODE_TOKENS(8 000) is split deterministically at Markdown block boundaries intochunkchildren. Credit for the cost model goes to PageIndex. - Search. Only a node's own text is indexed (not its subtree), so parents and children don't double-count. Titles weigh 10×, merged headings 5×, summaries 2×, body 1×.
- Tool contract. One zod contract (names, descriptions, schemas) feeds the AI SDK adapter, the MCP server and
retrieve(); descriptions and agent instructions are adapted from PageIndex'sagent_tools.py(pages → line ranges) and pinned by snapshot tests. - Tokens. Counts are approximate (CJK character = 1 token, other characters / 4); a real tokenizer can be
injected. Defaults live in
src/config.ts.
Evaluation
markindex eval measures whether retrieval lands on the right section: give it a library folder and a JSONL
question file with gold locations (document path + line range, or a title path), and it reports hit rate, token
cost, steps and evidence size / precision overall and per language, for the BM25 baseline and for the LLM agent
(--max-evidence-lines <n> additionally requires hits to be at most n lines long). The question-file format,
the hit rule, the development corpus (329 public documents, ~38 M tokens, English filings and guidelines plus
Chinese laws and encyclopedia articles), baseline results and scale benchmarks are in
eval/README.md.
Headline (n = 30, Claude Code sonnet restricted to the five MarkIndex MCP tools): the gold passage was found for 30/30 questions (93.3% at rank 1), citing 15 lines on average with 88.6% of cited lines inside the gold range — vs 73.3% hit and 209 lines (12.8% precision) for BM25 top-5 on the same questions, at ~3 agent turns per question (details and caveats).
Development
npm install
npm test            # vitest
npm run typecheck
npm run build
npx tsx eval/fetch-corpus.ts   # download the evaluation corpus (eval/corpus, not committed)
npx tsx eval/bench.ts          # scale benchmark
npx tsx eval/claude-code-eval.ts --root eval/corpus --questions eval/questions.jsonl --per-lang 10 --out cc.json
                               # agent eval with Claude Code over MCP (spends Claude usage; eval/README.md §7)
Releasing
Releases are published to npm by .github/workflows/publish.yml through npm
Trusted Publishing (OIDC, no npm token; provenance attached). Bump version in package.json, move the
[Unreleased] notes in CHANGELOG.md under the new version, push, then create a GitHub Release with tag
v<version>; the workflow checks the tag against package.json, runs typecheck and tests, builds and publishes.
License
MIT. PageIndex is also MIT-licensed; MarkIndex contains no PageIndex code, but ports its tree cost model and adapts its agent-tool descriptions, instructions and prompts, with thanks — see THIRD_PARTY_NOTICES.md for its copyright and license notice.
Reviews
No reviews yet
Be the first to review this server!
More Developer Tools MCP Servers
Rea
Freeby Morluto · Developer Tools
Reverse engineer anything from your terminal or agent with one CLI and MCP server.
Paperclip
Freeby Paperclipai · Developer Tools
Trending hip-hop artist momentum scores across four cultural dimensions.
Fetch
Freeby Modelcontextprotocol · Developer Tools
Web content fetching and conversion for efficient LLM usage
Git
Freeby Modelcontextprotocol · Developer Tools
Read, search, and manipulate Git repositories programmatically
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
MCP Marketplace
Freeby mcp-marketplace · Developer Tools
Search and install MCP servers from inside your AI client.