
Server data from the Official MCP Registry
Learns your writing voice locally and rewrites AI drafts so they sound like you.
About
Learns your writing voice locally and rewrites AI drafts so they sound like you.
Security Report
1 tool verified · Open access · No issues found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Remote servers are capped at 8.0 because source code is not available for review. The score reflects endpoint verification only.
How to Install
Add this to your MCP configuration file:
{
  "mcpServers": {
    "io-github-joshmcq-humanifyme": {
      "args": [
        "-y",
        "humanifyme"
      ],
      "command": "npx"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
HumanifyMe
Make AI sound like you. · humanifyme.com
Try it in your browser → No install and no key: paste a few of your own messages and an AI draft, and get the draft back in your voice.




HumanifyMe learns how one specific person writes, then rewrites an AI agent's output in that person's voice before anyone reads it. Install it once and every agent on your machine — Claude Code, Cowork, Cursor — rewrites in the same voice. It is not "write better." It is "stop sounding like AI."
It runs locally. The only thing that crosses the network is a redacted draft sent to the LLM provider you choose.
Quickstart
Run the secure one-time setup first. It explains the privacy boundary, hides your provider key while you type it, validates the provider, collects three writing samples, builds your profile, and offers a first rewrite:
npx -y humanifyme@0.2.2 setup
Want to see it work before installing? A live demo of the setup and rewrite flow is at humanifyme.com.
Never paste a provider key into an AI chat or pass it as a command-line flag. Then install the plugin from the bundled marketplace — no clone or build:
claude plugin marketplace add JoshMcQ/HumanifyMe   # register the marketplace
claude plugin install humanifyme@humanifyme        # installs 3 skills + the MCP server
Then use /humanifyme:humanify on any draft, or let the bundled skills trigger
it after an agent drafts an email, PR, or message. The CLI and every installed
agent share the profile stored in ~/.humanifyme/. Use
/humanifyme:build-voice-profile later to add samples or rebuild it.
Tried it? Rate a rewrite: two dropdowns, and it is the feedback that improves voice matching most.
Run /reload-plugins if you installed mid-session. Using a different agent (Cursor, Continue, Cline, Windsurf, Zed, ChatGPT desktop) or the CLI? See Install.
Want to inspect a draft before setting up a profile? The analyzer is local, deterministic, and needs no API key:
echo "At its core, this robust approach paves the way." | npx -y humanifyme analyze
It reports the exact phrases and punctuation it matched against the public 90-sign AI-writing checklist. It is an editing aid, not an AI detector; subjective signs stay labeled for human review instead of being turned into a fake probability.
Why it exists
People hand more of their writing to AI every day — commits, PR descriptions, Slack posts, email drafts — and every agent produces the same recognizable register: polished, balanced, faintly corporate. Recipients have learned to spot it. The usual fixes (Grammarly, Wordtune, "AI humanizers") push text toward a generic professional voice, which is the opposite of the goal.
Few-shot prompting alone cannot close the gap. A large 2025 study ran tens of thousands of generations across frontier models and hundreds of real authors and found that dropping a few samples into a prompt and asking a model to "write like me" hits a ceiling on casual voice (Wang et al., 2025). HumanifyMe's answer to that ceiling is a persistent, retrievable corpus of your writing plus a paraphrase-then-restyle rewrite — not a longer prompt.
MCP vs. plugin. MCP (Model Context Protocol) is the protocol HumanifyMe speaks, so any MCP-compatible agent can call its
humanify_texttool. A plugin is the packaging format (used by Claude Code and Cowork) that bundles the MCP server plus skills into one installable unit. You can install the plugin, or register the MCP server directly.
How it works
An agent calls one tool, humanify_text. Everything else happens on your machine.
flowchart LR
    Agent["AI agent (Claude Code / Cowork / Cursor)"] -->|"calls humanify_text"| Tool["humanify_text (MCP tool)"]
    Tool --> Engine["rewrite engine"]
    Engine --> Redact["redaction"]
    Engine --> Memory["voice memory (retrieval)"]
    Engine --> Provider["LLM provider"]
    Engine --> Verify["deterministic verify gate"]
    Redact -. "masked draft only" .-> Provider
    Memory --> DB[("local store: ~/.humanifyme/data.db")]
    DB --> S["samples"]
    DB --> P["profile"]
    DB --> E["embeddings"]
The rewrite is paraphrase-then-restyle: strip the source style, re-render toward your learned voice, then run a deterministic gate no prompt can skip. The three pieces that carry the design:
- Deterministic verification — the quality moat. Most "rewrite in my voice" tools stop at the prompt and hope. After every generation,
src/engine/verify.tsruns five mechanical checks against the redacted draft: words the model introduced from your avoid-list, dropped numbers (dates, prices, versions), broken URLs, vanished redaction placeholders, and your learned casing register. Failures on the first attempt become instructions for one retry; survivors become user-facing "review before sending" notes. It never blocks output. - An editable voice fingerprint. Your voice is a readable, labeled JSON object — sentence length, formality, directness, punctuation habits, words you avoid, your real greetings and sign-offs — not an opaque vector. Every dimension can be specialized per context (casual, professional, email, annoyed, …) and deep-merged at rewrite time. You can read it and correct it.
- Retrieval over your own writing. Embeddings of your past messages live locally and are pulled as few-shot exemplars at rewrite time, with the structured fingerprint as the structural spec and cold-start fallback. One persistent voice memory in
~/.humanifyme/data.db, shared across every agent and project on your machine. The default embedder is offline and dependency-free; MiniLM and Ollama are opt-in, local-only upgrades.
Deep dives: architecture & rewrite pipeline · voice memory & retrieval · data model.
Install
As a plugin (start here)
HumanifyMe is bundled as a plugin in humanifyme.plugin/: a .claude-plugin/plugin.json manifest, an .mcp.json that registers the MCP server, and three skills (humanify, build-voice-profile, humanify-pr). The repo root ships a marketplace catalog at .claude-plugin/marketplace.json. The two-line install is in Quickstart.
The bundled .mcp.json launches the server from the published npm package via npx -y --package humanifyme@0.2.2 humanifyme-mcp, pinned to a known build, so the plugin works on a fresh machine with nothing checked out. Copy-paste setup for other agents is in docs/install/.
Command line
From npm, one command walks through privacy, provider, three samples, profile creation, and a first rewrite. API-key input is hidden and setup resumes from the last completed step if interrupted.
npx -y humanifyme setup
npx -y humanifyme rewrite draft.txt
Contributing from a checkout requires Node 22.5 or newer:
npm ci
npm run build
node dist/humanifyme.mjs setup
Raw MCP registration
If your agent does not use the plugin format, register the server directly:
claude mcp add humanifyme -- node /path/to/repo/dist/humanifyme-mcp.mjs
The server exposes 16 humanify_* tools in one registry: the headline humanify_text, plus feedback and metrics, sample add/list/delete, profile get/build/update/delete, provider set, key test, audit list, wipe-all, and two importers. The same engine runs without MCP via the humanifyme CLI.
Does it actually work?
A four-register evaluation: four writers with distinct voices (casual lowercase, formal sentence-case, terse technical, warm enthusiastic), five generic-AI drafts each, rewritten with retrieval on and off — 20 rewrite pairs. Full method, raw numbers, and reproduction steps are in docs/proof/README.md. Run date 2026-06-24.
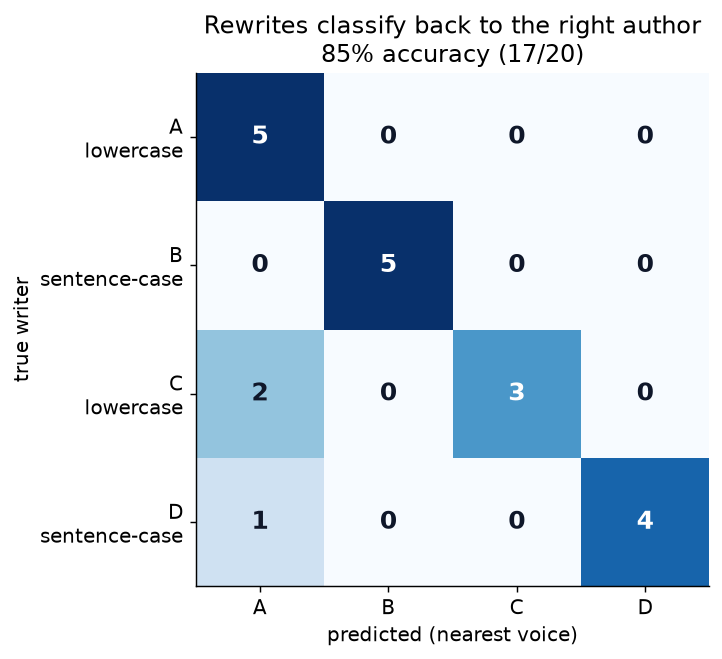
Attribution (a sanity check, not proof). Ask which of the four writers each retrieval-grounded rewrite lands closest to under a stylometric scorer: 17 of 20 (85%) land on their own writer. Be skeptical, because we are — the writers differ mostly by register, the scorer is eight coarse surface features, and every miss falls between the two lowercase writers. It shows the machinery does something; it is not evidence it reproduced anyone's idiolect.
Retrieval pulls the rewrite closer to the real writer for three of four writers this run (lower is closer). We report writer B even though retrieval hurt it — the metric is noisy and we are not rounding a loss into a win.
| Writer | Distance ON | Distance OFF | Retrieval helps? |
|---|---|---|---|
| A (casual / lowercase) | 2.35 | 3.38 | yes, clearly |
| B (formal / sentence-case) | 3.22 | 2.32 | no, worse this run |
| C (terse / technical) | 2.92 | 3.09 | yes, small |
| D (warm / enthusiastic) | 2.47 | 2.69 | yes, small |
What we do not claim: that an LLM judging an LLM is proof (we ran it; it's a weak proxy); that retrieval helps every writer; that the MVP already does style-pure retrieval; or that redaction recall is a privacy guarantee. The honest test is human evaluation, and the proof doc spells out every limitation.
Privacy
HumanifyMe is local-first and redacts before it sends. The privacy assurance is architectural, not a recall percentage: the engine runs on your machine and the privacy-critical code (src/privacy/, src/network/, src/engine/verify.ts) is Apache-2.0, so you can read exactly what leaves.
- Local-first. All state lives under
~/.humanifyme/, overridable only viaHUMANIFYME_HOME. Raw samples never leave that directory. - Keys stay in the OS credential store. Cloud API keys are stored in Windows Credential Manager, macOS Keychain, or Linux Secret Service. HumanifyMe fails closed if the keychain is unavailable; it never falls back to plaintext config storage.
- Redact before send.
redact()masks emails, phones, US addresses, Luhn-checked cards, API keys, AWS access-key IDs, and JWTs into numbered placeholders before the single network call;restore()swaps them back after. Retrieved exemplars are re-redacted at send time — store-time redaction is never trusted. Best-effort by design, and documented as such. - Outbound allowlist + static scan.
src/network/outbound-scan.test.tsasserts that onlysrc/providersandsrc/networkmay callfetch(), and that every hardcoded host is on a 4-entry allowlist. - Metadata-only telemetry. The audit log and opt-in feedback record counts, latency, and byte sizes — never content. Anonymous sharing is OFF by default and gated to once per 24h.
On the golden fixtures in src/privacy/redact.test.ts, redaction masks all seven planted secret classes with no false positives across 20 plain paragraphs — deterministically. The full methodology is in specs/privacy-security-spec.md, the one set of rules contributors cannot break.
Not a detection-bypass tool
HumanifyMe will not help you beat AI detectors, and the specs say so. The research backs the stance on the merits: detection is fragile — there is a theoretical bound on detector reliability and recursive paraphrasing defeats most detectors (Sadasivan et al., 2024) — and a tool that wins at fooling classifiers proves nothing about whether the output sounds like you. We track AI-tell density only as a sanity floor, never as a target.
The research it is based on
Every design choice maps to prior work, and each write-up is explicit about where the science stops and our opinion starts: prior-work survey · state-of-the-art review · evaluation design. The deterministic verify gate, in particular, is a design bet against a named failure mode, not a validated published result. The full, linked reference list is below.
Why I built it
I wanted AI to write messages for me and it never quite could. I would have something typed up, ask it to just tighten the wording, and get back a completely different message in a voice that was not mine. So I started prompting my way around it, and that turned into this.
Most of the code was written with Claude Code, Anthropic's agentic coding tool, against specs and acceptance criteria I wrote and reviewed. The product and architecture calls are mine: plugin-first distribution, keeping everything local, the verify gate, and how it gets evaluated.
Repository layout
/README.md                       <- you are here
/src/                            <- the MCP server + CLI (TypeScript)
/humanifyme.plugin/              <- plugin bundle: manifest, MCP registration, skills
/prompts/                        <- LLM prompt templates for the rewrite engine
/evals/                          <- ablation runner, scorers, results
/docs/                           <- research, proof, architecture, install, data model
Contributing
We want maintainers. Read CONTRIBUTING.md, then read src/engine/rewrite.ts, src/engine/verify.ts, and src/privacy/ — that trio is the heart of the methodology. The rules you cannot break live in specs/privacy-security-spec.md; when you change behavior, src/network/outbound-scan.test.ts and src/engine/verify.test.ts must stay green. Good first issues are labeled good first issue.
If HumanifyMe saves you from sounding like a robot, give us a ⭐ on GitHub and help spread the word. Stars and contributors are how an open-source project like this gets found.
License
Apache License 2.0. See LICENSE and NOTICE. The whole repository is open source, including the rewrite engine, prompts, and the privacy-critical modules, so anyone can verify exactly what data does and does not leave a machine. "HumanifyMe" is a trademark of Joshua McQueary; the license does not grant trademark rights.
Drawn from the project's prior-work survey.
- Stamatatos. A Survey of Modern Authorship Attribution Methods. JASIST, 2009.
- Koppel, Schler & Argamon. Computational Methods in Authorship Attribution. JASIST, 2009.
- Abbasi & Chen. Writeprints. ACM TOIS, 2008.
- Patel et al. LISA: Learning Interpretable Style Embeddings. Findings of EMNLP, 2023.
- Stamatatos, Bevendorff et al. PAN 2023 Cross-Discourse Authorship Verification Overview. CLEF 2023 Working Notes (CEUR-WS).
- Salemi & Zamani. RAG vs PEFT for Privacy-Preserving Personalization. ICTIR (ACM SIGIR), 2025.
- Li et al. Teach LLMs to Personalize, 2023.
- Neelakanteswara et al. RAGs to Style. Personalize at ACL, 2024.
- Wegmann, Schraagen & Nguyen. Same Author or Just Same Topic? RepL4NLP at ACL, 2022.
- Wang et al. Can Authorship Representation Learning Capture Stylistic Features? TACL, 2023.
- Krishna, Wieting & Iyyer. STRAP. EMNLP, 2020.
- Patel, Andrews & Callison-Burch. STYLL, 2022.
- Wang et al. Catch Me If You Can? Not Yet. Findings of EMNLP, 2025.
- Sadasivan et al. Can AI-Generated Text Be Reliably Detected? TMLR, 2024.
- Rivera-Soto et al. Few-Shot Detection of Machine-Generated Text Using Style Representations. ICLR, 2024.
- Jangra et al. Evaluating Style-Personalized Text Generation, 2025.
- Jin et al. A Survey of Deep Learning for Text Style Transfer. Computational Linguistics (MIT Press), 2022.
Reviews
No reviews yet
Be the first to review this server!
More Developer Tools MCP Servers
Git
Freeby Modelcontextprotocol · Developer Tools
Read, search, and manipulate Git repositories programmatically
Fetch
Freeby Modelcontextprotocol · Developer Tools
Web content fetching and conversion for efficient LLM usage
Worldmonitor
Freeby Koala73 · Developer Tools
Live markets, conflicts, country risk, chokepoints, energy, and China decision signals. 86 tools.
Paperclip
Freeby Paperclipai · Developer Tools
Trending hip-hop artist momentum scores across four cultural dimensions.
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
mcp-creator-python
Freeby mcp-marketplace · Developer Tools
Create, build, and publish Python MCP servers to PyPI — conversationally.