Server data from the Official MCP Registry
Read-only crypto research skills that check a price, RSI and ATR against independent sources.
About
Read-only crypto research skills that check a price, RSI and ATR against independent sources.
Remote endpoints: streamable-http: https://nota-ryo.vercel.app/mcp
Security Report
Remote MCP endpoint verified (121ms response). Server: nota. 4 tools available. 3 trust signals: valid MCP protocol, known domain (vercel.app), registry import. 1 security issue detected.
4 tools verified · Open access · 2 issues found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Remote servers are capped at 8.0 because source code is not available for review. The score reflects endpoint verification only.
Permissions Required
This plugin requests these system permissions. Most are normal for its category.
How to Connect
Remote Plugin
No local installation needed. Your AI client connects to the remote endpoint directly.
Add this to your MCP configuration to connect:
{
  "mcpServers": {
    "io-github-pugarhuda-nota": {
      "url": "https://nota-ryo.vercel.app/mcp"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
Nota
An AI trading opinion you can audit. A council of specialised agents debates live RYO market
evidence and records the practice trade it would make as a replayable decision receipt:
nota replay <id> rebuilds it from the stored evidence and prints identical: true, every cited
number is read back out of the evidence rather than retyped by the model, and independent sources
audit RYO's own price and indicators before anything is sized. Built for the RYO-CHAN Hackathon 2026.
Tracks entered: 1 Autonomous Agents (council, receipts, watch loop, a derivatives gate the
council cannot argue past), 2 Dashboards (diff-first receipt dashboard, and the
RYO Verdict Scorecard), 3 New Skills
(narrative_convergence, news_verify, price_crosscheck, technicals_crosscheck,
positioning_check, move_base_rate, verdict_track_record, liquidity_check, crowd_odds, all
in RYO's envelope).
Judging? https://nota-ryo.vercel.app/judges gives one screen per track: what to open, and which rubric line it answers. The dashboard can run the council live on fresh RYO evidence. What Nota does not do is in LIMITATIONS.md, and why it is built this way is in DECISIONS.md.
What Nota does that a receipt-and-replay agent alone does not:
- It audits RYO itself. The Verdict Scorecard locks
RYO's own
deep_analysisverdict and trade plan for 25 majors every day, before the outcome is known, and settles each plan on OKX candles. RYO never grades itself, and every miss is counted. - It found a defect in RYO's data and gates it. Some derivatives fields carry one value across unrelated tokens on the same day. Code withholds them from the council and names the tokens.
- It proves the record was not rewritten. Every receipt and lock is anchored in Bitcoin through OpenTimestamps, and every ledger snapshot CI pushes is attested with Sigstore.
- You can break it on purpose. /drill injects seven real failure modes into the real pipeline, offline, and shows each refusal next to a healthy run.
RYO Verdict Scorecard
Every deep_analysis answer carries a verdict and a trade plan (a stop 1.5 ATR away, a target at
+1R). RYO never reports what became of either. nota lock stores the whole answer for 25 majors
once a day (never twice within 20 h); nota settle later asks OKX's public candles which level was
touched first within 24 h and 72 h: 1-minute candles from the lock to the first full hour, hourly
after, and an hour that touched both levels is split on its own 1-minute candles. RYO does not grade
itself: the bracket is re-anchored to OKX's price at the lock, and a lock where the two prices are
more than 2% apart is kept as basis_mismatch and never settled. A window with an hour OKX never
published is retried for a day, then kept as unsettleable. Verdict pairs, confluence states and
RYO's momentum gate are each compared on the target-first rate and on the return at the horizon
(plans that touched neither level included): within each lock day, combined with Mantel-Haenszel
weights so a lopsided day cannot flip the sign, with a p-value that shuffles labels within clusters
of overlapping windows. Nothing is called distinguishable before 10 shared days and p < 0.10; a
simulated null in the tests checks that rate. Every failed lock is a counted row, one per token and
day however often retried, and a dead key stops the run after one call with an aborted row. The
page also reports how often each lane of RYO's answer came back available, per RYO's own words.
/scorecard shows it, most urgent first;
/api/scorecard?horizon=24|72 is the raw record and /api/scorecard.csv the same table as CSV
(one row per lock and horizon, failures included). The page carries a schema.org Dataset
description (JSON-LD) naming both downloads.
Anchored in Bitcoin, not in Nota's clock. "Locked before the move" is only worth something if
nobody, Nota included, can backdate a lock. nota stamp submits the SHA-256 of every good lock row and
every receipt, exactly as stored, to three public OpenTimestamps calendars and keeps the .ots proof;
a later run swaps in the Bitcoin attestation once the calendar has one, after checking that block's
merkle root against mempool.space. The scorecard and the dashboard say "Bitcoin block N" or
"timestamp pending (submitted …)" from that stored status and nothing else. To check one yourself:
curl -o lock.json https://nota-ryo.vercel.app/api/scorecard/locks/<id>.json    # the row as stored
curl -o lock.json.ots https://nota-ryo.vercel.app/api/scorecard/locks/<id>.ots
ots verify lock.json.ots        # pip install opentimestamps-client; or drop both files on opentimestamps.org
Receipts work the same way with /r/<id>.json and /r/<id>.ots.
Day 0 (2026-09-18): 25 of 25 locked, 4 CONFIRMED and 21 MIXED, and 7 plans long while RYO's own
verdict was cautious (XRP, DOGE, ADA, LINK, SUI, BCH, WIF).
What the council may not cite
deep_analysis.data.derivatives reported funding 0.0 and a null long/short ratio for every token
probed on 2026-09-18, and one 24 h open-interest change repeated exactly across unrelated tokens
(-10.44 for ETH, SOL, WIF and ONDO). positioning_check rules each field without guessing RYO's
undocumented definitions: the same value on two other tokens locked that day is
not_token_specific, an opposite sign to OKX's coin-terms OI change of 3% or more is
conflicts_with_venue, BTC funding of exactly 0 while RYO's own sentiment tool reports BTC funding
is conflicts_with_ryo. A withheld field reaches the prompt as withheld: <reason> and a
citation of it is dropped. scripts/gate_ab.py <id> re-runs a receipt's council without the gate;
the first run (docs/gate-ab/cd5ada18b179.json) changed nothing, and is published anyway.
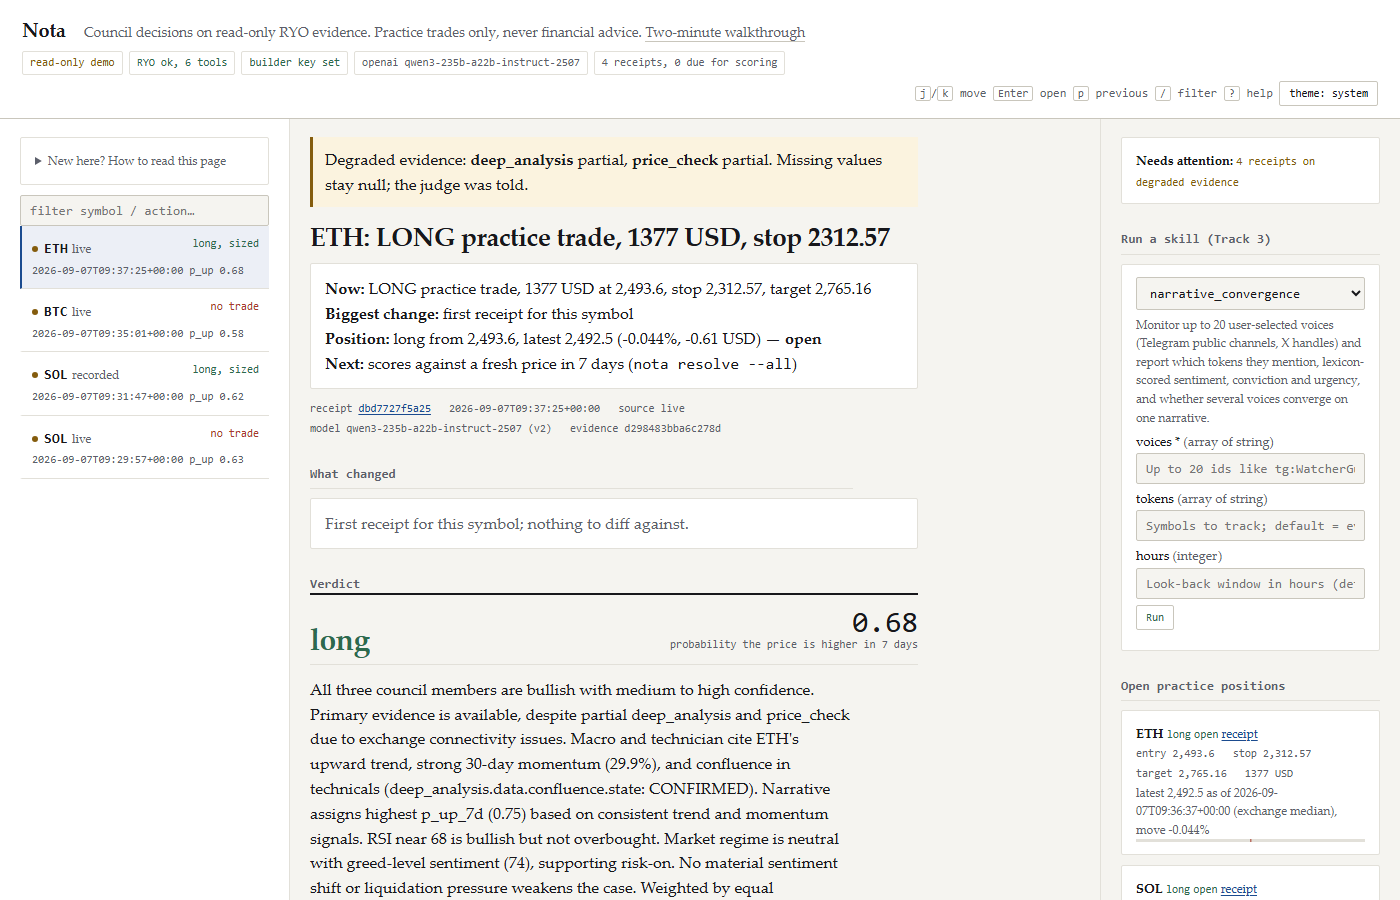
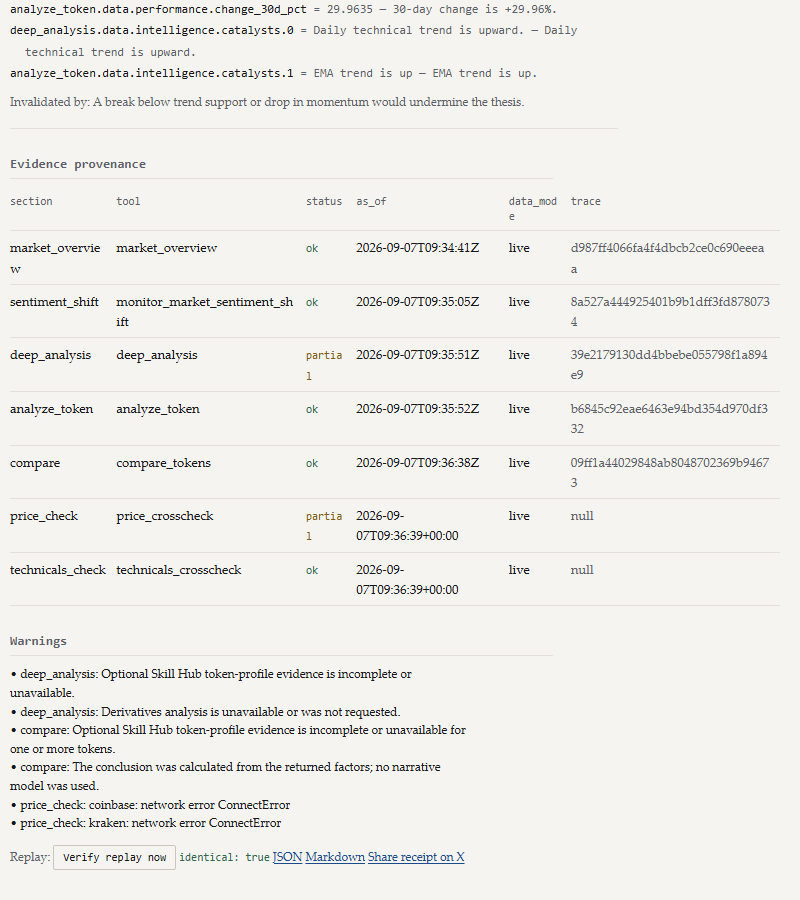
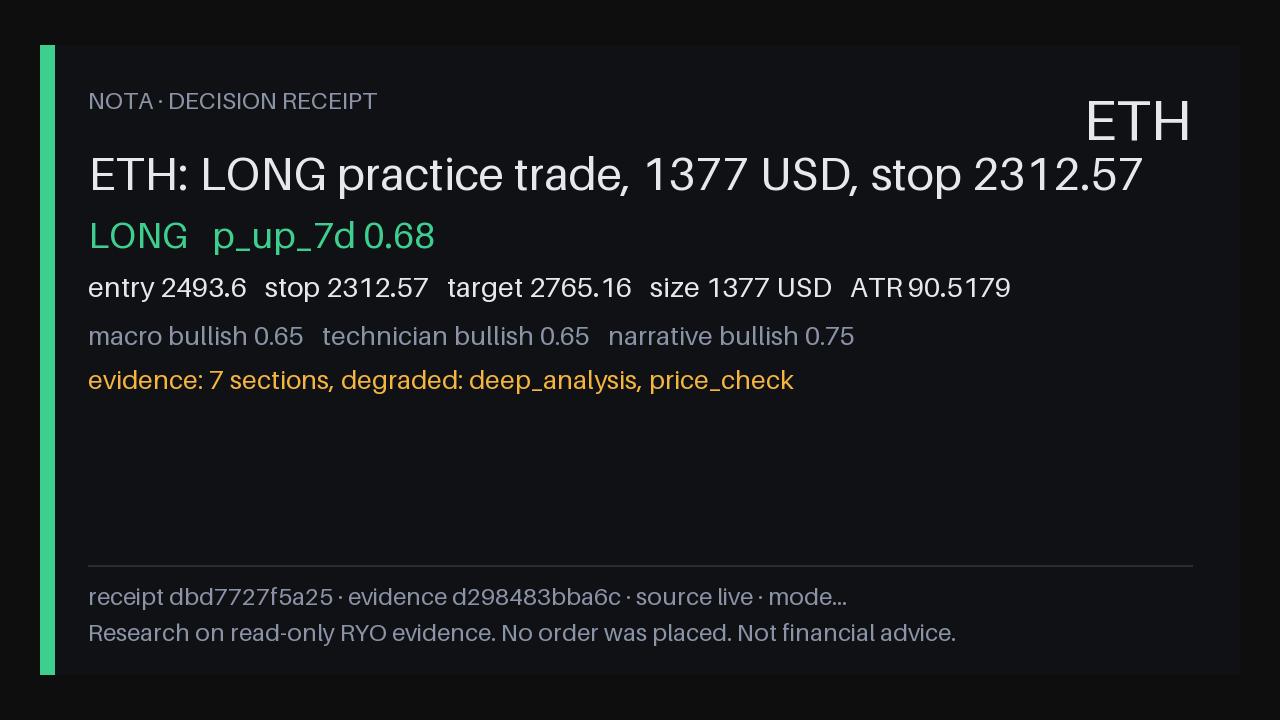
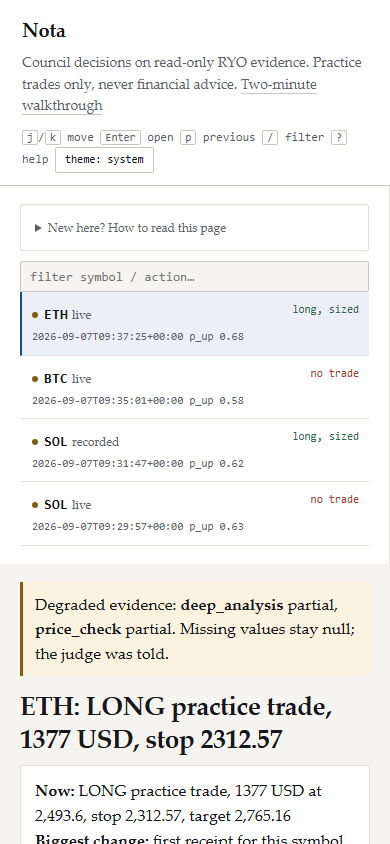
Screenshots are generated from the shipped demo ledger by scripts/screenshots.py.
Watch it instead: nota-ryo.vercel.app/demo — a narrated
3:36 walkthrough with a clickable transcript, or the bare file at /demo.mp4.
How a decision is made
gather ──────────► council ──► judge ──► risk (pure ATR math) ──► receipt ──► ledger ──► notify
 5 RYO tools        macro       weighs      entry / stop / target      id = hash(evidence,   Telegram
 + own skills       technician  opinions    or Blocked when price       model, prompts)      Discord
 (price_check,      narrative   by Brier    or ATR is missing
  voices, news)                 weights
- Evidence pack:
market_overview,monitor_market_sentiment_shift,deep_analysis,analyze_token,compare_tokens(the token against BTC/ETH peers).scan_marketdrivesnota scan, RYO's recommended funnel;--direction negativesends itsfilter_directionto shortlist losers for a short, and a decision on a scanned token keeps its own scan row (rank, 24 h change, turnover, momentum score,established_asset, RYO's reason) as ascansection inside the hashed pack. A failed tool becomes a section with statuserror; the pack still exists. Own skills are added as further sections (price_check,technicals_check,positioning_check,liquidityandcrowd_oddsby default,narrative_signalwith--voices,news_checkwith--news). - Council: three agents (macro, technician, narrative) each return a stance, a
probability, and citations as dotted paths into the evidence. Citations that point at
a missing or null value are dropped in code (after normalising
x[0].ytox.0.y) and the opinion is downgraded. - Third-party text is data, not instructions: post text from
narrative_signaland headlines and snippets fromnews_checkreach the council wrapped as{"untrusted": ...}with control and bidi characters stripped, flaggedinjection_suspectwhen they read like "ignore your rules", and every agent is told such text is evidence to weigh, never a request to follow. RYO's token-profile prose (about 2.7 KB, repeated indeep_analysisand in everycompare_tokensrow) is shown once, to the narrative agent; everyone else sees its status and missing inputs at the same paths, which cuts the technician's prompt by more than 30% (promptsv4). Promptsv5give the macro agentliquidity(stablecoin supply and chain TVL); no agent seescrowd_odds, which is kept as the market's price to score the judge against. - Judge: weighs opinions by each agent's historical Brier score and decides long / short / no_trade.
- RYO's own plan is evidence, not an instruction:
deep_analysis.data.trade_plancarries RYO's ATR preview (entry, stop, targets, multiplier, method). Nota sizes independently and then reports the gap on the receipt: on the shipped ETH call, RYO stops at 2357.83 on a 1.5× ATR while this sizing uses 2.0×, so the stop sits 1.8% of entry lower and the first target 5.4% further, both in the same direction. RYO'ssqueeze_riskandliquidation_pressuresit beside that comparison. - RYO's call on every receipt: each receipt records
ryo_view(deep_analysis's call, key driver, what would change it, confluence state, analyze_token's verdict, compare_tokens' pick) andagrees_with_ryo(long against constructive/bullish/accumulate, short against cautious/bearish/avoid), printed as "RYO said: constructive (confluence CONFIRMED) - council: long, agrees". Both come from the hashed pack, so replay compares them; receipts stored before they existed still replay identical./api/scores.vs_ryoand the dashboard's "Nota vs RYO" line answer whether the council beats RYO's own call: both hit rates over the scored calls where each took a direction. - Risk: a pure function. Stop = 2×ATR(14), target = 3×ATR, size from 1% account risk,
capped at 20% of the account. RYO's own derivatives
vetoblocks the practice trade ("RYO derivatives veto: ") unless the positioning gate withheld it. No price or no ATR means Blocked, never a guessed number, and so does an ATR big enough to put the stop or target at or below zero: on an instrument that volatile the fixed-multiple rule does not apply, and a receipt must not print a negative price. - Replay: LLM outputs are cached by
(evidence hash, role, prompt version, model).nota replay <id>reproduces the receipt exactly;--freshre-asks the model and prints the drift honestly. The dashboard's "Verify replay" button does the cached check only. - Calibration:
nota resolve --allscores every decision whose seven-day horizon has passed (Brier per agent) against the OKX hourly close at the horizon, however late the cycle runs; when OKX cannot give it, the current RYO price or exchange median stands in, labelledlate:<hours>h:. Calibration tables count only outcomes that reached the horizon, report how many of their calls are independent (one per token per week), and stay unreadable until 20 are. The judge's weights move towards each agent's Brier only as n/(n+20), so five scored calls cannot swing them. Two baselines sit beside the Brier: the token's own base rate (vs_base_rate) and, harder, the prediction markets' P(up) at decision time (vs_base_rate.vs_market, "Nota vs the crowd" on the dashboard): the judge's Brier against the market's on the same resolved calls. - Autonomy:
nota watch SOL,BTC --every 3600 --notifydecides on a schedule, resolves matured decisions, and posts each new receipt to Telegram / Discord.--scan-top 3lets the loop pick its own candidates fromscan_marketevery cycle. - Simulated data never trades: when RYO marks the primary evidence
data_mode: simulated, sizing is blocked and the receipt says so. - Transport: REST (
/tools/{tool}/call) by default, or MCP JSON-RPC (tools/list,tools/callon the same base URL) withRYO_TRANSPORT=mcp. The MCP client does theinitialize+notifications/initializedhandshake once per client, keeps RYO'sserverInfoand protocol version, sendsAccept: application/json, text/event-streamand reads an SSE reply as well as a JSON one.nota healthshows whoami, days until the key expires, the handshake and the live catalog, checks every argument Nota sends against RYO's published input schemas (required keys, unknown keys, enum values) and lists the published arguments Nota does not use;nota health --strictexits 1 on any of those problems or a key expiring within 14 days.
The public surface is treated as public
/api/skills/<name>/invoke and POST /mcp are unauthenticated on purpose, so they are written for
strangers:
- A voice id goes into an outbound URL, so it is validated first.
../../evilused to resolve tohttps://t.me/evil, which handed a caller the path on the target host; with redirects followed that is a step towards making this server fetch somewhere of their choosing. Handles are letters, digits, underscore, dot and hyphen, up to 64 characters, and anything else is refused before a request is built. - Every skill argument is checked against the skill's own declared schema in one place
(
nota.skills.invoke), which REST, MCP and the CLI all go through: wrong type, a value outside an enum, a non-finite number, a string over 64 characters (500 for a news claim) or an array over 20 items is a 422, a JSON-RPC-32602, or a CLI usage error, never a 500. A symbol must be 1-15 letters or digits before it can reach an exchange URL, a prompt or the ledger, so../xorBTC?xnever leaves the process.GET /api/decisionstakeslimitfrom 1 to 200, and a backing handle is one line:@Abcandabcare the same backer,abcis refused. tools/callover MCP is metered per address exactly like the REST route, 60 units an hour, because it reaches third-party APIs. A call costs roughly the fetches it makes: one unit for a price or technicals check, two fornews_verify, one per voice fornarrative_convergence(so a 20-voice call is 20, not 1).initialize,tools/list,resources/*and the ledger-onlyverdict_track_recordstay free: they touch nothing outside the process. A batch is checked whole before any of it is charged, and a refusal is a JSON-RPC429withRetry-After. WithDATABASE_URLset the count lives in Postgres (ahitstable), so every serverless instance draws on one budget instead of each granting its own; without it the count is per process, pruned as it goes and cleared if it ever holds 10,000 addresses.- A Telegram, X or Bluesky voice and each of the four RSS feeds is fetched at most once per five minutes per process; repeats come from that cache, and a failed fetch is never cached.
- Every response carries
X-Content-Type-Options: nosniff, aReferrer-Policy, aPermissions-Policyand aContent-Security-Policythat allows this origin only: fonts are self-hosted and no page loads a third-party script. It still permits'unsafe-inline'for scripts and styles, because the pages keep their behaviour inline; that is weaker than a nonce policy against injected script, which is why every value the pages insert is escaped first./docsis left out because Swagger UI comes from a CDN. The read-only JSON under/api/and/r/,llms.txt, the feeds, the captions and the agent card answer any origin, and the skill invoke route answers its CORS preflight, so a page elsewhere can call a skill;/mcpkeeps itsOriginallowlist. Every page answersHEADwith the headersGETwould send, and/r/<id>for an id that is not in the ledger is a404withnoindex. /api/healthprobes RYO at most once a minute per process (one retry on a timeout) and says when it did (checked_at), where a backing would be written (backing:postgres,ledgerornone), and how fresh the ledger is: the newest lock, receipt and settlement, andstale: truewhen neither a lock nor a receipt has been written for 36 hours.- A JSON-RPC batch is capped at 25 messages and a body at 1 MB (checked while it streams, so a
chunked upload cannot slip past), a body nested too deep to parse is a
-32700, andOriginis validated on every MCP request as the transport spec's security section requires. Every refusal, transport-level ones included, comes back as a JSON-RPC error body. - A message without an
idis a notification: it gets202and does nothing, so it cannot run a tool or spend the budget. Params of the wrong JSON type are a-32602, a skill that fails in an unexpected way is anisErrorresult naming the tool (the detail goes to the server log, not the caller), and skills run in a worker thread so one slow source never stalls the endpoint. - Backing is capped at 30 an hour per address. It used to answer 503 on the hosted deployment, which
meant the one place anyone could try it was the one place it did not work: a serverless filesystem
cannot be written, and the ledger there is a snapshot. Backings now go to Postgres when
DATABASE_URLis set (nota/backings.py) and to the ledger's own table otherwise, so nothing local needs a database to run or to test. The write is a singleINSERT ... ON CONFLICT (decision_id, handle) DO UPDATE: reading a map of handles, changing one and writing it back would drop a stance whenever two people backed at the same moment, and a public record that silently loses someone's vote is worse than no public record. The 503 is still there for the case it was written for - nowhere to write at all. - A handle cannot be taken over. There are no accounts, so the first backing under a handle claims
it and returns an
edit_tokenonce; any later backing under that handle must carry the token or gets a409. Only the token's SHA-256 is stored, and it is compared in constant time. The dashboard keeps the token in the browser that claimed the handle.
Honesty rules this code enforces
- Every number in a receipt carries its source path, RYO
as_of,data_modeand trace id. null/unavailableis never converted to 0 (Envelope.get,first_present, risk, every skill).- Recorded fixtures keep RYO's original
as_ofanddata_modeand are labelledsource: recorded. The RYO envelopes undertests/fixtures/are real answers too (recorded 2026-09-19, plus the 2026-09-07 set intests/fixtures/recorded_0907/where SOL's derivatives lane was down, and RYO's real refusals intests/fixtures/ryo_errors/). Only evidence whose source isliveorrecordedcan size a practice trade or enter a Brier, base-rate, source or reliability score; anything else is shown but never counted. There is no fake-LLM mode in the CLI. - The RYO surface is read-only; practice trades exist only in
nota.db. - A receipt says what it cost: model calls, cache hits, prompt and completion tokens, the provider's
own billed figure, and wall time. Every one of those is what the provider reported, never derived
from a price table this repository would have to keep correct - a figure that was not reported
reads "not reported", and one silent call makes the whole total unknown rather than smaller.
spendis deliberately outside the replay comparison: a cached rebuild spends nothing, so the field is a measurement, not a reproducibility claim. - External sources say what they cannot do: Venice web search carries no dates, the X mirror is unofficial, RSS feeds that fail are listed, exchange prices never replace RYO's value.
Run
uv sync
cp .env.example .env            # RYO_MCP_KEY + an LLM key (Anthropic, or NOTA_LLM=openai for Venice/OpenRouter)
uv run nota health             # MCP health (no key) + whoami, key expiry, handshake, catalog check (with key)
uv run nota health --strict    # the same, exit 1 on an expiring key or an argument RYO would refuse
uv run nota llm-check --llm openai   # one 1-token completion; exit 2 when the key or balance is refused
uv run nota decide SOL         # live evidence + price cross-check, council, receipt
uv run nota decide SOL --voices tg:WatcherGuru,bs:decrypt.co,bs:unusualwhales.bsky.social --news --notify
uv run nota scan --top-n 5 --decide-top 2      # scan_market -> analyze_token -> council
uv run nota scan --direction negative          # RYO's losers shortlist, the funnel for a short
uv run nota watch SOL,BTC --every 3600 --notify
uv run nota replay <id>        # identical: True
uv run nota replay <id> --fresh
uv run nota resolve --all      # after 7 days: Brier scores per agent
uv run nota stamp              # OpenTimestamps: anchor new locks and receipts, upgrade proofs pending over 3 h
uv run nota export snapshot.json        # receipts + scorecard as one JSON (the ledger cycle writes data/snapshot.json)
uv run nota merge-db other.db  # add another snapshot's rows this ledger lacks (the cycle's push-conflict path)
uv run nota scores
uv run nota record SOL         # capture all six live tools into fixtures/recorded (all or nothing)
uv run nota decide SOL --source recorded   # replay those recordings without a RYO key (the council still needs an LLM key)
uv run nota positions                      # open practice positions vs the latest independent price
uv run nota serve                          # http://127.0.0.1:8000 overview, /app dashboard, /mcp
uv run nota skill spec                     # Track 3 definitions
uv run nota skill run price_crosscheck '{"symbol":"SOL","reference_price":150}'
uv run pytest -q
Multi-KOL agent (Track 1 spotlight)
The hackathon's spotlight idea, end to end: pick up to 20 crypto voices, let Nota find the tokens they name with sentiment, conviction and urgency, and open a practice position only when trusted voices converge and every rule you set passes.
uv run nota kol --voices x:handle,tg:WatcherGuru,bs:decrypt.co --min-voices 2 --min-sentiment 0.3 \
  --min-conviction 0.2 --tokens SOL,ETH --account 10000 --risk-pct 1 --max-positions 3
uv run nota kol --voices ... --watch --every 3600   # run every hour; each run is stored
uv run nota kol-replay <id>                         # identical: True, from the ledger alone
Or open /kol in the browser (form, per-voice coverage, rule trail, position), or call
POST /api/kol/run with {"voices": [...], "rules": {...}, "limits": {...}}; GET /api/kol lists
stored runs and GET /api/kol/<id> replays one.
- Reading. The voices go through the
narrative_convergenceskill.x:voices try X's own syndication endpoint, then Tavily search; a voice read through Tavily is markedvia tavily_search, coverage partial, and an unreadable voice isunavailablewith its reason. - Rules (
nota/kol.py). Code, not a model. Per token: the voices converge (two or more with a stance, all the same sign); voices with a stance >=min_voices; |sentiment_mean| >=min_sentiment; conviction_mean >=min_conviction; optionally urgency_max >=min_urgencyand the token in your allowed list. Every rule is stored as{rule, value, threshold, passed}, the value read straight from the envelope. A missing value fails its rule and staysnull. - Position. A fired signal goes through the same
nota.riskcode as the council: RYO'sdeep_analysisgives price and ATR(14), the stop is 2 ATR and the target 3 ATR away, and size follows your account and risk %. No RYO evidence, no ATR, a RYO veto, a token already held, ormax_positionsreached: the signal stays, the trade is refused, and the reason says which. RYO is asked only about tokens that could fill a free slot. - Replay. A run is stored in the ledger's
kol_runstable with its narrative envelope, its rules and limits, the holdings it started from and its RYO evidence packs, sokol-replayre-derives every decision with no network and no key. - Hosted demo. The snapshot is read-only, so
/api/kol/runthere returns the run unstored and says so. It is throttled per address by what it fetches (one unit per voice, two perx:voice, one per possible RYO read).
Skills (Track 3)
All nine return RYO's public envelope field for field (docs/skills/SKILL-SPEC.md) and are
served on RYO's own skill paths, so plugging them into RYO is a route registration, not a port:
GET /api/skills/ (SkillDefinition list), GET /api/skills/{name}, and
POST /api/skills/{name}/invoke taking SkillCallRequest {name, args, conversation_id} and
returning SkillCallResponse {name, status: success|error, result, latency_ms, xp, guard_decision}.
The dashboard's "Run a skill" panel builds its form from those definitions and shows the envelope.
contrib/positioning_check/ is the flagship skill packaged as a drop-in for RYO's own backend:
no Nota imports, a FastAPI router to include, and its own offline tests (see its README).
contrib/move_base_rate/ packages move_base_rate the same way: one OKX source, same router and test layout.
narrative_convergence: up to 20 voices (tg:public Telegram previews,bs:Bluesky public API,x:through X's own public syndication endpoint, the one that serves embedded timelines, with a Tavily fallback), VADER sentiment plus a crypto lexicon scored per token on the clauses that name it ("BTC pumping while ETH dumping" is two opposite reads), whole-word conviction and urgency, and convergence: two or more voices with a net sentiment, all of the same sign. Only known majors count as tokens, so$HODLor "CEO" is not a call. Silence isnull, not 0. Nitter, whichx:used to go through, was served cease-and-desist letters in August 2026 and its public mirrors went dark, so that reader was advertising a source that could not answer; syndication is keyless, dated and still open, and every failure is reported asunavailablerather than guessed. One measured limit worth knowing before you try it: syndication throttles hard, and it has tightened. It hit data-centre addresses first, sox:came backunavailablefrom the hosted demo while reading fine from an ordinary connection; as of 2026-09-10 an ordinary connection getssyndication HTTP 429too. Treatx:as best effort andtg:/bs:as the dependable readers - those two answer from both. SettingTAVILY_API_KEYturns the throttle into a search-backed fallback, which the envelope then labels as undated; without that key the warning says so in as many words.news_verify: dated headlines from CoinDesk, Cointelegraph, The Block and Decrypt RSS, plus Tavily or Venice web search for breadth; counts independent domains and attaches RYOanalyze_tokencontext. Headlines match on the claim's distinctive words, not on "Bitcoin" and "price", and a headline that leans the other way is counted against the claim, so a story can come backdisputed. With no search key the headlines still decide, and the status sayspartial.price_crosscheck: keyless CoinGecko, Coinbase, Kraken, Binance (public data mirror, USDT as the USD proxy) and DefiLlama spot prices, median, spread, and deviation of a reference price (RYO's) from the exchanges, plus the alternative.me Fear & Greed index against RYO's reading. A source more than 2% from the others is markedoutlierand left out of the median, so a CoinGecko symbol search that lands on a different coin cannot move the price.technicals_crosscheck: RSI(14), ATR(14) and 1d/7d/30d performance recomputed with Wilder's method from 200 closed UTC-day candles (OKX, else Binance, else CoinGecko 4-hour OHLC aggregated to days, which warns that 30 days do not converge; today's unfinished candle is never used), with the deviation of reference values (RYO'stechnicals.rsi_14/atr_14) from the independent calculation. The Technician sees it astechnicals_checkon every decision.positioning_check: the derivatives gate above, plus OKX's perp premium (the funding rate sits at the 1 bp interest component and says nothing), open-interest change in coins, the long/short account ratio as a percentile of its last 100 hours, and Hyperliquid's premium as a second venue.premium_consensusis one side of spot on every venue orvenues_disagree, never an average, with one plain sentence in English and Japanese; the headline quotes both venues. Called without RYO's block, it asks RYO'sdeep_analysisitself (whenRYO_MCP_KEYis set) and compares it with today's scorecard locks. For BTC and ETH it adds Deribit's DVOL: the options market's implied 7-day move, and withatr_stop_pcta warning when a stop sits inside that normal noise. Other tokens have no DVOL and get none.move_base_rate: how often this token reached (or closed beyond) k ATRs within h days, counted on ~400 days of OKX UTC candles restricted to days in today's volatility tercile, with the number of independent days and a time-split holdout that warns when the rate has drifted (its tercile cuts come from the older days only, so the fit never sees the holdout). Given RYO'satr_14_pctit measures in RYO's ATR (0.91-0.98 of a Wilder ATR from OKX, ratio printed). Every scored decision also carries this base rate, and/api/scores.vs_base_rategives each agent 1 - Brier / Brier(base rate): above zero it knew something the calendar did not.verdict_track_record: the scorecard's settled record for a token, by verdict and confluence state, with denominators, the plans whose verdict leans against their own direction (a long under a cautious verdict or a short under a constructive one), and the latest locked verdict's trace id.liquidity_check: DefiLlama, keyless: the 7- and 30-day change of the total USD stablecoin supply (fresh buying power arriving or leaving) and of DeFi TVL on the token's own chain, each with the date of its last row. BTC and tokens without a chain of their own get no TVL, with the reason, never a neighbour's. The macro agent reads it asliquidity.crowd_odds: the prediction markets' implied P(higher than now) at the horizon. Polymarket's " above ___ on " ladder expiring within a day of now + 7 d (BTC, ETH, SOL, XRP), else Kalshi's KXD ladder (also DOGE). Only two-sided books at most 10 cents wide count, so a fresh ladder's 0.5 placeholders are never read; prices are made monotone in the strike and interpolated at spot. No readable ladder ismarket_p: null, never a coin flip. Stored in every pack, shown to no agent, and scored against the judge.
Nota is also an MCP server (Track 3)
Nota is an MCP client of RYO. It is also an MCP server, so RYO, Claude Desktop, Cursor or any other MCP host can call the nine skills directly with no wrapper:
// claude_desktop_config.json, or any MCP client that speaks Streamable HTTP
{ "mcpServers": { "nota": { "url": "https://nota-ryo.vercel.app/mcp" } } }
curl -s https://nota-ryo.vercel.app/mcp -H 'content-type: application/json'   -d '{"jsonrpc":"2.0","id":1,"method":"tools/list"}' | jq '.result.tools[].name'

curl -s https://nota-ryo.vercel.app/mcp -H 'content-type: application/json'   -d '{"jsonrpc":"2.0","id":2,"method":"tools/call","params":{"name":"technicals_crosscheck","arguments":{"symbol":"SOL"}}}'
It serves all four MCP primitives, not just the easy one:
- tools:
tools/listandtools/callfor the nine skills, eachinputSchemagenerated from the same definition the REST route and the dashboard form use. - resources:
resources/list,resources/templates/list(nota://receipt/{id}) andresources/read, which returns a receipt as markdown plus its own JSON. A client that never touches this project's HTTP API can still list its decisions and read one. - prompts:
prompts/listandprompts/get.audit_a_tokentells the caller's model to cross-check RYO against the independent sources and carries the honesty rules with it, including that a null stays null.read_a_receiptwalks a stored decision. - completions:
completion/completeoffers the receipt ids and symbols this deployment actually holds, so a client never has to guess one, and only for an argument the referenced prompt or template declares.
Each tool carries a title, annotations (readOnlyHint: true, destructiveHint: false) and an
outputSchema, the RYO envelope's own JSON Schema, so a client knows before calling that nothing is
written and what shape comes back. Lists page with an opaque cursor 50 at a time.
It also ships an MCP Apps view. Every tool links ui://nota/receipt in _meta.ui.resourceUri,
and resources/read on that URI returns one self-contained HTML page (nota/static/mcp_app.html,
text/html;profile=mcp-app, empty CSP allow-list: it loads nothing). A host that renders MCP Apps
runs the ui/initialize handshake with it and pushes the tool result in; the view draws the
envelope as a stamped card: status, as_of, availability per source, headline, key points and
warnings, all written as text, never as markup.
Nota is published in the official MCP registry as io.github.PugarHuda/nota (version 0.1.0,
2026-09-10; server.json here is 0.2.0, which describes the scorecard and the derivatives gate and
takes effect once republished), so a client can find it without being handed the URL:
curl "https://registry.modelcontextprotocol.io/v0.1/servers?search=io.github.PugarHuda/nota".
server.json at the repository root is this server's entry for the official MCP registry, and the
deployment serves it at /.well-known/mcp/server.json and /server.json, so the description and the
endpoint it names cannot drift apart. Two rules the registry enforces and a test here mirrors: the
description is capped at 100 characters, and a published version is immutable - every republish
needs a new version, so changing anything in that file means bumping it. Publish with
mcp-publisher login github && mcp-publisher publish from the repository root; mcp-publisher validate checks the file against the live registry without publishing.
GET /llms.txt follows the llms.txt convention: one generated page telling an agent what is here,
how to call the MCP and A2A endpoints, the scorecard, which skills exist and which receipts the
ledger holds. Its page list is filtered by the routes the app really serves, so it cannot drift
from them.
A2A. Nota is also an Agent2Agent 1.0 agent. /.well-known/agent-card.json is its Agent Card
(the nine skills with tags and an example call each, one JSON-RPC interface, no streaming, no push)
and POST /a2a takes SendMessage with the header A2A-Version: 1.0 (no header means 0.3, which
is refused with VersionNotSupportedError, as the spec says). The message carries a data part
{"skill": ..., "args": {...}}, or text such as price_crosscheck SOL; the call goes through the
same invoke checks as REST and MCP, and the answer is a completed task whose artifact is the
envelope. Bad arguments are -32602 with a google.rpc.BadRequest detail. Every task finishes
inside the request, so no task is stored: GetTask answers TaskNotFoundError and streaming,
cancel and push configuration answer UnsupportedOperationError. It shares /mcp's Origin
allowlist, 1 MB body cap and per-address skill budget.
Open data and discovery. /feed.xml (Atom) and /feed.json (JSON Feed 1.1) carry the newest
50 receipts, each with its verdict, degraded sections and, once resolved, the outcome and the
judge's Brier score, plus every settled scorecard plan. /api/outcomes.csv has one row per resolved
decision (each role's p_up_7d, the base rate, what happened, Brier per role). /robots.txt and
/sitemap.xml (every page, both languages as hreflang alternates, every receipt) are for
crawlers, and every page's head names its canonical URL, an absolute og:image and the feeds.
One endpoint, POST only, stateless. It negotiates the protocol version the client asks for
(2026-07-28, 2025-11-25, 2025-06-18, 2025-03-26 or RYO's own 2024-11-05, and the newest
when it asks for one it does not know), answers server/discover with the versions, capabilities and
server info, refuses an MCP-Protocol-Version header it does not speak with a 400 and the spec's
UnsupportedProtocolVersionError (-32022, listing what it does), validates the Origin header
against DNS rebinding as the transport spec requires, answers a batch with one response per request,
returns 202 Accepted with no body when the body holds only notifications, and answers 405 to GET
and DELETE because there is no stream to open and no session to delete. Each tool's inputSchema is
generated from the same skill definition the REST route and the dashboard form use, so the three can
never drift apart. tools/call returns the RYO envelope twice: as text for clients that only read
text, and as structuredContent for clients that parse.
Dashboard (Track 2)
nota serve exposes a read-only API over the ledger (/api/decisions, /api/decisions/{id},
/api/decisions/{id}/replay, /api/positions, /api/scores, /api/health, exports
/r/{id}.json and /r/{id}.md, OpenAPI at /docs) and a single-page dashboard. A receipt read
from /api/decisions/{id} also carries requests (the exact arguments each evidence section was
called with) and audit (Nota's ATR, RSI and price beside RYO's, with each skill's warning
threshold), both read from the stored evidence pack; the landing's audit table is filled from it and
holds no number of its own. List rows carry availability and failed_sections (RYO sections in
error or unavailable), which is how the landing picks the receipt its failure panel shows.
Documentation truncated — see the full README on GitHub.
Reviews
No reviews yet
Be the first to review this server!
More Developer Tools MCP Servers
Rea
Freeby Morluto · Developer Tools
Reverse engineer anything from your terminal or agent with one CLI and MCP server.
Paperclip
Freeby Paperclipai · Developer Tools
Trending hip-hop artist momentum scores across four cultural dimensions.
Git
Freeby Modelcontextprotocol · Developer Tools
Read, search, and manipulate Git repositories programmatically
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
MCP Marketplace
Freeby mcp-marketplace · Developer Tools
Search and install MCP servers from inside your AI client.
mcp-creator-python
Freeby mcp-marketplace · Developer Tools
Create, build, and publish Python MCP servers to PyPI — conversationally.