
Server data from the Official MCP Registry
Local speaker-attributed transcription and meeting search for Apple Silicon. Audio stays on the Mac.
About
Local speaker-attributed transcription and meeting search for Apple Silicon. Audio stays on the Mac.
Security Report
Valid MCP server (1 strong, 1 medium validity signals). 1 known CVE in dependencies Package registry verified. Imported from the Official MCP Registry.
3 files analyzed · 2 issues found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Permissions Required
This plugin requests these system permissions. Most are normal for its category.
What You'll Need
Set these up before or after installing:
Environment variable: WHOSAID_WORKSPACE
How to Install
Add this to your MCP configuration file:
{
  "mcpServers": {
    "io-github-sblattj-whosaid": {
      "env": {
        "WHOSAID_WORKSPACE": "your-whosaid-workspace-here"
      },
      "args": [
        "whosaid==1.15.2",
        "whosaid-mcp",
        "whosaid"
      ],
      "command": "uvx"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
whosaid
Local, speaker-attributed transcription for Apple Silicon — who said what, on your Mac, nothing leaves the machine.

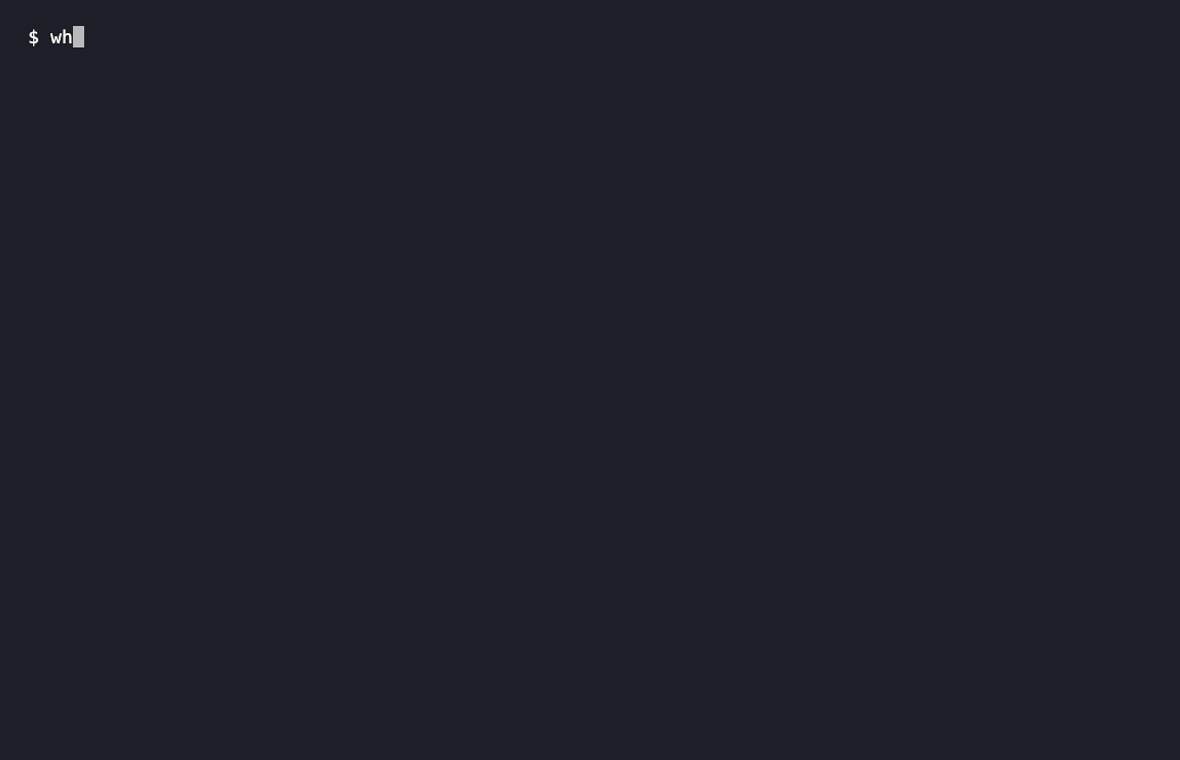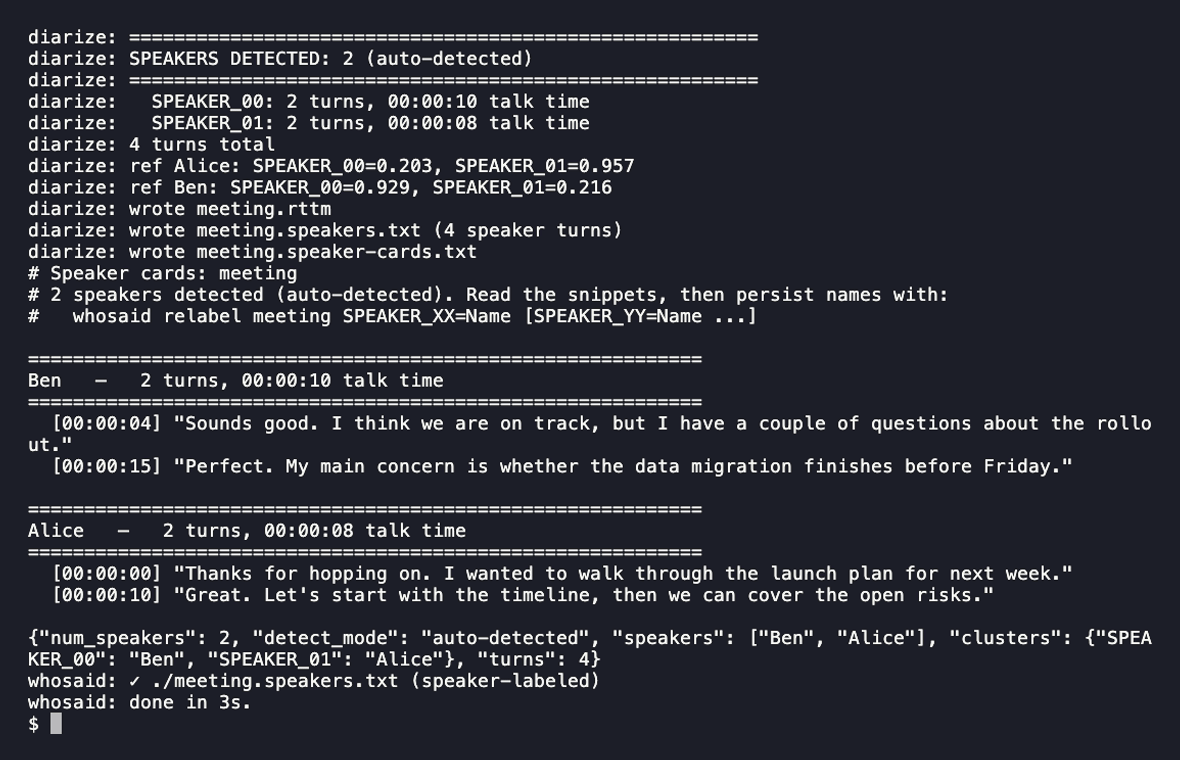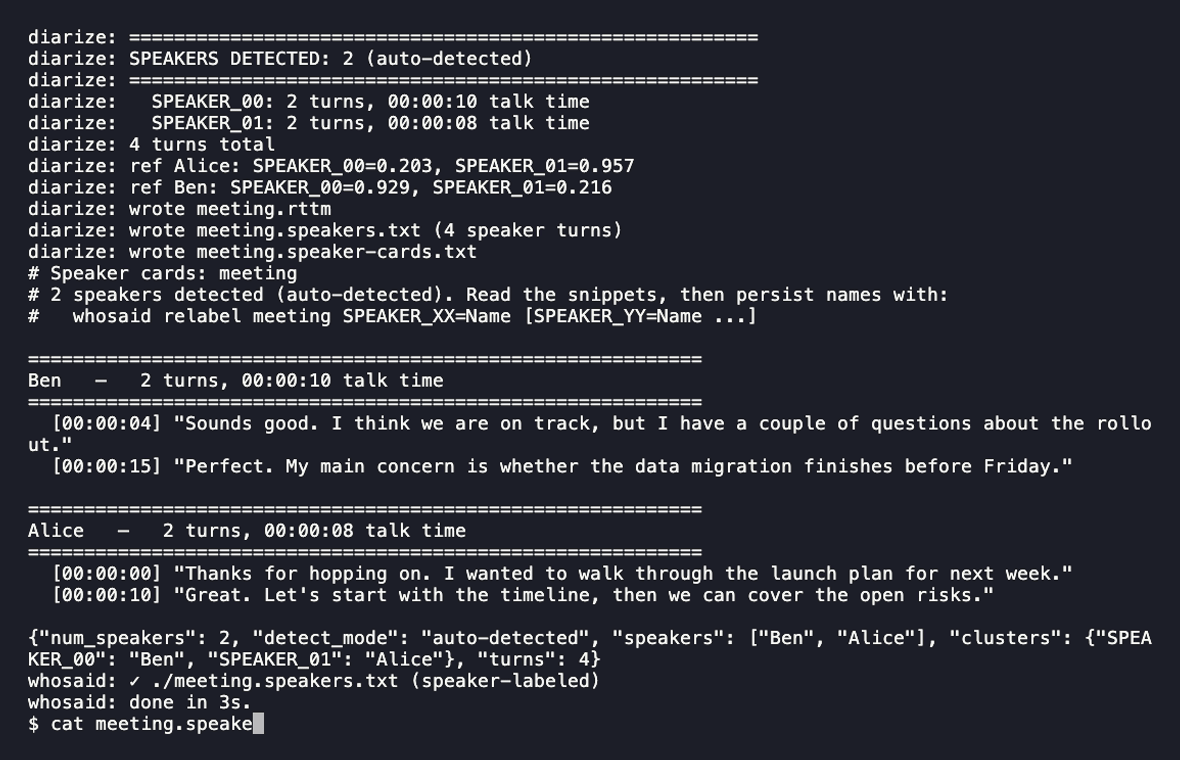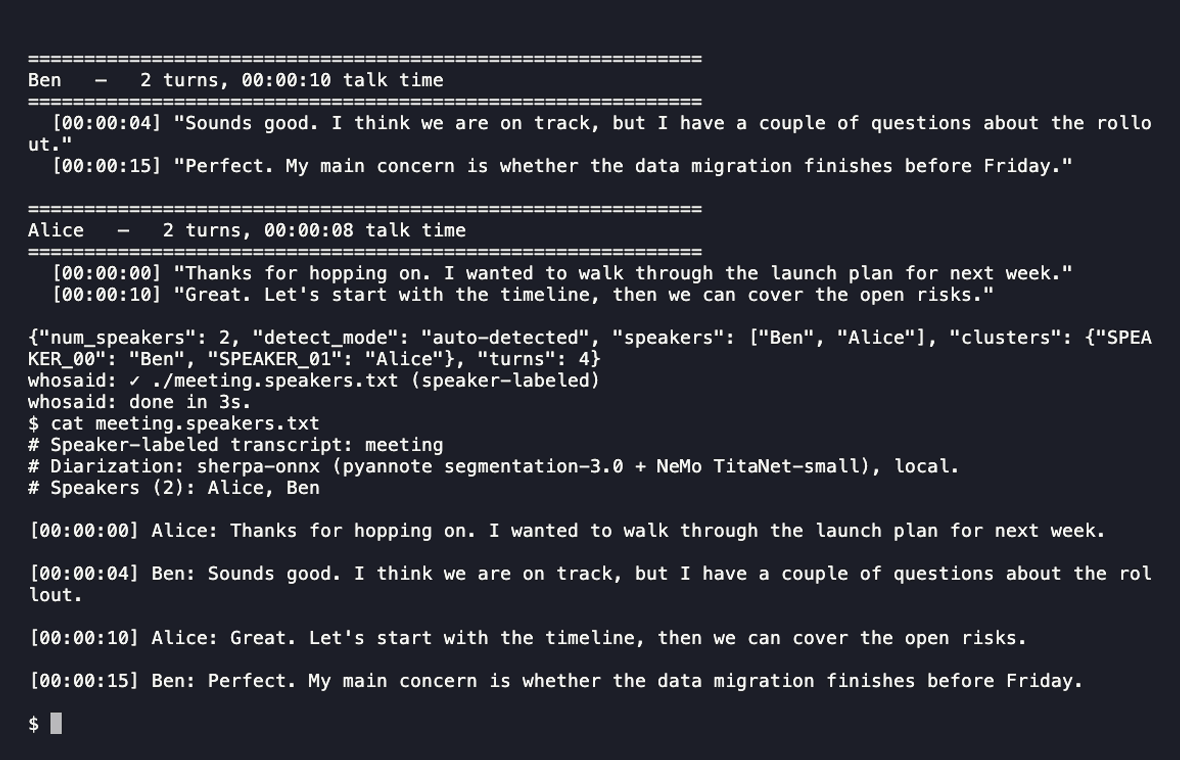
whosaid pairs Whisper speech-to-text with speaker diarization to turn a meeting,
interview, call, or podcast recording into a transcript that says who spoke when — running fully
offline and on-device on an Apple Silicon Mac, with no cloud service, no API keys, and no Hugging
Face token. Think of it as whisper + speaker labels + voice-based speaker recognition, in one
command.
Example output (meeting.speakers.txt):
[00:00:04] Alice: Thanks for jumping on, I know it's late for you.
[00:00:11] SPEAKER_01: No problem at all, happy to make it work.
[00:00:19] Alice: Let's start with the roadmap for next quarter.
[00:00:27] SPEAKER_01: Sounds good, I've got a few updates on that.
Why whosaid
- Meetings, interviews, calls, podcasts — get a transcript where every turn is attributed to a person, not just a wall of text.
- Privacy by construction — audio, text, and voice embeddings never leave your Mac. The only
cloud step is one you opt into:
[summarizer] engine = "claude"sends each transcript's text to Anthropic to draft action items. Leave it unset and nothing is sent. - Your name on your own lines — a one-time ~45s voice enrollment teaches whosaid your voice, so
your turns read as your name instead of
SPEAKER_00. - Tells you how many people spoke — the number of distinct speakers is auto-detected and reported up front, with per-speaker turn counts and talk time.
- Speaker cards to identify who's who — for every speaker, whosaid writes a card of that voice's most representative snippets, so you can read a few lines and know who was talking.
- Remembers people you name — identify a speaker once with
whosaid relabel, and their voiceprint is saved to a private local registry so they're auto-named in every future transcript. - Fast on long recordings — recordings over ~15 min are diarized in parallel windows and stitched back into consistent speakers by voiceprint, so an 80-minute meeting is minutes, not tens of minutes, recovering the same speakers as a single-pass run.
- No accounts, no API keys, no Hugging Face token — every model comes from an open, ungated source.
- Search everything you have recorded.
whosaid indexbuilds a local full-text (and, with Ollama, meaning) index over every transcript in a meeting workspace;whosaid searchfinds the turn,whosaid contextshows the minute around it, andwhosaid graphanswers who committed to what, when. See Search your meetings. - Hands-free from Voice Memos.
whosaid watch installputs a launchd agent on the Voice Memos folder (or any folder): stop recording, and a few minutes later the meeting is transcribed, summarized, and searchable. See Hands-free ingest. - Usable from an AI agent, too.
whosaid mcpexposes transcribe, relabel, doctor, and the read-only workspace search tools as MCP tools for Claude Code, Claude Desktop, Kiro, and other MCP clients, with the same local-only guarantee as the CLI.
How it compares
Looking for a MacWhisper, whisperX, or aTrain alternative? If you want speaker-attributed
transcription that runs fully offline on Apple Silicon and can put real names on voices — not just
SPEAKER_00 labels — that's the gap whosaid fills. Here's how it stacks up:
| whosaid | whisperX | plain mlx-whisper | cloud transcription APIs | |
|---|---|---|---|---|
| Speaker labels | Yes | Yes | No | Varies by provider |
| Names speakers by voice | Yes (enrollment) | No | No | No |
| Remembers speakers across meetings | Yes — persistent local voiceprint registry | No | No | No |
| Runs fully offline | Yes | Partial — needs a gated model download | Yes | No |
| Parallel diarization on long audio | Yes | No | — (no diarization) | Varies by provider |
| Needs an account / token | No | Yes — Hugging Face token for gated pyannote models | No | Yes — API key |
| Install weight | ffmpeg + uv, ephemeral environments | torch + pyannote + the full HF stack | mlx-whisper only | None (network client only) |
Quickstart
git clone https://github.com/sblattj/whosaid && cd whosaid   # get the code
./bootstrap.sh                                                # check deps, download models, install ~/.local/bin/whosaid
whosaid enroll                                                # ~45s reading a printed passage — teaches whosaid your voice
whosaid path/to/meeting.m4a                                   # transcribe + diarize + label -> meeting.speakers.txt (and friends)
If ~/.local/bin is not on your shell's PATH, add it or invoke the installed command by its
absolute path. WHOSAID_INSTALL_DIR=/another/bin ./whosaid install selects another install
directory. The installed command is a symlink to the checkout, so updating the checkout updates the
command without copying or duplicating the implementation.
whosaid's helper scripts need Python 3.11 or newer, because whosaid.toml is read with tomllib.
The launcher picks one interpreter: $WHOSAID_PYTHON if it is set, otherwise the first of python3,
python3.13, python3.12 and python3.11 on your PATH that is 3.11+, otherwise
uv python find '>=3.11'. It skips the stock macOS python3 (3.9) automatically. If no interpreter
qualifies, commands that run Python stop with an error; uv python install 3.13 fixes that.
whosaid doctor shows which interpreter was picked.
Homebrew is optional when uv, ffmpeg, and ffprobe are already installed. The launcher
and watcher search ~/.local/bin, ~/bin, and ~/homebrew/bin as well as the usual system
prefixes. Setup can install a pinned, checksum-verified Apple Silicon uv archive into
~/.local/bin. Homebrew FFmpeg installation requires a bottle; a nonstandard prefix will not
silently trigger a source build.
For a Mac without Homebrew, or one where no bottle is available, use:
./bootstrap.sh --build-ffmpeg
This builds pinned FFmpeg source into user-local ffmpeg and ffprobe executables. It needs
Apple's Command Line Tools (xcode-select --install if missing), compilation time, and free
disk space, but no administrator-owned install prefix or GPG installation. The source archive
is checked with macOS shasum against a checksum verified from FFmpeg's signed release.
Existing usable tools are retained. Setup then warms the Python environments and downloads
the models as usual.
Commands
| Command | What it does |
|---|---|
./bootstrap.sh [--yes] [--build-ffmpeg] (also whosaid setup) | Capability check, dependency install, model pre-download, and command installation. --build-ffmpeg selects the verified user-local source build when FFmpeg tools are missing. Idempotent — safe to re-run. |
whosaid install [--force] | Install/update the command symlink in ~/.local/bin (or WHOSAID_INSTALL_DIR). Refuses to replace an unrelated command, and refuses (unless --force) to install from a checkout under /tmp, /private/tmp, /var/tmp, or $TMPDIR — that symlink would dangle once the OS cleans the temp directory up. |
whosaid enroll [Name] | Records ~45s from the mic reading a printed passage, saves voices/<Name>.wav. See Speaker identity: enrollment clips vs. the registry. |
whosaid enroll <Name> --from FILE [--ss T] [--t D|--to T] [--force] | Extracts a clip from an existing recording instead of the mic (extract → verify → save, no interaction). --ss/--t/--to accept seconds or M:SS/H:MM:SS; same ≥15s/non-silent bar as mic enrollment. |
whosaid record [--label L] | Foreground mic capture to recordings/<timestamp>[-label].m4a, then transcribes automatically. |
whosaid record --app A [--no-mic] [--label L] | Capture one app's audio (Zoom, a browser, ...) through ScreenCaptureKit, plus the mic, to a stereo recordings/<timestamp>[-label].m4a (left = mic, right = the app), then transcribe it. A is a bundle ID, an app name, or a unique part of either; whosaid record --list-apps lists them. Needs macOS 15+, Xcode Command Line Tools (a small Swift helper, lib/record_app.swift, is built on first use into ~/.cache/whosaid) and Screen & System Audio Recording permission for your terminal. No virtual audio device. --no-mic records the app alone. With --me NAME (or $WHOSAID_OWNER), the voice heard only on the mic is named NAME and app-side voices never are. If macOS kills the capture it restarts in place. |
whosaid <audio>… [flags] | The default command: transcribe + diarize + label one or more audio files. --reuse-asr skips Whisper when <out>/<base>.json already exists and re-diarizes only (errors if the json is missing; not valid with --no-diarize). whosaid transcribe <audio>… is the same command written explicitly (matching the whosaid_transcribe MCP tool name). |
whosaid relabel <base> SPEAKER_02=Jane … | Put real names on clusters after reading the speaker cards. Rewrites the transcript + cards and saves each named voiceprint to the local registry for future transcripts — refusing (unless --force) to overwrite an existing registry entry the new cluster doesn't match (similarity below the match threshold, default 0.50). No re-transcription. |
whosaid relabel <base> SPEAKER_04=Alice --blend | Average the cluster into Alice's saved print instead of replacing it, to strengthen the print from a new recording. Same similarity guard as a normal relabel. See Speaker identity: enrollment clips vs. the registry. |
whosaid relabel <base> SPEAKER_04=Alice --no-save [--note TEXT] | Transcript-only label: renames the cluster in the transcript + cards and never writes to the registry. For a speaker the conversation makes obvious but whose cluster is a poor voiceprint — a long mixed cluster saved as that person would degrade their enrolled print. The label is kept in the sidecar (local_labels), survives relabel --auto and whosaid samples, and each card is marked Alice_Example (transcript-only label; registry untouched). See Speaker identity: enrollment clips vs. the registry. |
whosaid relabel <base> --auto [--forget NAME ...] [--fold-unknown] | Re-apply naming to an existing transcript with no assignments: re-runs registry matching + the absorb pass over the cached sidecar (and the voices/ enrollment clips, as transcribe does) and rewrites the transcript + cards. Picks up voices enrolled after the transcript was made, and drops auto-assigned names whose registry entry and clip are gone. --forget NAME (repeatable) clears NAME from this meeting first; it can come back if NAME is still enrolled and matches. Add --fold-unknown to repair anonymous phantom clusters in cached auto-diarization; it requires --auto and does not assign an identity. No re-transcription, no re-diarization. In a meeting workspace the base is transcript. See Speaker identity: enrollment clips vs. the registry. |
whosaid backfill <ws> [--dry-run] | Apply current registry names and roles to historical meetings, regenerate commitments, and refresh roll-up, worklists, search, graph, and wiki. Reports conflicts before changing meeting files. |
whosaid speakers export --out FILE | Export the private speaker registry to a new backup file, including voiceprints, roles, and metadata. |
whosaid speakers import FILE [--merge|--overwrite] | Restore a registry backup. An existing destination requires an explicit conflict policy; --overwrite replaces the entire registry. |
whosaid samples <base> [-o DIR] [--audio FILE] [--per-speaker N] [--seconds S] [--json] | Export one short representative WAV per speaker cluster — the longest diarized segment, clamped to --seconds (default 8) — so you can listen and confirm an identity before trusting an auto-label or enrolling. Cuts from the sidecar's own source.path, or an explicit --audio FILE for a sidecar written before that metadata existed. |
whosaid ingest <audio>… --into DIR [--action-items] [--engine E] [--index] | Transcribe a batch into dated meeting folders (idempotent by content hash). --engine picks the action-item summarizer, --index runs roll-up + index afterwards. See Meeting workspaces. |
whosaid roll-up <ws> [--action-items] [--refold MEETING[=OLD_MD]]... [--index] [--owner NAME|me] [--all-owners] | Rebuild the workspace index (_INDEX.md), audit, the deduplicated action-item and dev-commitments corpora, and the owner's ranked _WORKLIST-<Owner>.md; --index then rebuilds the search index too. --refold MEETING[=OLD_MD] (repeatable; implies --action-items, not valid with --rebuild) re-reads one already-folded meeting's regenerated action-items.md: ids, hand-set status and titles survive, owners follow the new speaker labels; OLD_MD is the meeting's previous file, so a hand-retitled item re-matches. |
whosaid reprocess <ws> [MEETING ...] [--dry-run] [--all] [--no-items] [--speakers N] [--min-speakers N] [--max-speakers N] [--expected-speakers A,B] [--match-threshold X] [--engine E] [--hook CMD] | Re-diarize meetings an older diarizer got wrong, reusing the existing ASR (transcribe --reuse-asr), keeping --no-save labels and hand edits, with backups in <ws>/_reprocess-backups/. --dry-run only reports. See Upgrading to 1.11. |
whosaid commitments <ws> [--owner NAME|me] [--all-owners] [--json] [-o FILE] | Print the ranked personal worklist (P1/P2/P3) on demand from the corpora, without a roll-up. See Dev-commitments. |
whosaid index <ws> [--no-embed] [--rebuild] | Build <ws>/_search.db (full text, optional embeddings, entity graph) and <ws>/_WIKI.md. See Search your meetings. |
whosaid search <ws> "<query>" [--mode exact|meaning|hybrid] [--speaker S] [--meeting M] [-k N] [--json] | Search every speaker-labeled transcript; each hit is a meeting, a timestamp, a speaker, and a snippet. |
whosaid context <ws> <meeting> <HH:MM:SS> [--before S] [--after S] [--json] | The verbatim turns around a moment, for reading a hit in place. |
whosaid graph <ws> items|item AI-NNN|person [Name]|prs|meetings|speakers|commitments [--json] | Entity views: action items with filters, one item's history, a person's commitments and asks, PR mentions, meeting coverage, talk share. commitments lists the unified CM table (--owner, --source transcript|action-items, --status filters) — one model behind the worklist, whosaid commitments, and the wiki since #23: the roll-up folds self-owned action-items bullets into the same CM-NNN corpus as the spoken clauses (one item, occurrences from both sources, the bullet's timestamp included), and graph build loads that corpus instead of re-parsing the bullets. |
whosaid wiki <ws> [--stdout] [-o FILE] | Regenerate <ws>/_WIKI.md from the graph. |
whosaid watch run|install|uninstall|status --into <ws> | Hands-free ingest of new recordings via a launchd agent. See Hands-free ingest. |
whosaid memos list|pull|delete "<title>"|shortcut-recipe | Voice Memos helpers that never touch the app's files or database. See Voice Memos helpers. |
whosaid doctor | Read-only environment report, including Ollama reachability and the index status of $WHOSAID_WORKSPACE. |
whosaid version | whosaid --version | whosaid -V | Print the installed version (plus a git describe suffix when run from a git checkout). |
Enroll from an existing recording
Already have a clip of the person speaking? Skip the mic and cut a reference straight from it:
whosaid enroll Alice --from meeting.m4a --ss 3:20 --t 20 # or --to 3:40
Meeting workspaces
One-off transcriptions are files; a recurring meeting series is a corpus. The meeting-workspace layer gives that corpus a home: every recording is transcribed into a dated folder, each meeting can carry generated action items and dev commitments, and one roll-up produces the index, the audit, a living action-item list, and the dev-commitments corpus across all of them — still entirely offline.
whosaid ingest — a batch into dated folders
whosaid ingest weekly/*.m4a --into ./meetings --folder-by created \
  --tz America/Los_Angeles --action-items
Every file is transcribed with the full set of whosaid <audio>… flags passed through, into
meetings/YYYY-MM-DD-HHMM/. The timestamp comes from the recording's own container
creation_time rendered in --tz (default UTC), falling back to the file's mtime — so folder
order reflects when meetings actually happened, not when you got around to copying the files.
Ingest is idempotent by source sha256: re-running a batch never re-transcribes or duplicates a
recording.
With --action-items, each meeting also gets an action-items.md. Generation is pluggable: the
hook command receives the speaker-labeled transcript on stdin, plus WHOSAID_SPEAKERS and
WHOSAID_TRANSCRIPT_PATH in its environment, and whatever it writes to stdout becomes the
markdown. Pass it per-run with --hook CMD, or set WHOSAID_ACTION_ITEMS_HOOK once. With no
hook, a skeleton is written instead and everything stays offline. Example hook — illustrative
only; any command that turns stdin into markdown works:
#!/bin/sh
# Drafts action items with a local Ollama model.
ollama run llama3.2 "List this meeting's action items as markdown bullets (Owner: task):"
You no longer need a hook to get a real draft: --engine ollama (or the default --engine auto, which uses Ollama when it is running) turns on the built-in summarizer described in
Action items drafted by a local model; --engine claude
is the opt-in cloud alternative. --engine
implies --action-items. Add --index and, once every file is in, ingest runs
whosaid roll-up <ws> --action-items and whosaid index <ws> for you, so the new meetings are
searchable in the same command:
whosaid ingest weekly/*.m4a --into ./meetings --engine ollama --index
With --commitments, each meeting also gets a commitments.md — the first-person commitments
you made in it (see Dev-commitments). Roles set once via
whosaid relabel --role decide whose cues count: tag your own voice self (and your manager
boss), and the extractor tracks what you promised, ranking boss-requested items higher.
--min-words N tunes the fragment filter for the run (fragments such as "I'll do that" are
dropped; default [commitments] min_words, else 2; 0 disables).
whosaid roll-up — index, audit, and the action-item corpus
whosaid roll-up ./meetings --action-items
- Coverage index —
_INDEX.mdholds one row per meeting (created date, duration, and whether it is transcribed, diarized, and has action items), plus a nothing-missing audit that flags orphan directories and stale manifest entries, and a recurring-topics section that surfaces themes appearing across meetings. Once any dev commitments exist, a one-line open/total count section is appended too. Both output paths are overridable with-oand--action-items-out. - Action-item corpus — with
--action-items,_ACTION-ITEMS.mddeduplicates items across meetings (by text similarity; threshold--similarity-threshold, 0.5–1.0, default 0.82) and groups them by owner, then status. Ids are stable (AI-001… and never renumber), each item carriesfirst_seen/last_seendates and its occurrence list, and open/ongoing/resolved statuses survive re-runs — so the corpus reads as living history across the series, not a per-meeting snapshot. Items can carry a free-form type, rendered in parens after the status, and pairs scoring just under the threshold are surfaced in a Possible duplicates (review) section at the end. - Dev-commitments corpus — each meeting's
commitments.json(fromingest --commitments) folds into_COMMITMENTS.mdautomatically whenever any exists: stableCM-NNNids that never renumber, the same 0.82 text-similarity dedupe and 0.10 near-miss review band, grouped by status then speaker, with**[boss]**marking boss-requested items. Hand edits in_COMMITMENTS.md(mark onedone, retitle, merge via(merged CM-NNN)) fold back on the next roll-up, exactly like the action-item corpus. The fold applies the same[commitments] min_wordsfragment rule as extraction, so per-meeting files written before the filter (or by a hook) never put "I'll do that" into the corpus: skipped entries are listed under Dropped fragments (review) and kept in_commitments.jsonasdropped;CMitems already in the corpus are never touched. Roll-up refolds only the meetings whose commitment inputs changed (commitments.json,action-items.md,*.speakers.txt, roles) or that are new or gone, so a small Teams delta takes seconds; it logsrefolding N changed commitment folder(s): ...and, on a long fold,folded N/M commitment folder(s)every 25 folders. Ids and hand edits stay put, and the fields a removed line contributed (cue, boss priority, requester) are re-derived from what is left. A[commitments]change inwhosaid.tomlstill refolds every meeting. - Personal worklist
_WORKLIST-<Owner>.md: whenever a commitments corpus or owner-attributed action items exist, roll-up also writes the owner's open items ranked into P1/P2/P3 (see Dev-commitments). The owner is--owner NAME, else theself-roled speaker, else[workspace] owner;--all-ownerswrites one file per participant. It is a regenerated view, never reconciled: edit the corpora, not the worklist.
Dedupe is text similarity (difflib, the --similarity-threshold above) and, when a local
Ollama answers on 127.0.0.1 with [search] embed = true, also embedding cosine: two texts
match when either the difflib ratio or the [search] embed_model cosine clears its threshold
([commitments] embed_threshold, default 0.90), so "I'll write the rollout runbook for the
platform team" and "for the platform team write the rollout runbook" fold into one item. No
Ollama, embed = false, or a non-loopback URL means difflib only, with one log line saying so.
Roll-up is incremental and append-only by default: re-running with nothing new writes nothing.
--rebuild is the escape hatch — it resets the manifest and corpus and regenerates both from the
folders on disk.
State is plain JSON in the workspace directory — _workspace.json (the manifest; it points at
the dev-commitments corpus via commitments_corpus) and _action-items.json (the corpus; it
also records the similarity_threshold in effect), plus the parallel _commitments.json.
All are safe to read and hand-edit — marking an item resolved by hand is the intended way to
close one the extractor phrased wrong. Hand edits made directly in _ACTION-ITEMS.md (and,
same contract, _COMMITMENTS.md) are folded back on the next roll-up and survive re-runs:
statuses, types, retitles, and (merged AI-NNN) merge annotations (the merged item stays at
its id, rendered collapsed as [merged → AI-NNN]). Only --rebuild discards them. --index
runs whosaid index <ws> right after the roll-up.
Upgrading to 1.11: reprocess older meetings
v1.10 fixed two diarizer faults: short fragments inflated the automatic speaker count, and
recordings under 15 minutes ignored --speakers N and undercounted. Meetings processed before
that keep their old speaker split, and their action items and commitments inherit it (a phantom
"speaker" owns items, or two people are merged into one). whosaid reprocess re-diarizes them
without re-running Whisper.
whosaid reprocess ./meetings --dry-run     # 1. what would change; touches nothing
whosaid reprocess ./meetings               # 2. re-diarize the flagged meetings (or --all)
$EDITOR ./meetings/_ACTION-ITEMS.md        # 3. review the refolded corpus
- The detector (
--dry-run). It reads each meeting's<base>.diarization.jsonand prints findings per meeting.likely:brief-fragments(an auto count that includes a cluster made only of turns under 2 s) andshort-hinted-undercount(audio under 900 s,--speakers Nhinted, fewer than N found), andbound-pinned(a--max-speakersbound, ormax_speakersinwhosaid.toml, set a saturated auto count to the bound instead of capping it; fixed in v1.11.2).possible:short-whole-file(audio under 900 s, auto count, no count estimate; a v1.10--no-chunkrun looks the same) andref-order(two or more--refvoices matched, which were assigned in argument order before v1.10). Sidecars written by v1.11.0 or v1.11.1 are checked forbound-pinnedonly; v1.11.2 or later are never flagged. With noMEETINGand no--all,reprocesstakes exactly the meetings with a finding;MEETINGnames (folder names) or--alloverride that. - No ASR. Each meeting is re-run as
whosaid transcribe --reuse-asr, which reuses the existing<base>.json. Diarization takes seconds to a minute per meeting. Regenerating action items runs the summarizer once per meeting, and theclaudeengine is a cloud call per meeting (see The claude engine);--engine Eand--hook CMDchoose the summarizer as iningest.--no-itemsskips regenerating action items and commitments. - Speaker counts. The flags a meeting was first diarized with (
--speakers Nor the--min/--max-speakersbounds, recovered from the sidecar'sdetect_mode) are reused unless you pass--speakers,--min-speakers,--max-speakers, or--expected-speakers, which replace them. Expected-speaker names are not recorded in the sidecar, so they are not recovered.--match-threshold Xsets the registry match threshold. - Preserved.
relabel --no-savelabels carry over to the new clusters by segment overlap. A role is never re-applied for a name the registry already knows. Thenreprocessrunswhosaid roll-up <ws> --action-items --refold MEETING=<backup>/action-items.mdfor each regenerated meeting, so corpus ids (AI-NNN/CM-NNN), hand-set status, and hand-edited titles survive while owners follow the new speaker labels. - Backups and restore. Before touching a meeting,
reprocesscopies its<base>.speakers.txt,<base>.speaker-cards.txt,<base>.rttm,<base>.diarization.json,action-items.{md,json}, andcommitments.{md,json}to<ws>/_reprocess-backups/<meeting>/<UTC timestamp>/, and restores them itself if a step fails. To undo a run you did not want, copy those files back into the meeting folder, then runwhosaid roll-up <ws> --refold MEETING(a plain roll-up skips already-folded meetings). The_-prefixed folder is skipped by roll-up and workspace scans; delete it when you are satisfied.
On 8 synthetic meetings first processed by v1.8.2 (ground truth known), the total absolute
speaker-count error went from 11 to 6, and the two meetings run with --speakers N went from 2
speakers found (of 5 and of 3) to exact. Whisper was skipped in 8 of 8, and a --no-save label,
a hand-set done, and a hand retitle all survived the refold with ids unchanged.
The MCP tool whosaid_reprocess wraps the same command; its dry_run defaults to true.
whosaid teams ingest — Microsoft Teams chat, no audio
Many decisions and commitments are made in Teams chat, not in recorded calls. whosaid teams ingest adds a chat export to the same workspace. There is no diarization and no Whisper, because
every message already names its author.
whosaid teams ingest teams-export.json --into ~/meetings --tz America/Los_Angeles --self Alice_Example
whosaid roll-up ~/meetings --index
The input is the output of the browser scraper in
contrib/teams-scraper/. That can be its raw_by_chat map,
a flat list or NDJSON of {chat, author, ts, epoch, text} records, or the same records with
timestamp_iso/epoch_ms. The scraper's README also covers how to run it and the Teams web DOM
contract it depends on. Ingest writes one dated folder per chat per local
day (YYYY-MM-DD-HHMM, where the time is that day's first message). Each folder holds:
teams.speakers.txt:[HH:MM:SS] Speaker: textturns, stamped with the local time of day.teams.diarization.json: the provenance sidecar.source.kindis"teams-chat", and each segment keeps the message's exactepoch_ms.
Search, the graph, commitments and the worklist all read teams.speakers.txt the same way they
read a recording's transcript. A search hit's file is teams.speakers.txt, and whosaid graph <ws> meetings --kind teams-chat (or the kind argument of the whosaid_meetings MCP tool)
tells chat days apart from recordings. A folder with no audio takes its created time from the
sidecar's source.creation_time. The roll-up audit treats it as text-only rather than flagging a
missing transcript.
Map Teams display names to the names you use elsewhere, and give people roles, in whosaid.toml:
[teams.names]
"Doe, Jane (Vendor, consultant)" = "Jane_Example"

[teams.roles]
Jane_Example = "boss"
Unmapped authors keep their display name. When a role is not set in [teams.roles], it comes
from the voice registry's role for the same name. --self NAME overrides both. Re-ingesting an
overlapping export is safe: messages are deduplicated on epoch_ms and merged into the existing
folder, and --dry-run shows what would be written.
whosaid teams ingest-transcript: Microsoft Teams meeting transcripts, no audio
When Teams has already transcribed a meeting, the Recap page's Transcript panel names every
speaker. whosaid teams ingest-transcript adds that transcript to the workspace without the audio.
whosaid teams ingest-transcript transcript.json --into ~/meetings --tz America/Los_Angeles --self Alice_Example
The input is window.__tt.result from
contrib/teams-scraper/teams-transcript-scraper.js.
The panel is a virtualized list, so the scraper reads the list's full item array from React
rather than the few rows on screen, and falls back to a scroll-and-harvest pass that puts the
scroll position back. One meeting becomes one folder named from the meeting start
(YYYY-MM-DD-HHMM). teams.speakers.txt stamps each turn as an offset from the start, like a
recording's transcript, and teams.diarization.json has source.kind "teams-transcript",
the transcript_id, and the Start/Stop events. The start comes from the export's
meeting.start_iso or from --start ISO. Re-ingest rewrites the folder that already holds the
same transcript_id. [teams.names], [teams.roles], --self and --dry-run work as for chat.
Search your meetings
A workspace with a dozen meetings is a corpus you cannot reread. whosaid index turns it into
something you can query: an exact full-text index over every turn, optional meaning search
through a local embedding model, an entity graph (people, meetings, action items, timestamped
commitments, PR mentions), and a generated wiki. Everything lives in the workspace, everything is
rebuildable, and nothing leaves the machine.
whosaid index ./meetings                     # build _search.db + _WIKI.md (embeds if Ollama is up)
whosaid index ./meetings --no-embed          # exact search only, no Ollama needed
whosaid search ./meetings "budget"           # every turn that says budget
whosaid search ./meetings "who is blocked" --mode meaning
whosaid search ./meetings '"token exchange"' --speaker Bob_Example --meeting 2026-09-16 -k 5
whosaid context ./meetings 2026-09-16-0900 00:00:06   # the verbatim minute around a hit
whosaid graph ./meetings items --owner Alice_Example --status open
whosaid graph ./meetings item AI-003         # one item: occurrences + timestamped commitments
whosaid graph ./meetings person Bob_Example  # talk share, commitments made, asks received
whosaid graph ./meetings prs | whosaid graph ./meetings meetings | whosaid graph ./meetings speakers
whosaid wiki ./meetings --stdout             # the generated wiki, regenerated from the graph
<ws> can be left out everywhere: the commands fall back to $WHOSAID_WORKSPACE, then to the
current directory when it holds _workspace.json or whosaid.toml. Any subfolder with a
*.speakers.txt counts as a meeting, dated or hand-named, so transcripts you made by hand are
indexed too.
Three search modes. --mode exact (the default) is SQLite FTS5: words, "quoted phrases",
AND/OR/NOT, and prefix*, and it needs nothing but Python. --mode meaning embeds the
query with nomic-embed-text through Ollama on 127.0.0.1:11434 and returns the nearest turns,
so "who is blocked" finds "I'm stuck until the review lands" with no shared words. --mode hybrid
runs both and fuses the rankings, which is usually what you want once the index has embeddings.
Every hit prints the same way, and --json gives you one object per hit with the same fields:
$ whosaid search ./meetings "budget"
whosaid: engine: exact
[2026-09-16-0900 @ 00:00:06] Bob_Example: I will review the »budget« spreadsheet before Thursday.
1 hit(s).

$ whosaid context ./meetings 2026-09-16-0900 00:00:06 --before 10 --after 10
whosaid: 2026-09-16-0900: 3 turn(s) between 0s and 16s
[00:00:01] Alice_Example: Let's start with the roadmap for next quarter.
[00:00:06] Bob_Example: I will review the budget spreadsheet before Thursday.
[00:00:14] Alice_Example: Great, and I will send the draft out to the team today.
Set Ollama up once if you want meaning search: brew install ollama && brew services start ollama && ollama pull nomic-embed-text. Without it, index skips the embedding pass with a note and
search runs exact-only; nothing fails.
Graph views. The entity tables are built from reliable signals only: the manifest, the
deduplicated action-item corpus, each meeting's action-items.md, and the transcripts
themselves. items filters by --owner, --requester, --status, and --type; item AI-NNN
shows one item's occurrences and every timestamped commitment behind it; person [Name] is the
per-owner view (talk share, what they committed to, what they asked others for); prs lists
pull-request numbers mentioned in speech or in the notes; meetings is coverage per folder; and
speakers is talk share across the workspace. Every view takes --json.
The wiki. _WIKI.md is a generated rollup: people, meetings, open items, and PR mentions,
each action item citing the [meeting @ time] it was committed at. It is regenerated by index
and by whosaid wiki, so it never drifts from the data. Edit the corpus, not the wiki.
Per-workspace settings: whosaid.toml. Optional, next to the transcripts. Every key has a
default; WHOSAID_OWNER, WHOSAID_OLLAMA, and WHOSAID_SUMMARIZER_MODEL override the matching
keys per run.
[workspace]
owner = "Alice_Example"          # whose action items this workspace tracks
aliases = ["Ali", "Alicia"]      # how the transcript may misspell the owner (default: first name)

[groups]                         # optional, ordered; drives the action-item sections
leadership = ["Bob_Example"]
team = ["Carol_Example", "Dan_Example"]

[summarizer]
engine = "auto"                  # auto | ollama | claude | hook | none (claude: opt-in, cloud)
model = "qwen2.5:14b"
timeout = 900                    # seconds per model call
num_predict = 2048               # max tokens per model reply; caps a runaway generation
think = false                    # thinking models (qwen3, qwen3.x) skip reasoning; much faster
                                 # per model: think = { "qwen3:14b" = true, default = false }
claude_model = "opus"            # engine = "claude": any `claude --model` value
claude_timeout = 900             # seconds for the one claude call
claude_bin = ""                  # path to `claude` (default: WHOSAID_CLAUDE_BIN, PATH, ~/.local/bin)
fallback = "ollama"              # engine = "claude" failed: "ollama" (if it is up) or "none" (skeleton)

[search]
ollama = "http://127.0.0.1:11434"
embed_model = "nomic-embed-text"
embed = true                     # false: exact search only, never contact Ollama

[commitments]                    # optional; ranks _WORKLIST-<Owner>.md. A list you set replaces
boss = []                        # the default list, so omit a key to keep the built-in cues.
deadline_cues = ["today", "tonight", "tomorrow", "eod", "end of day", "this week", "next week"]
blocking_cues = ["blocking", "blocked", "urgent", "asap", "critical", "hotfix", "outage", "prod issue", "release blocker", "customer escalation"]
negators = ["not", "no", "non", "never", "isn't", "won't", "don't", "without", "hardly"]
embed_threshold = 0.90           # cosine at or above this is a duplicate (with [search] embed)
min_words = 2                    # content words a commitment clause needs; 0 keeps every fragment
[commitments.weights]            # score = sum of the signals that fired
boss = 5
blocking = 4
deadline = 4
overdue = 1                      # replaces deadline once a relative deadline has passed
repeat = 2                       # per extra meeting
recent = 1
strong = 1
requested = 1
negative = -3

[watch]
source = ""                      # folder to watch (default: the macOS Voice Memos store)
# speakers = 2                   # exact diarization speaker count (a 1:1-call workspace)
# min_speakers = 2               # lower bound on auto-detected speaker count
# max_speakers = 4               # upper bound (a ceiling for a mixed-size meeting workspace)
# expected_speakers = ["Alice_Example", "Bob_Example"]   # roster, or "Alice_Example,Bob_Example"

[diarize]                        # same four keys, for EVERY ingest into this workspace
# max_speakers = 8               # e.g. a ceiling near the team's real headcount
What _search.db is. One SQLite file in the workspace: an FTS5 table of every turn (meeting,
timestamp, speaker, text), a table of stored embeddings keyed by turn, and the graph tables.
It is a derived artifact. Delete it whenever you like and run whosaid index again; --rebuild
does the same and also re-embeds every turn.
Action items drafted by a local model
whosaid ingest --action-items can draft each meeting's action-items.md with a local model
instead of a hook. --engine (or [summarizer] engine in whosaid.toml) picks how:
| Engine | What happens |
|---|---|
auto (default) | The hook if one is configured, else Ollama if it answers on localhost, else the skeleton. |
ollama | The built-in summarizer below. If Ollama is down or the model is missing, it warns and writes the skeleton (exit 0). |
claude | Opt-in, cloud. The transcript text goes to Anthropic. See The claude engine. auto never picks it. |
hook | The --hook / WHOSAID_ACTION_ITEMS_HOOK command, exactly as before. |
none | The skeleton only (speakers listed, no items). |
Documentation truncated — see the full README on GitHub.
Reviews
No reviews yet
Be the first to review this server!
More Developer Tools MCP Servers
Rea
Freeby Morluto · Developer Tools
Reverse engineer anything from your terminal or agent with one CLI and MCP server.
Paperclip
Freeby Paperclipai · Developer Tools
Trending hip-hop artist momentum scores across four cultural dimensions.
Git
Freeby Modelcontextprotocol · Developer Tools
Read, search, and manipulate Git repositories programmatically
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
MCP Marketplace
Freeby mcp-marketplace · Developer Tools
Search and install MCP servers from inside your AI client.
mcp-creator-python
Freeby mcp-marketplace · Developer Tools
Create, build, and publish Python MCP servers to PyPI — conversationally.