
Server data from the Official MCP Registry
Multi-source biomedical literature search: PubMed, Europe PMC, OpenAlex, full text, citations
About
Multi-source biomedical literature search: PubMed, Europe PMC, OpenAlex, full text, citations
Security Report
The PubMed Search MCP server is consistent with its stated literature-research purpose, and the visible code shows bearer-token auth for service mode, tenant-scoped data access, and loopback-by-default binding. Key concerns are that local HTTP mode runs without authentication unless PUBMED_AUTH_TOKENS is set, that --no-security can disable DNS rebinding protection, and that the browser fetch broker keeps authenticated browser sessions in a persistent profile. Several source files were truncated, so this review is partial. Supply chain analysis found 5 known vulnerabilities in dependencies (1 critical, 1 high severity). Package verification found 1 issue.
5 files analyzed · 11 issues found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Permissions Required
This plugin requests these system permissions. Most are normal for its category.
What You'll Need
Set these up before or after installing:
Environment variable: NCBI_EMAIL
Environment variable: NCBI_API_KEY
How to Install
Add this to your MCP configuration file:
{
  "mcpServers": {
    "io-github-u9401066-pubmed-search-mcp": {
      "env": {
        "NCBI_EMAIL": "your-ncbi-email-here",
        "NCBI_API_KEY": "your-ncbi-api-key-here"
      },
      "args": [
        "pubmed-search-mcp"
      ],
      "command": "uvx"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
PubMed Search MCP




Professional Literature Research Assistant for AI Agents - More than just an API wrapper
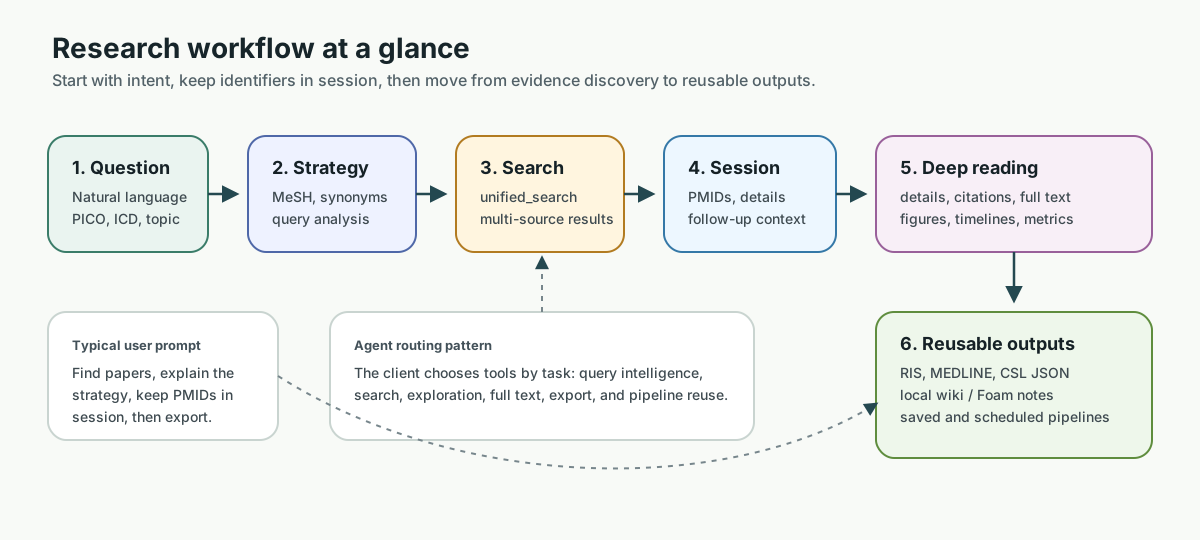
A Domain-Driven Design (DDD) based MCP server that serves as an intelligent research assistant for AI agents, providing task-oriented literature search and analysis capabilities.
✨ What's Included:
- 🔧 41 MCP Tools - Streamlined PubMed, Europe PMC, CORE, NCBI database access, and the versioned Research Chronicle
- 🛡️ Multi-Agent Service Mode - Deploy once and serve many agents: per-tenant sessions, caches, and artifacts, bearer-token auth, and per-tenant fair-share limits. See DEPLOYMENT.md
- 🖼️ OA Figure Extraction - Pull figure captions, direct image URLs, and PDF links from PMC Open Access articles
- 📘 Docs Site - Browse the complete language-switchable handbook: user workflows, architecture, 41-tool reference, pipeline tutorials, source/broker contracts, integrations and operations, security, and deployment at u9401066.github.io/pubmed-search-mcp
- 📖 GitHub Wiki - GitHub-native mirror of the same canonical documentation at github.com/u9401066/pubmed-search-mcp/wiki
- 📚 26 Claude Skills - Ready-to-use workflow guides for AI agents (Claude Code-specific)
- 📖 Copilot Instructions - VS Code GitHub Copilot integration guide
- Research automation - Scheduled pipeline diffs/local notifications, Chronicle rebuild summaries, multi-seed citation snowballing, and opt-in session deduplication with
options="exclude_seen".
🌐 Language: English | 繁體中文
📘 Documentation Map: README is the quick project entry point. Use the Docs Site for the best reading experience, the GitHub Wiki for GitHub-native navigation, and source docs for edits: User guide | Advanced workflows | Capability-first guide | Unified Search architecture | 41-tool quality audit | 60-repository academic retrieval landscape | Provider data planes | BioMCP architecture analysis | Developer guide | Complete index
Documentation map · Maintenance scripts
Research automation and portable installation — v0.8.0
Scheduled pipelines report bounded changes and retain local notification summaries.
Chronicle rebuild summaries compare the previous revision; snowball pipelines
expand multiple citation seeds. Normal searches can opt into options="exclude_seen"
to filter previously returned PMID/DOI identities in this session before limit;
the option is rejected with pipeline=. The interface remains 41 tools.
See the usage guide and
pipeline tutorial.
Registry metadata and plugin drift are checked before PyPI upload. Release smoke verifies the exact wheel's ownership marker and all 41 installed tools under the registry environment contract; registry publication follows PyPI via GitHub OIDC.
Real workflow smoke and local pretest — v0.7.7
Local pretest runs the complete regression gate before push. CI focuses on
Ubuntu/Windows installed artifacts and real MCP/provider workflows; publication
verifies the exact wheel/sdist and a running non-root container. Removed 64 weak
or obsolete tests with documented replacement coverage. See the
testing policy and
phased release review.
Background fulltext and reliable section reads — v0.7.6
Opt-in XML prefetch shares downloads with later get_fulltext calls. Queued
articles become foreground reads when requested; search returns ready-to-use
read arguments. Missing sections report available titles without substituting
abstracts or repeating PDF retrieval. Prefetch remains off by default.
See the assessment and
release review.
Shared input normalization — v0.7.5
All 41 tools share automatic correction for JSON containers, decimal numeric strings, explicit boolean text, enum spelling and biomedical identifiers. Published schemas include accepted representations; pre-execution errors provide precise field paths and repair constraints. Native and normalized requests are verified across all tools, including one corrected retry. See input formats and validation.
Provider-safe scheduling — v0.7.4
Pipeline branches now proceed as their dependencies finish while API request-rate limits remain unchanged. Shared concurrency uses the most conservative caller limit; 429 cooldowns survive timeouts and cancelled PubMed workers. Historical plans are archived behind a documentation map. See the release review and offline latency experiment; fixed-delay timing is not a live-provider throughput or retrieval-quality claim.
Core review and reliability — v0.7.3
Completed the ten-phase core review: 223 source files and 2,901 definitions with authored decisions and current file hashes. This release repairs source-failure handling, article identity, persistence, cancellation, exports, and evaluation checkpoints while keeping all 41 tools. Harness installation preserves user customizations; contributors run the full local gate before push, with an independent smoke gate in ordinary CI. See the changelog for behavior changes. Local regression results do not establish a new public benchmark gain.
Research quality and evaluation — v0.7.2
This release improves query-aware ranking and fusion, cross-source article deduplication, bibliographic verification, section filtering, and concurrent cache fetches. The canonical 41-tool interface remains unchanged.
The benchmark report separates component quality from the value of the complete agent package. On public BEIR NFCorpus, an earlier BM25 component comparison improved test nDCG@10 from 0.293357 to 0.297831. That result does not measure this release's full agent performance. The three-question native Codex/package pilot is too small to establish a product-level gain; the complete 5,000-question evaluation is prepared but has not been started.
Read the reliability audit for reproduced defects, validation boundaries, and revision fingerprints. Reference verification checks bibliographic consistency; confirming that a paper supports a claim still requires inspecting the relevant passage.
🚀 Quick Install
MCP Registry and Agent Plugin
In clients that support the official MCP Registry
or GitHub MCP Registry, look up
io.github.u9401066/pubmed-search-mcp once the release is published. Registry
metadata launches uvx pubmed-search-mcp@0.8.0 over stdio; configure NCBI_EMAIL
and optionally NCBI_API_KEY in the client.
For Agent Plugins 1.0.0-compatible clients, install the repository's
plugins/pubmed-search/ directory using the client's
plugin installer. It bundles the version-pinned MCP launcher and research skills;
client plugin support and installation UI vary. See integrations.
Prerequisites
-
Python 3.10+ — Download
-
uv (recommended) — Install uv
# macOS / Linux curl -LsSf https://astral.sh/uv/install.sh | sh # Windows powershell -ExecutionPolicy ByPass -c "irm https://astral.sh/uv/install.ps1 | iex" -
NCBI Email — Required by NCBI API policy. Any valid email address.
-
NCBI API Key (optional) — Get one here for higher rate limits (10 req/s vs 3 req/s)
-
OpenAlex API Key (optional) — set
OPENALEX_API_KEYto use an authenticated credit allocation; without it, requests use OpenAlex's current anonymous casual-use budget.mailtois contact metadata, not authentication. Without source-specific emails, the server reuses the configured runtime contact email for OpenAlex, CrossRef, and Unpaywall.
Install & Run
# Option 1: Zero-install with uvx (recommended for trying out)
uvx pubmed-search-mcp

# Option 2: Add as project dependency
uv add pubmed-search-mcp

# Option 3: pip install
pip install pubmed-search-mcp
Python SDK Facade
For in-process Python integrations, use the stable SDK facade instead of importing MCP tool modules:
from pubmed_search.api import PubMedSearchClient, PubMedSearchConfig

async with PubMedSearchClient(PubMedSearchConfig(email="your@email.com")) as client:
    result = await client.unified_search("remimazolam ICU sedation", limit=20)

    print(result.articles)
    print(result.source_counts)
    print(result.source_errors)
    print(result.result_filter_counts)
Use uvx pubmed-search-mcp or /mcp for agent tool discovery. Use the SDK for
Python package/notebook calls where a typed object is easier than parsing an MCP
response string.
The SDK executes the application use case directly and intentionally has no MCP
session journal or artifact side effects; use the MCP tool when durable replay
and artifact locators are required.
The async context owns and closes every provider client and HTTP pool. If a
long-lived application does not use async with, call await client.aclose()
during shutdown.
Choose a Runtime Contract
| Contract | Command | Network and trust boundary |
|---|---|---|
| Local stdio | uvx pubmed-search-mcp | Recommended for one local AI client; no listening MCP port |
| Local loopback HTTP | pubmed-search-mcp-http --mode local --host 127.0.0.1 | Trusted single-user integration; MCP requests share the durable default tenant, and the port must never be published |
| Multi-user service | pubmed-search-mcp-http --mode service | Remote/team use behind HTTPS; bearer auth, allowed hosts/origins, and per-principal storage are mandatory |
Local and service deployments are intentionally separate contracts. Do not turn
the local HTTP command into a public service by changing only its bind address.
The explicit local profile retains pmids="last", sessions, cache, and exports
across MCP requests and reconnects in its durable default tenant; this is safe
only inside the enforced loopback/Host/Origin boundary. Service mode never
inherits that trust: it fails closed without a bearer principal. Use
DEPLOYMENT.md for the service environment and Compose profile.
The current service profile supports many authenticated principals in one
server process; keep one replica until sessions, locks, artifacts, and
subscriptions have shared backends.
The protocol baseline is MCP SDK v2 (mcp>=2.0,<3). Modern 2026-07-28 clients
send tools/list and tools/call directly, without an initialize handshake or
Mcp-Session-Id. Local mode retains filesystem features. Authenticated service
callers cannot load file: pipelines, select note output_dir/template_file,
or inherit a process-wide pipeline workspace. Note responses use tenant-relative
logical locators and never reveal server filesystem paths. The service Compose scheduler is
disabled. See the Integrations & Operations Guide
for the capability matrix.
⚙️ Configuration
This MCP server works with any MCP-compatible AI tool. Choose your preferred client:
VS Code / Cursor (.vscode/mcp.json)
{
  "servers": {
    "pubmed-search": {
      "type": "stdio",
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com"
      }
    }
  }
}
Optional: enable browser-session PDF fallback once and let tools auto-use it:
{
  "servers": {
    "pubmed-search": {
      "type": "stdio",
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com",
        "BROWSER_FETCH_CONFIG": "{\"enabled\":true,\"auto_enabled\":true,\"broker_url\":\"http://127.0.0.1:8766/fetch\",\"token\":\"<random-32-byte-token>\",\"allowed_hosts\":[\"jamanetwork.com\",\"*.jamanetwork.com\",\"nejm.org\",\"*.nejm.org\"]}"
      }
    }
  }
}
With this setting, get_fulltext will automatically try the local broker for institutional or publisher landing pages. Pass allow_browser_session=false only when you want to suppress it for a specific call.
Run the local broker with download interception:
uv sync --extra browser-broker
uv run playwright install chromium
uv run python -c "import secrets; print(secrets.token_urlsafe(32))"
uv run pubmed-browser-fetch-broker --token "<same-random-32-byte-token>"
Copy the generated value into both commands/configurations; never reuse a
published example token. --token, BROWSER_FETCH_BROKER_TOKEN, or the
shared BROWSER_FETCH_TOKEN is required; the broker fails closed instead of
generating or logging a secret. The broker launches a persistent browser
profile with download interception enabled. Log in once inside that
broker-controlled browser window, and subsequent PDF downloads will be captured
automatically without a native "Save As" dialog.
Claude Desktop (claude_desktop_config.json)
{
  "mcpServers": {
    "pubmed-search": {
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com"
      }
    }
  }
}
Config file location:
- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json- Windows:
%APPDATA%\Claude\claude_desktop_config.json- Linux:
~/.config/Claude/claude_desktop_config.json
Claude Code
claude mcp add pubmed-search -- uvx pubmed-search-mcp
Or add to .mcp.json in your project root:
{
  "mcpServers": {
    "pubmed-search": {
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com"
      }
    }
  }
}
Zed AI (settings.json)
Zed editor (z.ai) supports MCP servers natively. Add to your Zed settings.json:
{
  "context_servers": {
    "pubmed-search": {
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com"
      }
    }
  }
}
Tip: Open Command Palette →
zed: open settingsto edit, or go to Agent Panel → Settings → "Add Custom Server".
OpenClaw 🦞 (~/.openclaw/openclaw.json)
OpenClaw uses MCP servers via the mcp-adapter plugin. Install the adapter first:
openclaw plugins install mcp-adapter
Then add to ~/.openclaw/openclaw.json:
{
  "plugins": {
    "entries": {
      "mcp-adapter": {
        "enabled": true,
        "config": {
          "servers": [
            {
              "name": "pubmed-search",
              "transport": "stdio",
              "command": "uvx",
              "args": ["pubmed-search-mcp"],
              "env": {
                "NCBI_EMAIL": "your@email.com"
              }
            }
          ]
        }
      }
    }
  }
}
Restart the gateway after configuration:
openclaw gateway restart
openclaw plugins list  # Should show: mcp-adapter | loaded
Cline (cline_mcp_settings.json)
{
  "mcpServers": {
    "pubmed-search": {
      "command": "uvx",
      "args": ["pubmed-search-mcp"],
      "env": {
        "NCBI_EMAIL": "your@email.com",
        "SEMANTIC_SCHOLAR_API_KEY": "your_semantic_scholar_key",
        "PUBMED_SEARCH_DISABLED_SOURCES": ""
      },
      "alwaysAllow": [],
      "disabled": false
    }
  }
}
Other MCP Clients
Any MCP-compatible client can use this server via stdio transport:
# Command
uvx pubmed-search-mcp

# With environment variable
NCBI_EMAIL=your@email.com uvx pubmed-search-mcp
Note:
NCBI_EMAILis required by NCBI API policy. Optionally setNCBI_API_KEYfor higher rate limits (10 req/s vs 3 req/s). 📖 Detailed Integration Guides: See docs/guides/INTEGRATIONS.md for all environment variables, Copilot Studio setup, Docker deployment, proxy configuration, and troubleshooting.
🎯 Design Philosophy
Core Positioning: The intelligent middleware between AI Agents and academic search engines.
Why This Server?
Other tools give you raw API access. We give you vocabulary translation + intelligent routing + research analysis:
| Challenge | Our Solution |
|---|---|
| Agent uses ICD codes, PubMed needs MeSH | ✅ Auto ICD→MeSH conversion |
| Multiple databases, different APIs | ✅ Unified Search single entry point |
| Clinical questions need structured search | ✅ PICO handoff + pipeline (validate_pico_plan validates agent-provided P/I/C/O and returns a runnable template: pico pipeline) |
| Typos in medical terms | ✅ ESpell auto-correction |
| Too many results from one source | ✅ Parallel multi-source with dedup |
| Need to trace research evolution | ✅ Research Chronicle & Tree with landmark detection, diagnostics, sub-topic branching, and versioned revisions |
| Citation context is unclear | ✅ Citation Tree forward/backward/network |
| Can't access full text | ✅ Multi-source fulltext (Europe PMC XML, Unpaywall OA locations, institutional direct/EZproxy, CORE, and downloader fallbacks) |
| Gene/drug info scattered across DBs | ✅ NCBI Extended (Gene, PubChem, ClinVar) |
| Need cutting-edge preprints | ✅ Preprint search (arXiv, medRxiv, bioRxiv) with detected-preprint filtering; this does not verify peer-review status |
| Export to reference managers | ✅ One-click export (official RIS/MEDLINE/CSL JSON; local RIS/BibTeX/CSV/MEDLINE/JSON) |
Key Differentiators
- Vocabulary Translation Layer - Agent speaks naturally, we translate to each database's terminology (MeSH, ICD-10, text-mined entities)
- Unified Search Gateway - One
unified_search()call, capability-aware dispatch across PubMed, Europe PMC, CORE, OpenAlex, Semantic Scholar, and enabled preprint/commercial sources - PICO Handoff + Pipeline - the Agent extracts P/I/C/O,
validate_pico_plan()validates that structured handoff, and the backendtemplate: picopipeline executes O-aware precision/recall searches - Research Chronicle & Lineage Tree - Detect milestones with policy-driven heuristics, identify landmark papers via multi-signal scoring, surface diagnostics, persist versioned revisions you can diff, and visualize research evolution as branching trees by sub-topic
- Citation Network Analysis - Build multi-level citation trees to map an entire research landscape from a single paper
- Full Research Lifecycle - From search → discovery → full text → analysis → export, all in one server
- Agent-First Design - Output optimized for machine decision-making, not human reading
📡 External APIs & Data Sources
This MCP server integrates with multiple academic databases and APIs:
Core Data Sources
| Source | Coverage | Vocabulary | Auto-Convert | Description |
|---|---|---|---|---|
| NCBI PubMed | 36M+ articles | MeSH | ✅ Native | Primary biomedical literature |
| NCBI Entrez | Multi-DB | MeSH | ✅ Native | Gene, PubChem, ClinVar |
| Europe PMC | 33M+ | Text-mined | ✅ Extraction | Full text XML access |
| CORE | 200M+ | None | ➡️ Free-text | Open access aggregator |
| Semantic Scholar | Evolving graph + operator datasets | S2 fields / bulk syntax | ✅ Broker-compiled modes | Relevance, bounded bulk, batch, citation graph, and metadata-only release/diff plane; no partition download |
| OpenAlex | Evolving open research graph | Topics / keywords | ✅ Keyword + bounded native semantic | Cursor, cost provenance, entity graph, and declared operator snapshot path; no local index yet |
| NIH iCite | PubMed | N/A | N/A | Citation metrics (RCR) |
🔑 Key: ✅ = Full vocabulary support | ➡️ = Query pass-through (no controlled vocabulary)
ICD Codes: Auto-detected and converted to MeSH before PubMed search
Environment Variables
# Required
NCBI_EMAIL=your@email.com          # Required by NCBI policy

# Optional - For higher rate limits
NCBI_API_KEY=your_ncbi_api_key     # Get from: https://www.ncbi.nlm.nih.gov/account/settings/
CORE_API_KEY=your_core_api_key     # Get from: https://core.ac.uk/services/api
CROSSREF_EMAIL=your@email.com      # Optional override; defaults to server/NCBI email
UNPAYWALL_EMAIL=your@email.com     # Optional override; defaults to server/NCBI email
SEMANTIC_SCHOLAR_API_KEY=your_semantic_scholar_key # https://www.semanticscholar.org/product/api
OPENALEX_API_KEY=your_openalex_key # Raises the OpenAlex credit budget; actual grant is response-driven
PUBMED_SEARCH_DISABLED_SOURCES=    # Example: semantic_scholar

# Optional - Pipeline run-wide safety budgets
PUBMED_PIPELINE_RUN_TIMEOUT_SECONDS=120 # Shared end-to-end deadline (max 3600)
PUBMED_PIPELINE_MAX_EXTERNAL_CALLS=40   # Shared across sequential/parallel steps (max 1000)

# Optional - Network settings
HTTP_PROXY=http://proxy:8080       # HTTP proxy for API requests
HTTPS_PROXY=https://proxy:8080     # HTTPS proxy for API requests

# Optional - Institutional fulltext access
INSTITUTIONAL_DIRECT_FETCH=true    # Try DOI publisher pages before CORE fallback
EZPROXY_ENABLED=false              # Enable only after configuring EZPROXY_HOST + cookie
EZPROXY_HOST=ezproxy.example.edu
EZPROXY_COOKIE_FILE=/path/to/cookies.json

# Optional - Local note export
PUBMED_NOTES_DIR=/path/to/wiki/references  # save_literature_notes target folder
PUBMED_WORKSPACE_DIR=/path/to/project       # fallback: references/ under this workspace
PUBMED_DATA_DIR=~/.pubmed-search-mcp        # fallback: references/ under this data dir
CrossRef and Unpaywall reuse the runtime server contact email (NCBI_EMAIL,
CLI --email, or detected git email) unless a source-specific email is
configured. OpenAlex accepts casual anonymous use and an optional API key; the
broker reads its response credit/rate metadata instead of assuming a permanent
"polite pool" quota.
Local note export resolves directories in this order: output_dir argument, PUBMED_NOTES_DIR, PUBMED_WORKSPACE_DIR/references, PUBMED_DATA_DIR/references, then ~/.pubmed-search-mcp/references.
This path/template selection applies only to trusted local mode. Authenticated
service notes always use a built-in format below the current tenant's isolated
references/ directory.
For LLM wiki compatibility, wiki and foam exports use stable link targets based on PMID, DOI, PMCID, or fallback identifiers; titles remain aliases/display labels, and the response includes wiki_validation for unresolved wikilink checks.
🔄 How It Works: The Middleware Architecture
┌─────────────────────────────────────────────────────────────────────────────┐
│                              AI AGENT                                        │
│                                                                              │
│   "Find papers about I10 hypertension treatment in diabetic patients"       │
│                                                                              │
└─────────────────────────────────┬───────────────────────────────────────────┘
                                  │
                                  ▼
┌─────────────────────────────────────────────────────────────────────────────┐
│                     🔄 PUBMED SEARCH MCP (MIDDLEWARE)                        │
│  ┌─────────────────────────────────────────────────────────────────────────┐│
│  │  1️⃣ VOCABULARY TRANSLATION                                              ││
│  │     • ICD-10 "I10" → MeSH "Hypertension"                                ││
│  │     • "diabetic" → MeSH "Diabetes Mellitus"                             ││
│  │     • ESpell: "hypertention" → "hypertension"                           ││
│  └─────────────────────────────────────────────────────────────────────────┘│
│  ┌─────────────────────────────────────────────────────────────────────────┐│
│  │  2️⃣ INTELLIGENT ROUTING                                                 ││
│  │     ┌──────────┐  ┌──────────┐  ┌──────────┐  ┌──────────┐             ││
│  │     │ PubMed   │  │Europe PMC│  │   CORE   │  │ OpenAlex │             ││
│  │     │  36M+    │  │   33M+   │  │  200M+   │  │  250M+   │             ││
│  │     │  (MeSH)  │  │(fulltext)│  │  (OA)    │  │(metadata)│             ││
│  │     └────┬─────┘  └────┬─────┘  └────┬─────┘  └────┬─────┘             ││
│  │          └──────────────┴──────────────┴──────────────┘                 ││
│  │                              ▼                                          ││
│  │  3️⃣ RESULT AGGREGATION: Dedupe + Rank + Enrich                         ││
│  └─────────────────────────────────────────────────────────────────────────┘│
└─────────────────────────────────┬───────────────────────────────────────────┘
                                  │
                                  ▼
┌─────────────────────────────────────────────────────────────────────────────┐
│                         UNIFIED RESULTS                                      │
│   • 150 unique papers (deduplicated from 4 sources)                          │
│   • Ranked by relevance + citation impact (RCR)                              │
│   • Full text links enriched from Europe PMC                                 │
└─────────────────────────────────────────────────────────────────────────────┘
🛠️ MCP Tools Overview
If you want to understand the tool surface as a usable system, do not start by memorizing 41 tool names.
Start with the Tools Usage Guide: it compresses the current 41 tools into 8 capability families, explains the theoretical lower bound, and gives intent-based routing for both humans and agents.
🔍 Search & Query Intelligence
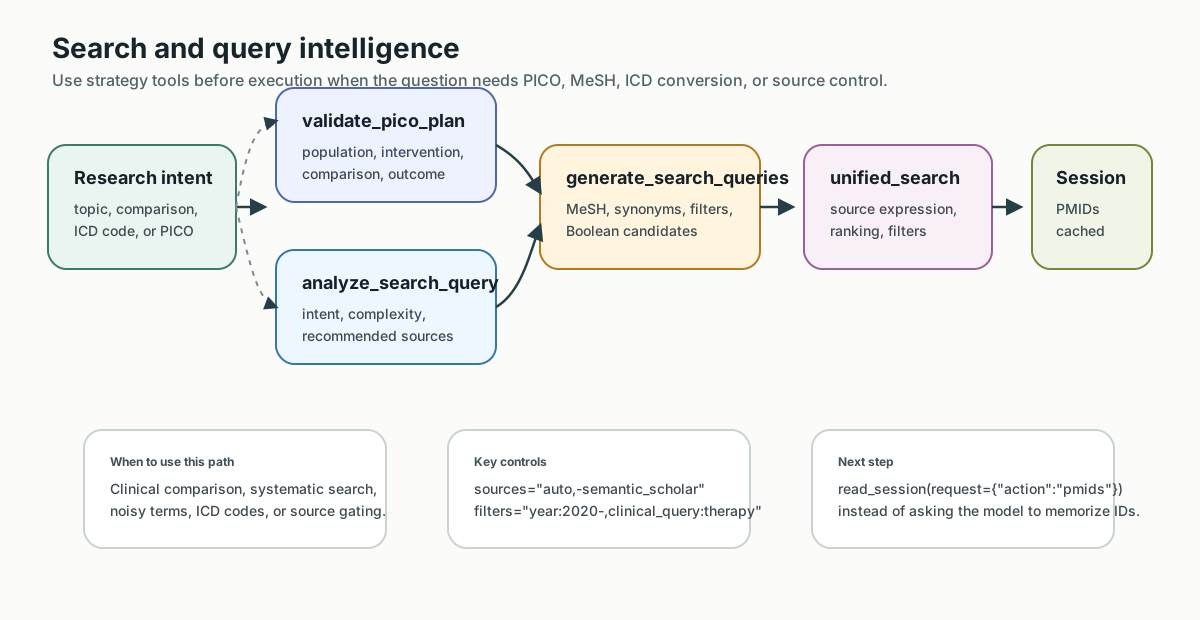
┌─────────────────────────────────────────────────────────────────┐
│                      SEARCH ENTRY POINT                          │
├─────────────────────────────────────────────────────────────────┤
│                                                                  │
│   unified_search()          ← 🌟 Single entry for all sources    │
│        │                                                         │
│        ├── Quick search     → Direct multi-source query          │
│        ├── Native semantic → Bounded OpenAlex semantic mode    │
│        ├── Systematic       → Bounded provider bulk/cursor mode  │
│        ├── PICO hints       → Detects comparison, shows P/I/C/O  │
│        └── ICD expansion    → Auto ICD→MeSH conversion           │
│                                                                  │
│   Sources: PubMed · Europe PMC · CORE · OpenAlex · S2            │
│   Auto: Deduplicate → Rank → Enrich full-text links              │
│                                                                  │
├─────────────────────────────────────────────────────────────────┤
│   QUERY INTELLIGENCE                                             │
│                                                                  │
│   generate_search_queries() → MeSH expansion + synonym discovery │
│   validate_pico_plan()              → Agent-provided PICO handoff        │
│   analyze_search_query()    → Query analysis without execution   │
│                                                                  │
└─────────────────────────────────────────────────────────────────┘
One search entry, three retrieval policies
Generic literature discovery is intentionally exposed through exactly one MCP
tool: unified_search. Provider-specific APIs remain internal broker
capabilities:
# Default relevance/keyword routing across enabled sources
unified_search(query="treatment resistance")

# OpenAlex native semantic search (provider maximum 50 results)
unified_search(
    query="mechanisms of treatment resistance",
    sources="openalex",
    options="native_semantic",
)

# Deterministic/bounded retrieval: OpenAlex cursor and S2 bulk where selected
unified_search(
    query="melanoma AND immunotherapy",
    sources="openalex,semantic_scholar",
    options="systematic",
)
native_semantic and systematic are mutually exclusive and disable the
multi-strategy deep-search expansion. Explicit source selections fail before a
network call when a requested retrieval mode is unsupported; automatic source
selection retains only capable providers. limit remains at most 100 per
source, so systematic means deterministic, bounded provider execution—not an
exhaustive systematic-review guarantee. Structured output and artifacts record
retrieval_mode plus per-source source_metadata (requested/provider mode,
canonical or compiled query, continuation availability, cost/rate metadata,
and warnings when available).
The public request boundary is fail-closed. limit must be an integer from 1
through 100; unknown or malformed filters / options, reversed or out-of-range
years, and unsupported ranking or output modes return a validation error before
provider I/O. In the default deep-search policy, limit is one total budget
per source divided across that source's query strategies—not limit results
for every strategy. Strategy calls use bounded global/per-source concurrency
and timeouts, and successful sources remain usable when another source times
out, is rate-limited, or fails.
PubMed, Europe PMC, Scopus, and Web of Science remain keyword-only in this release; explicit systematic requests for those sources fail before I/O instead of mislabeling a single page as systematic coverage.
See Source Contracts, Semantic Scholar, and OpenAlex for provider limits and operator data-plane boundaries.
🔬 Discovery Tools (After Finding Key Papers)
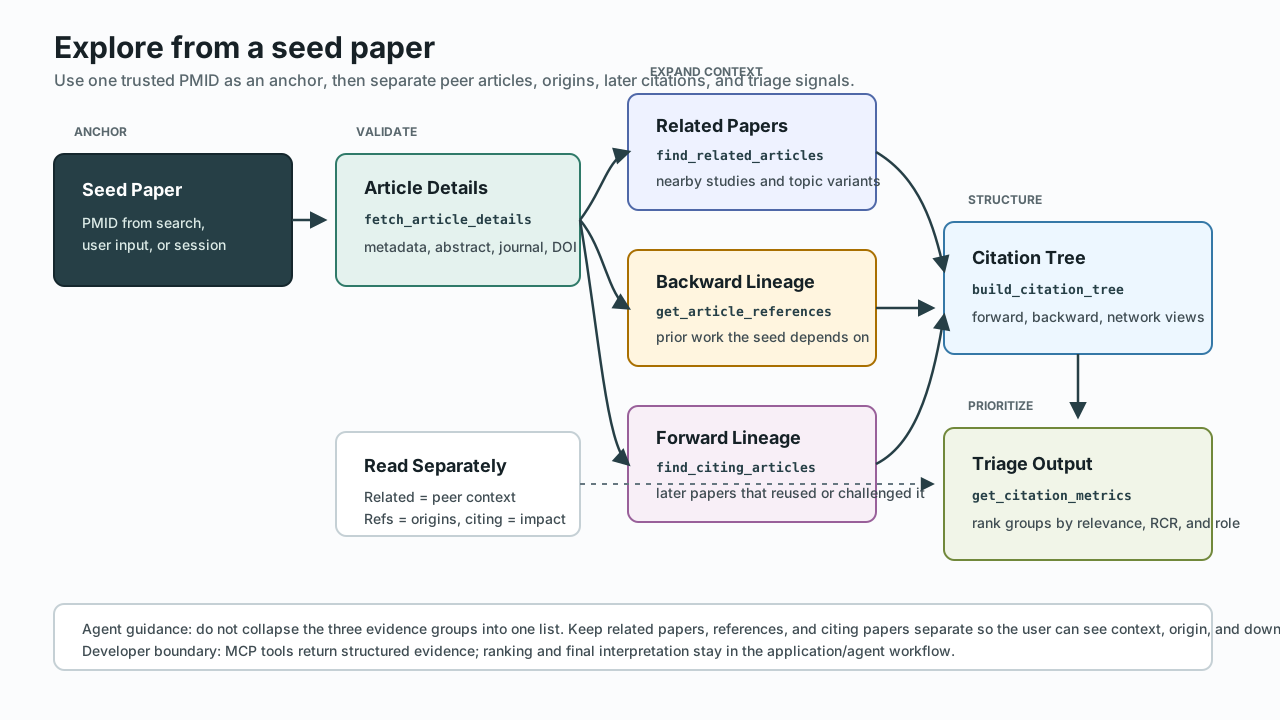
                        Found important paper (PMID)
                                   │
           ┌───────────────────────┼───────────────────────┐
           │                       │                       │
           ▼                       ▼                       ▼
    ┌─────────────┐        ┌─────────────┐        ┌─────────────┐
    │  BACKWARD   │        │  SIMILAR    │        │  FORWARD    │
    │  ◀──────    │        │  ≈≈≈≈≈≈     │        │  ──────▶    │
    │             │        │             │        │             │
    │ get_article │        │find_related │        │find_citing  │
    │ _references │        │ _articles   │        │ _articles   │
    │             │        │             │        │             │
    │ Foundation  │        │  Similar    │        │ Follow-up   │
    │  papers     │        │   topic     │        │  research   │
    └─────────────┘        └─────────────┘        └─────────────┘

    fetch_article_details()   → Detailed article metadata
    get_citation_metrics()    → iCite RCR, citation percentile
    build_citation_tree()     → Full network visualization (6 formats)
📚 Full Text, Figure Extraction & Export
For searches followed by close reading, unified_search(..., fulltext="prefetch")
prepares up to three eligible PMC XML articles in the background. Later
get_fulltext calls share ready/in-flight XML. Default is off; no polling or
speculative PDF/browser access. Tradeoffs and limits.
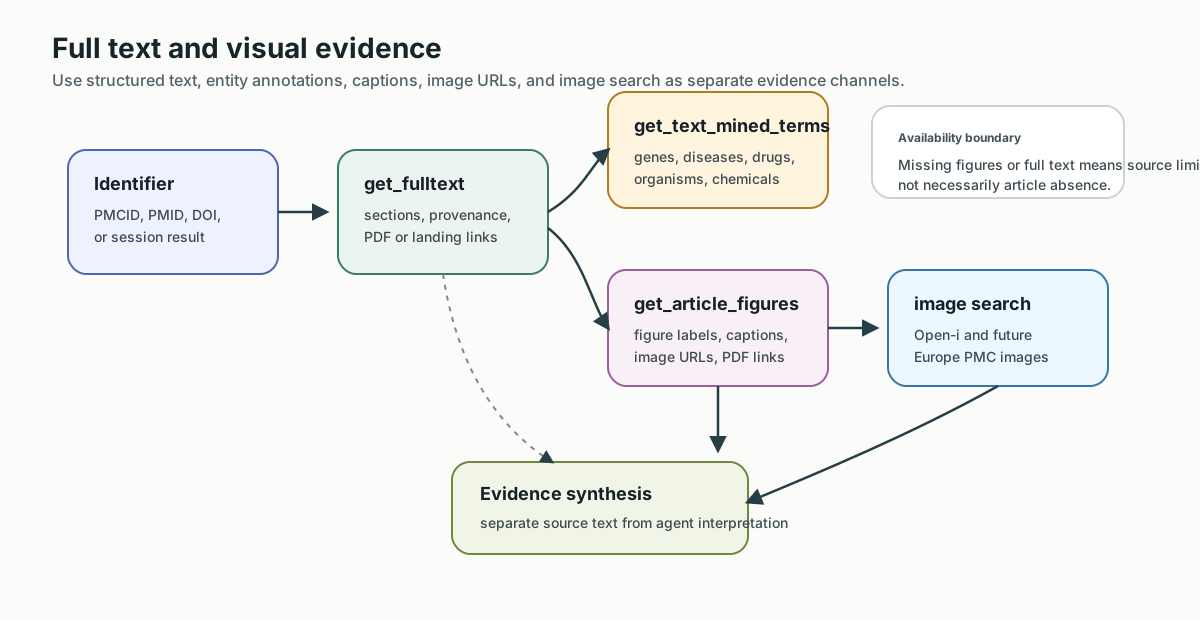
| Category | Tools |
|---|---|
| Full Text | get_fulltext → Europe PMC XML when a PMCID is available; DOI-backed Unpaywall, institutional direct/EZproxy, CORE, and downloader fallbacks when needed |
| Figures | get_article_figures → Extract figure labels, captions, image URLs, and PDF links from PMC Open Access articles |
| Figure-aware Full Text | get_fulltext(include_figures=True) → Embed figure metadata alongside structured fulltext |
| Text Mining | get_text_mined_terms → Extract genes, diseases, chemicals |
| Export | prepare_export → official RIS/MEDLINE/CSL JSON or local RIS/BibTeX/CSV/MEDLINE/JSON; save_literature_notes → local wiki/Foam-compatible/Markdown/MedPaper-style notes plus collection-level CSL JSON |
get_fulltext reports coverage_status, exact sources_tried /
sources_completed, and sanitized source_errors. A usable article or link
from one source plus a failure from another is therefore partial, not a
misleading complete success or empty result. Extended PDF discovery carries the
same immutable typed coverage envelope through discovery, download, extraction,
tool output, and artifacts.
🖼️ OA Figure-First Exploration
Use the PMC Open Access path when an agent needs evidence figures, not just article text:
get_article_figures(source={"kind":"pmcid","value":"PMC12086443"})→ Figure labels, captions, image URLs, and PDF/article linksget_fulltext(source={"kind":"pmcid","value":"PMC7096777"}, include_figures=True)→ Structured fulltext with figures inline- Figure output preserves article context, so agents can connect each figure back to the sections where it is mentioned
🧬 NCBI Extended Databases
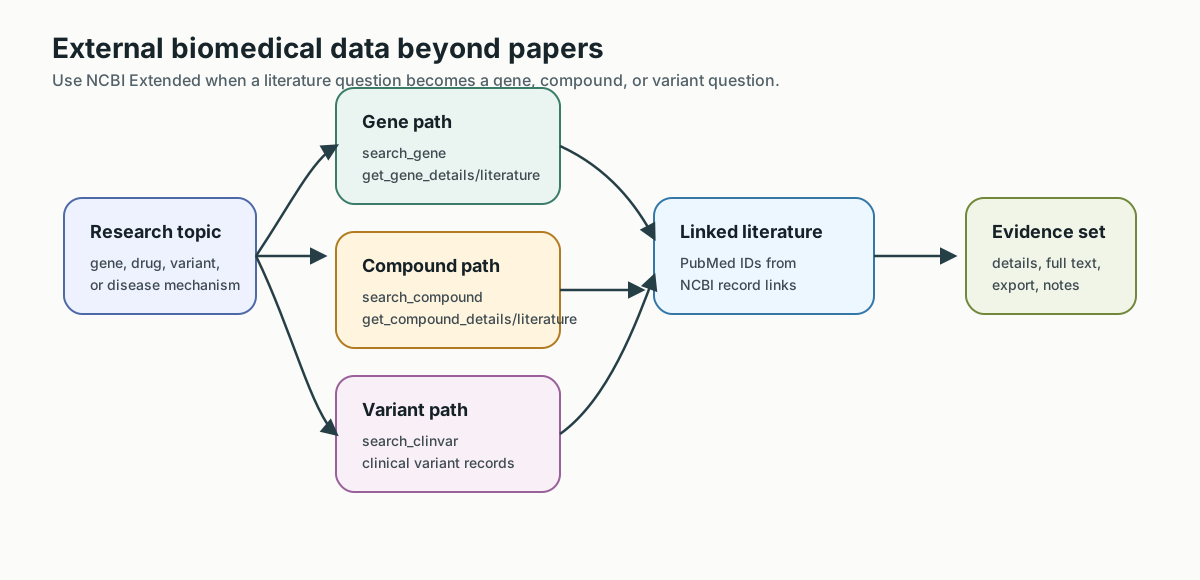
| Tool | Description |
|---|---|
search_gene | Search NCBI Gene database |
get_gene_details | Gene details by NCBI Gene ID |
get_gene_literature | PubMed articles linked to a gene |
search_compound | Search PubChem compounds |
get_compound_details | Compound details by PubChem CID |
get_compound_literature | PubMed articles linked to a compound |
search_clinvar | Search ClinVar clinical variants |
🕰️ Research Chronicle & Lineage Tree
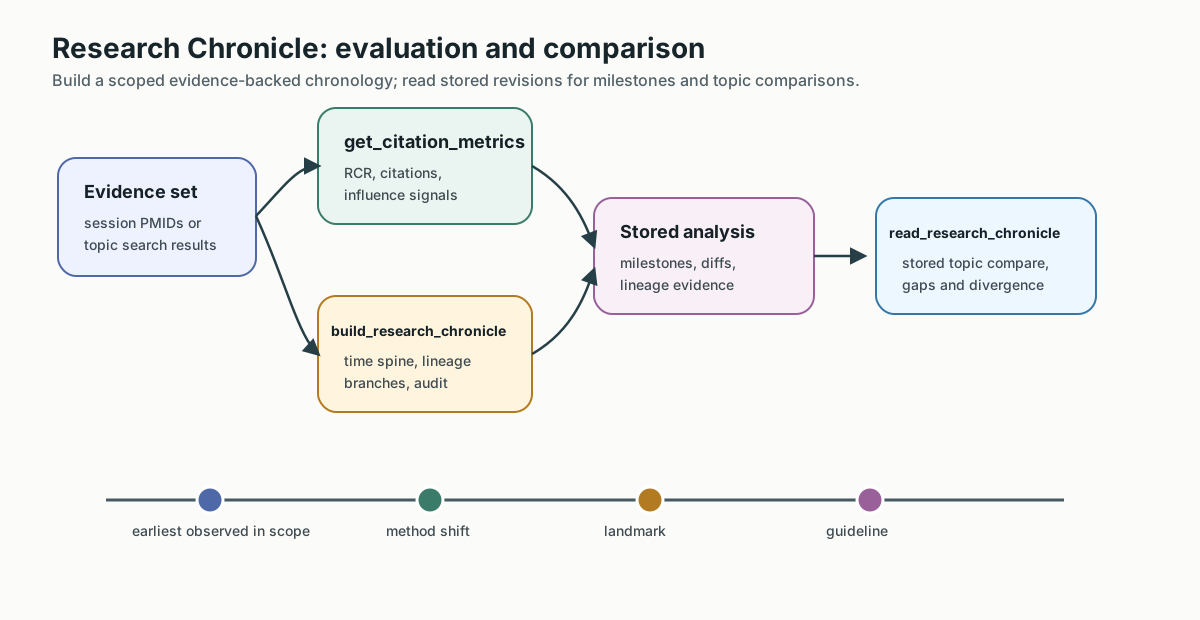
| Tool | Description |
|---|---|
build_research_chronicle | Build a persisted, versioned chronicle with landmark detection. Output: summary, chronicle_map, timeline, tree, graph, evidence, milestones, mermaid, narrative, json |
read_research_chronicle | Load, list, diff revisions, narrate with citations, analyze milestone distribution, or compare up to five topics |
# 1. Build from topic (retrieves PubMed, scores landmarks, clusters lineages)
build_research_chronicle(topic="remimazolam intraoperative", output="mermaid", max_events=30)

# 2. Continue an existing chronicle (inherits stored topic and filters to produce Revision N+1)
build_research_chronicle(chronicle_id="remimazolam-intraoperative-08c229f3")

# 3. Read revision diff, milestone analytics, or cross-topic comparison
read_research_chronicle(request={"action":"diff","chronicle_id":"remimazolam-intraoperative-08c229f3","from_revision":1})
read_research_chronicle(request={"action":"milestones","chronicle_id":"remimazolam-intraoperative-08c229f3"})
read_research_chronicle(request={"action":"compare","selection":{"kind":"topics","values":["remimazolam intraoperative","propofol intraoperative"]}})
mermaid is the canonical combined view: a horizontal year spine (X-axis) with each
observed research line (Y-axis) branching at its earliest dated paper within the
retrieved scope. This is an explainable grouping, not a causal genealogy or a
claim about the field's true first paper. Lineages prefer MeSH descriptors and
author keywords shared by multiple papers; singleton-only or insufficient
signals trigger a warned research-stage fallback. Same-year display order is
stable, but does not assert precedence when publication precision cannot prove
it. See
Advanced Research Workflows (docs/guides/ADVANCED_RESEARCH_WORKFLOWS.md) and
docs/design/RESEARCH_CHRONICLE_REFACTOR_SPEC.md.
Chronicle Mermaid output is built from structured nodes and edges, with safe
label escaping, cycle/orphan repair, collision-resistant IDs, and bounded graph
size. It falls back from rich to safe to minimal syntax instead of failing the
whole chronicle. mermaid_validation.json records every correction, fallback,
and omitted visual item; chronicle.mmd remains pure Mermaid source.
Chronicle revisions are immutable and appended atomically. When session artifact persistence is enabled, artifact failure is surfaced explicitly while the saved Chronicle revision remains available.
Topic builds send year limits to PubMed before bounded retrieval, then preserve
the first and last observed papers while filling the cap with landmarks and
temporal spread. The audit records PubMed returned / available counts and
warns when availability is unknown or any retrieval/selection cap makes the
view non-exhaustive. PubMed errors or a scope with no article evidence do not
publish an empty revision.
Retrieval provenance separates ranking_requested from the effective
ranking. iCite ordering is claimed only when a validated citation count was
actually applied. The versioned citation-metrics coverage records complete,
partial, empty, error, and not-requested outcomes with safe counts and errors;
the audit warns or fails rather than treating an outage as zero citations.
Documentation truncated — see the full README on GitHub.
Reviews
No reviews yet
Be the first to review this server!
More Education & Research MCP Servers
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
MCP Marketplace
Freeby mcp-marketplace · Developer Tools
Search and install MCP servers from inside your AI client.
mcp-creator-python
Freeby mcp-marketplace · Developer Tools
Create, build, and publish Python MCP servers to PyPI — conversationally.
FinAgent
Freeby mcp-marketplace · Finance
Free stock data and market news for any MCP-compatible AI assistant.
by Lharries · Communication
Read, search, and send WhatsApp messages through your AI assistant
Memory
Freeby Modelcontextprotocol · Productivity
Knowledge graph-based persistent memory across sessions