
Server data from the Official MCP Registry
Biomedical MCP server: genes, variants, trials, literature, patents, optional SQL/R/biowasm tools.
About
Biomedical MCP server: genes, variants, trials, literature, patents, optional SQL/R/biowasm tools.
Security Report
BioMCP is a well-structured biomedical MCP server with comprehensive input validation, proper error handling, and reasonable security practices. The codebase demonstrates good engineering discipline with thorough testing and appropriate permission scoping for its bioinformatics/database access purpose. Minor concerns include broad exception handling in some areas, informational logging practices, and the need for stronger credential storage guidance in documentation, but these do not significantly impact the security posture. Supply chain analysis found 2 known vulnerabilities in dependencies (0 critical, 1 high severity). Package verification found 1 issue.
3 files analyzed · 8 issues found
Security scores are indicators to help you make informed decisions, not guarantees. Always review permissions before connecting any MCP server.
Permissions Required
This plugin requests these system permissions. Most are normal for its category.
What You'll Need
Set these up before or after installing:
Environment variable: ANALYSIS_BIOWASM
Environment variable: ANALYSIS_R
Environment variable: DB_TYPE
Environment variable: NCBI_API_KEY
Environment variable: S2_API_KEY
Environment variable: OPENFDA_API_KEY
Environment variable: ONCOKB_TOKEN
Environment variable: DISGENET_API_KEY
How to Install
Add this to your MCP configuration file:
{
  "mcpServers": {
    "io-github-yeyuan98-biomcp-ts": {
      "env": {
        "DB_TYPE": "your-db-type-here",
        "ANALYSIS_R": "your-analysis-r-here",
        "S2_API_KEY": "your-s2-api-key-here",
        "NCBI_API_KEY": "your-ncbi-api-key-here",
        "ONCOKB_TOKEN": "your-oncokb-token-here",
        "OPENFDA_API_KEY": "your-openfda-api-key-here",
        "ANALYSIS_BIOWASM": "your-analysis-biowasm-here",
        "DISGENET_API_KEY": "your-disgenet-api-key-here"
      },
      "args": [
        "-y",
        "biomcp"
      ],
      "command": "npx"
    }
  }
}Documentation
View on GitHubFrom the project's GitHub README.
BioMCP


Highlights
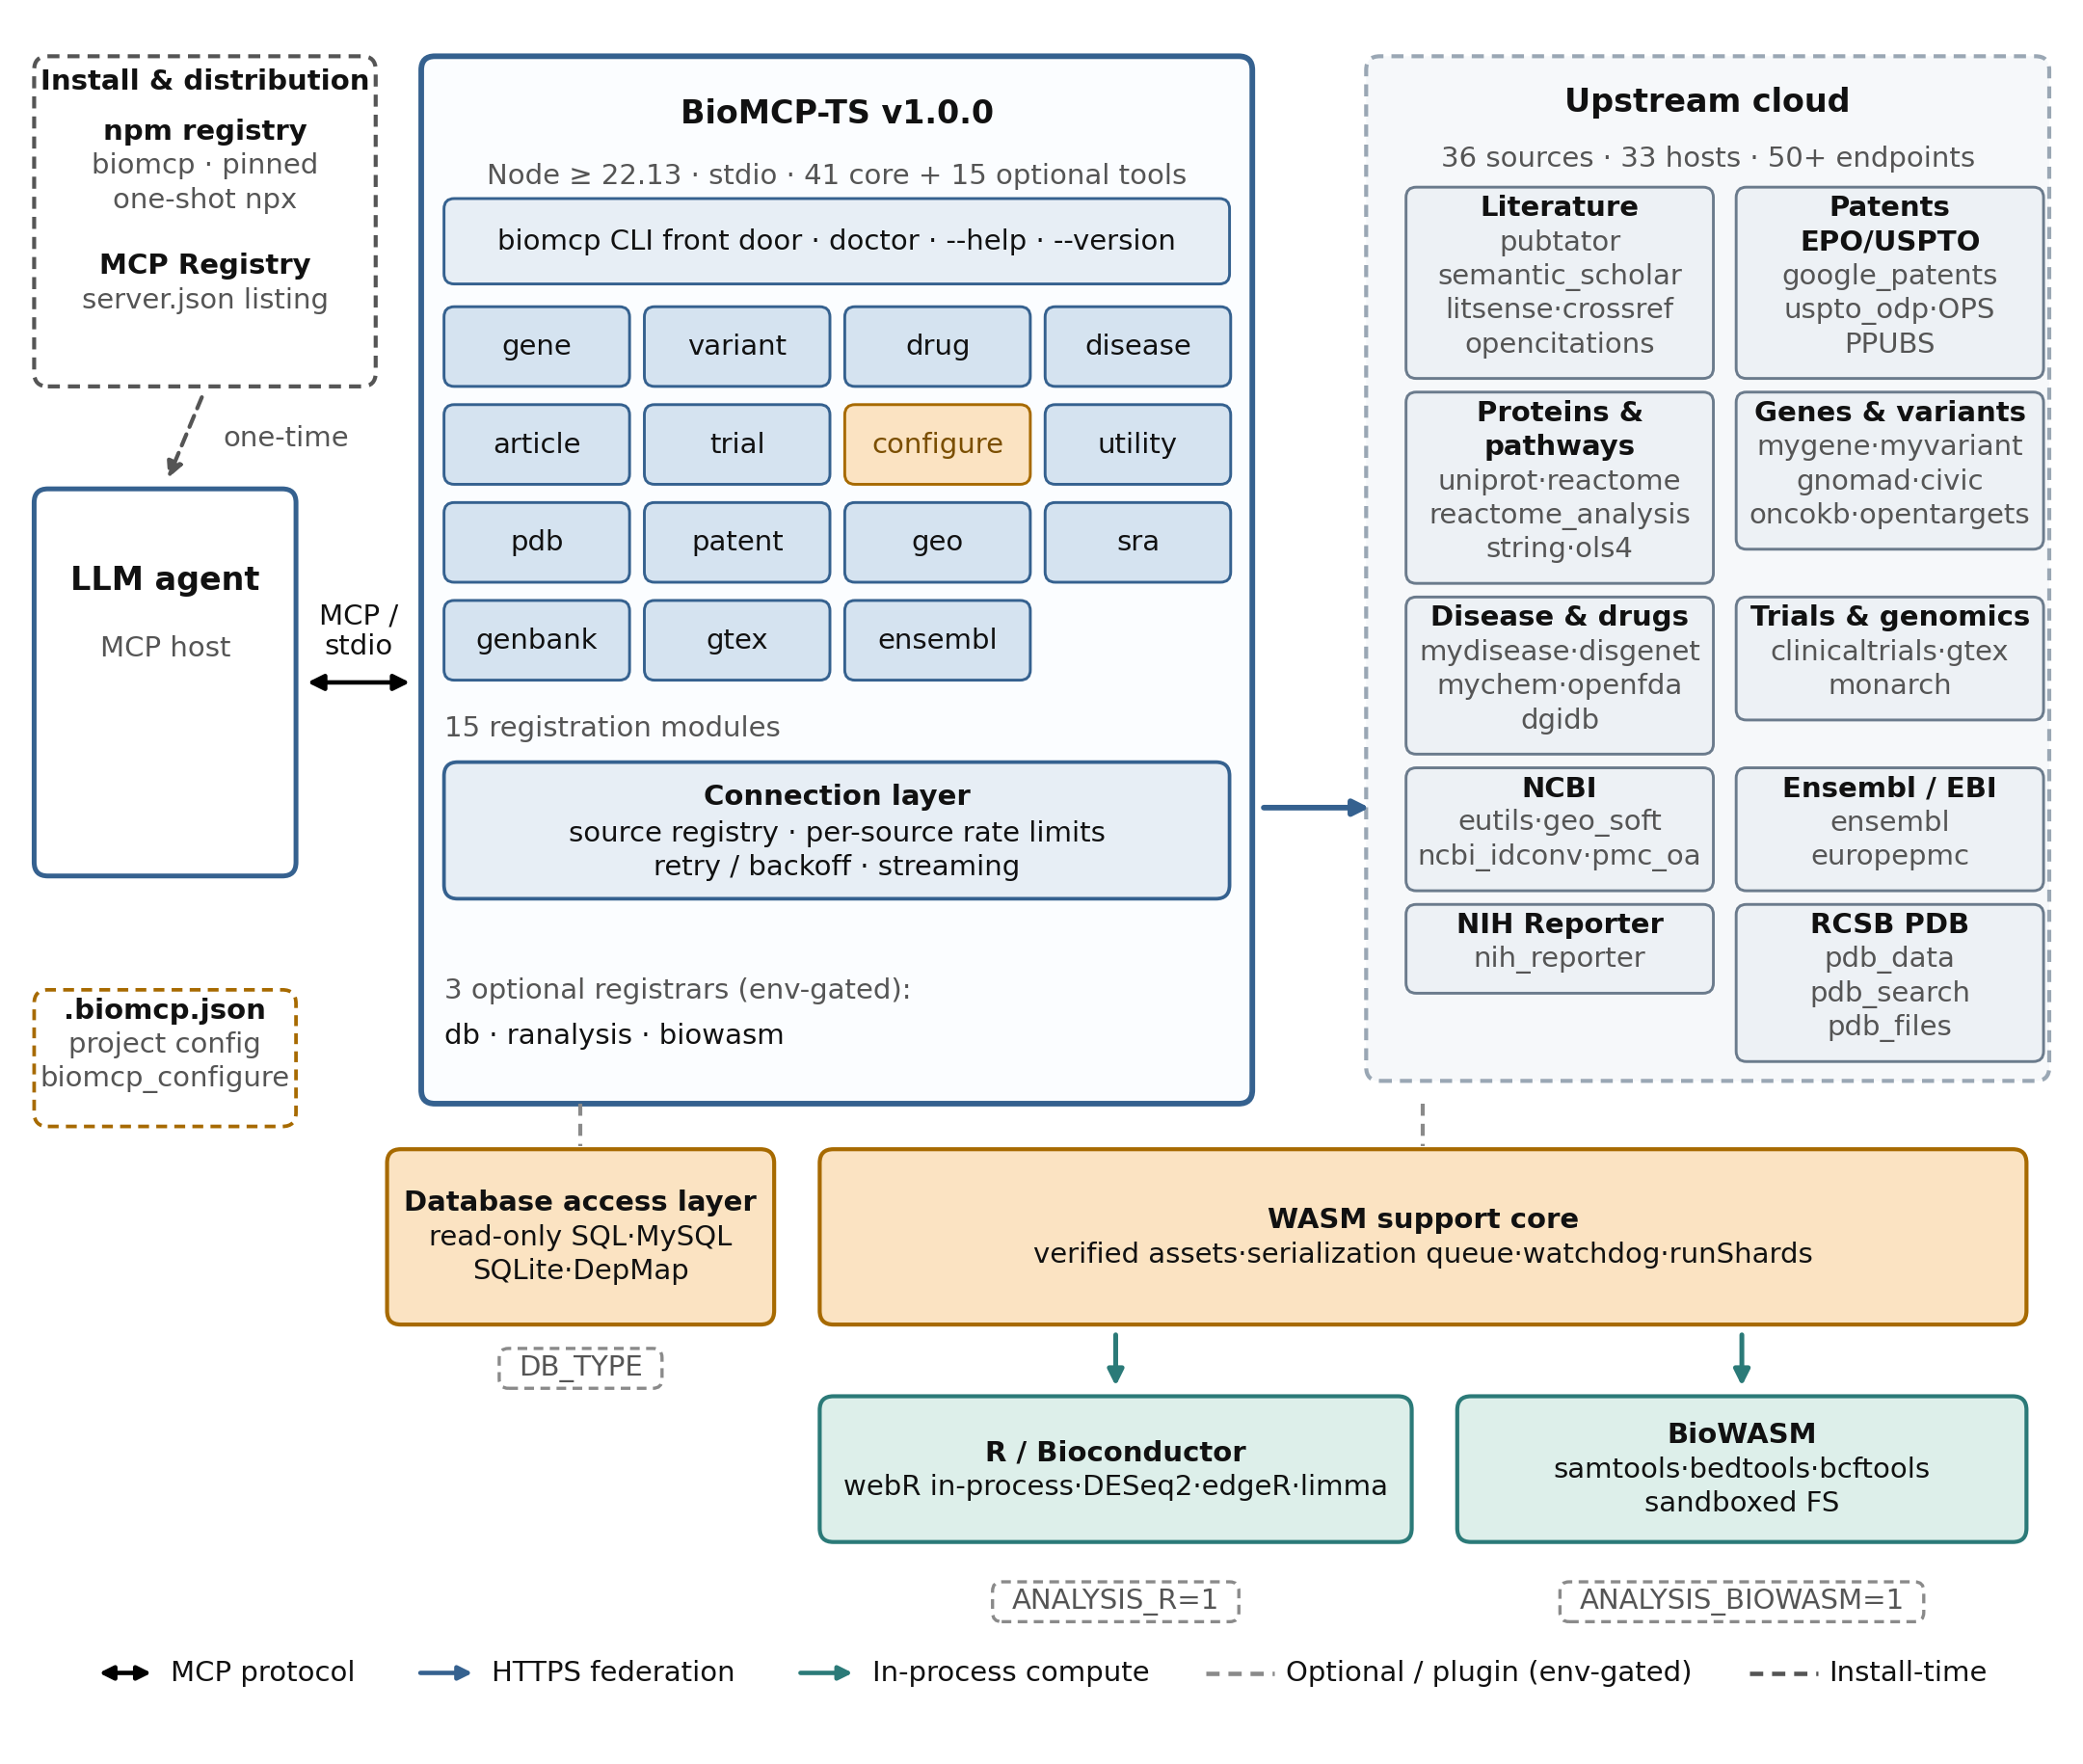
Democratizing agentic access to bioinformatics and biopharmaceutical databases and analyses.
- Section-based federated access to 50+ bioinformatics, pharmaceutical, and patent databases
- Optional toolboxes for local database curation and dependency-free analysis with Bioconductor and SAM/BED/BCFtools — no R installation, C toolchain, or containers
- Concrete example vignettes, developed fully in the open
Install
npx -y biomcp doctor   # diagnose a machine: Node gate, config health, feature gates, peer deps
npx biomcp             # zero-config stdio MCP server (this is what MCP clients run); Node >= 22.13
Setup is guided in docs/AGENT-INSTALL.md — a one-minute start, copy-paste config entries for Claude Desktop, Claude Code, Codex, and OpenCode (one canonical pinned command covering every feature), biomcp doctor as the single troubleshooting entry point, and agent-friendly paths for API keys and optional features.
Multiple agents on one machine: biomcp enforces arXiv's Terms-of-Use rate limit (1 request / 3 s) per process. When running multiple biomcp MCP instances on one machine (e.g., one stdio instance per agent), rate limits are not coordinated across processes, and arXiv's TOU applies to all your machines in aggregate. For multi-agent single-machine deployments, run a single shared biomcp serve daemon (see docs/SELF-HOSTING.md) so all agents share one process and one global rate limiter.
Available Tools
Full tool schemas (params, enums, defaults) live in src/server/README.md.
Gene (7)
| Tool | Description |
|---|---|
gene_search | Search genes by symbol, name, or keyword with chromosome filter |
gene_get | Get detailed gene info by HGNC symbol with optional sections (core, pathways, protein, ontology, go, interactions, expression, protein_atlas, constraint, druggability, dosage_sensitivity, clinical_evidence, disease_associations, diseases, funding). Set smart=true to auto-resolve gene aliases (e.g., "HER2" → "ERBB2") |
gene_diseases | Get diseases associated with a gene (DisGeNET / OpenTargets) |
gene_drugs | Find drugs targeting a gene (OpenTargets) |
gene_trials | Find clinical trials for a gene |
gene_articles | Find articles about a gene |
gene_enrich | Pathway enrichment analysis for a gene list (Reactome) |
Variant (4)
| Tool | Description |
|---|---|
variant_search | Search variants by rsid, HGVS, gene, ClinVar significance, frequency, CADD |
variant_get | Get detailed variant info with optional sections (frequency, predictions, clinical; alphagenome_scores currently returns an unavailability error pending reimplementation) |
variant_oncokb | Get OncoKB cancer variant annotations (requires ONCOKB_TOKEN) |
variant_trials | Find clinical trials for a variant |
Drug (3)
| Tool | Description |
|---|---|
drug_search | Search drugs by name, mechanism, or keyword |
drug_get | Get detailed drug info with optional sections (us_regulatory, eu_regulatory, who_regulatory, safety, targets, indications, adverse_events — FDA FAERS reactions ranked by report count) |
drug_trials | Find clinical trials for a drug |
Disease (4)
| Tool | Description |
|---|---|
disease_search | Search diseases by name, phenotype, or keyword |
disease_get | Get detailed disease info by ID (DOID, MONDO, OMIM, etc.) with optional sections (gene_associations, phenotypes, pathways) |
disease_drugs | Get drugs for a disease (OpenTargets) |
disease_trials | Get clinical trials for a disease (ClinicalTrials.gov) |
Article (2)
| Tool | Description |
|---|---|
article_search | Federated literature search across PubMed, EuropePMC, Semantic Scholar, arXiv, PubTator, and LitSense with optional date range filtering; source: "preprint_only" switches to bioRxiv+medRxiv preprints only (abstracts, citation counts, date filtering) |
article_get | Get detailed article info by identifier (PMID, PMCID, DOI, or bioRxiv/medRxiv preprint DOI) with optional sections: fulltext (the complete article text when freely readable in PMC/Europe PMC — open-access AND free-to-read articles; by default (fulltext_output="file") written to a server-side markdown file with the reply carrying file_path + an outline of headings with line numbers and char counts for selective Read/Grep, keeping body text out of the agent context; fulltext_output="inline" returns capped text sections via fulltext_max_chars, default 40000), oa (open-access/license metadata and links: status open_access/free_to_read/paywalled/not_in_pmc/unknown, license, pmc/pdf/doi links), annotations, graph (citation graph), citation (fast/full citation data; Europe PMC citations for preprints). all excludes fulltext. Preprint records include all versions, license, category, funders, JATS full-text URL (link only), and published-version mapping |
Trial (2)
| Tool | Description |
|---|---|
trial_search | Search clinical trials by condition, intervention, status, or phase. Cursor-based pagination via page_token |
trial_get | Get detailed trial info by NCT ID with optional sections (eligibility, locations, outcomes) |
Utility (2)
| Tool | Description |
|---|---|
discover | Free-text concept resolution across all entity types |
batch_get | Retrieve multiple entities in parallel |
Structural Biology (1)
| Tool | Description |
|---|---|
pdb | Search PDB structures, get entry metadata with optional sections (polymer entities, ligands, assembly, experiment, citation), and download structure files (mmCIF/PDB) |
Patents (2)
| Tool | Description |
|---|---|
patent_search | Search patents worldwide (US, EP, WO, JP, 100+ authorities) with assignee/inventor/CPC/status/date filters and relevance ranking (sort_by). Quote exact multi-word concepts (e.g. "mRNA display"). Foundational prior art is auto-discovered via co-citation mining (seminal_prior_art; disable with seminal: false). Default backends: USPTO Public Search full-text (US, keyless, relevance-ranked) + EPO OPS (worldwide, keyed); uspto_odp (US bibliographic metadata) and google_patents (best-effort) available via source |
patent_get | Get patent details by publication number with sections: abstract, claims (US fulltext via USPTO Public Search; EP/WO via EPO OPS), citations (forward + backward), family, classifications |
GEO (2)
| Tool | Description |
|---|---|
geo_search | Search NCBI GEO for functional genomics studies (expression microarrays, RNA-seq, single-cell series) by entry type (GSE/GSM/GPL/GDS) and organism; results carry cross-links (sra_project, bioproject, pubmed_ids) for chaining |
geo_get | Get the full SOFT record for a GEO series/sample/platform: summary, organisms, sample preview (≤20), supplementary file URLs, and cross-references; optionally download the first supplementary file |
SRA (2)
| Tool | Description |
|---|---|
sra_search | Search NCBI's Sequence Read Archive for sequencing experiments and runs by free text, accession, or field syntax; returns experiment/study/sample accessions with library strategy and run counts |
sra_get | Get full details for an SRA accession: SRR run (instrument, spots, bases, size), SRX experiment (library design), SRP study (experiment list), or SRS sample; ENA/DDBJ accessions rejected with an ENA pointer |
GenBank (3)
| Tool | Description |
|---|---|
genbank_search | Search NCBI nucleotide records (GenBank/RefSeq/INSDC) by plain terms, accession, or field syntax; results include accession.version, definition, length, organism, topology |
genbank_get | Fetch a GenBank/RefSeq record as GenBank flat file or FASTA; whole records capped at 2 Mb — larger records require a seq_start/seq_stop region (up to 10 Mb, reverse-strand via strand=2) |
genbank_genes | Map a GenBank/RefSeq accession to its NCBI Gene IDs (elink nuccore→gene) for bridging into gene tools |
GTEx (2)
| Tool | Description |
|---|---|
gtex_expression | Get median gene expression across GTEx tissues (Analysis v10, 54 tissue sites, TPM, highest first); accepts HGNC symbol or Ensembl gene ID, with optional single-tissue filter |
gtex_eqtl | Get significant cis-eQTL associations for a gene in a specific GTEx tissue (v10): variant_id, p_value, NES, slope, sorted by ascending p-value |
Ensembl (4)
| Tool | Description |
|---|---|
ensembl_lookup | Resolve a gene in Ensembl terms for any of ~356 species: stable ID (+version), symbol, coordinates on the current assembly, canonical transcript; expand=true adds transcripts with translation/protein IDs |
ensembl_homology | Find orthologues/paralogues across species via Ensembl Compara — target stable IDs, taxonomy level, percent identity, sorted by identity; filter with target_species/target_taxon |
ensembl_consequence | Compute variant consequences on demand via Ensembl VEP for NOVEL variants and non-human species: most severe consequence, per-transcript effects (SIFT/PolyPhen), co-located ClinVar/COSMIC/gnomAD data. Known human variants get deeper pre-computed scores via variant_get; prefer HGVS input over rsIDs for precision |
ensembl_region | Query genes/transcripts/known variants in a genomic interval (chr:start-end) on the current assembly — locus triage |
R Analysis (4, optional — ANALYSIS_R=1)
| Tool | Description |
|---|---|
analysis_r_deseq2 | Differential expression for RNA-seq counts with Bioconductor DESeq2 (negative binomial, independent filtering, optional LFC shrinkage) in sandboxed WebAssembly R. Inputs: integer count matrix + sample metadata + design formula; output: markdown table of top genes by adjusted p-value with summary (format="json", include_full=true for full base64(gzip(TSV)) table) |
analysis_r_edger | Differential expression with edgeR — TMM normalization, empirical-Bayes dispersion, quasi-likelihood F-test (test="qlm") or 2-group exact test; same input/output contract |
analysis_r_limma | Differential expression with limma-voom — precision-weighted linear models with empirical-Bayes moderation; same input/output contract |
analysis_r_session_info | R runtime report: R/webR versions, installed package versions, memory, mirror endpoint — for diagnosing analysis issues |
First use starts a ~1 GB WebAssembly R worker and downloads the wasm package bundle (~62 MB) from GitHub releases (cached). Requires webr installed next to biomcp. Guide: docs/R-ANALYSIS.md.
Biowasm Analysis (8, optional — ANALYSIS_BIOWASM=1)
| Tool | Description |
|---|---|
analysis_bam_summary | Inspect an alignment (SAM/BAM/CRAM): header contigs, sample/read groups, flagstat mapping metrics, per-contig counts via idxstats when indexed — "what's in this BAM?" before region work |
analysis_bam_view_region | Reads, depth, pileup, or read extraction in a genomic region (samtools view/depth/mpileup); indexed sources use fast positional retrieval, indexless sources stream a BED filter (depth requires coordinate-sorted input and detects order violations), returning counts, coverage tables, SAM rows, or a BAM artifact |
analysis_bcf_summary | Inspect a VCF/BCF: contigs, sample count and names, INFO/FORMAT field inventory from the header |
analysis_bcf_view_region | Variants in a region as a narrow field projection (bcftools query): chosen columns, sample subsets, expression filters, variant types — or a sliced VCF.gz artifact |
analysis_bed_op | Interval algebra on BED tracks (bedtools intersect/merge/subtract/coverage/jaccard/sort) with the streaming -sorted algorithm for sorted inputs |
analysis_biowasm_convert | Format plumbing: SAM/BAM/CRAM via samtools view, VCF/BCF via bcftools view, VCF/BCF → TSV via bcftools query; results are artifact handles reusable as artifact_id |
analysis_biowasm_session_info | Biowasm runtime report: pinned tool versions, asset cache state, engine status, retained artifacts, memory |
analysis_biowasm_cli | Constrained escape hatch: an allowlisted samtools/bedtools/bcftools subcommand with schema-validated args (no shell, paths under /shared only) |
First use downloads checksum-verified wasm assets (~4.5 MB, cached); no extra npm packages. Indexed sources answer region queries with fast positional retrieval (~0.2 % of file read); indexless sources fall back to streaming BED filters. Guide: docs/BIOWASM-ANALYSIS.md.
Citation Module
Citations federate 5 providers in fast (~4s) or full (~15-30s) mode. Forward citation lists come from Europe PMC, OpenCitations, and Semantic Scholar; Crossref supplies counts and backward references. Provider matrix and schema details: src/server/README.md.
Optional Features
Capabilities that ship with the package but stay inactive until enabled. Each links to its own guide:
| Feature | Enable | Guide |
|---|---|---|
Database access — read-only SQL tools (db_query, db_list_tables, db_describe_table) for MySQL and local-file SQLite | Set DB_TYPE (+ connection env vars); MySQL needs the mysql2 peer dep — use the pinned one-shot client command (see docs/DATABASE.md) | docs/DATABASE.md |
R analysis — Bioconductor differential expression (analysis_r_deseq2, analysis_r_edger, analysis_r_limma, analysis_r_session_info) running DESeq2/edgeR/limma in sandboxed WebAssembly R; wasm packages download from GitHub releases at first use (~62 MB, cached; slow links: asset_timeout_ms or a self-fetched mirror_url) | Set ANALYSIS_R=1; needs the webr peer dep — use the pinned one-shot client command ["npx","-y","-p","biomcp@1.6","-p","webr@0.6","biomcp"] (all-features variant adds -p mysql2@3); expect ~1 GB RSS | docs/R-ANALYSIS.md |
| Biowasm analysis — samtools/bedtools/bcftools (BAM/BED/VCF) in sandboxed WebAssembly; streams/indexes real human-scale datasets (~300 MB BAM scans, region queries touch ~0.2 % of the file); assets ~4.5 MB cached at first use; no extra npm packages | Set ANALYSIS_BIOWASM=1 | docs/BIOWASM-ANALYSIS.md |
Instead of hand-editing env blocks, agents (and users) can self-serve through the always-available biomcp_configure tool: it reports every parameter's status/provenance, writes the .biomcp.json project config file for the optional features above (env vars keep precedence; env-only parameters are query-only and value-masked), validates changes, detects conflicts, checks peer-dependency prerequisites, and spells out the restart/verify steps. Details: docs/ENV-VARS.md → Project config file.
Documentation
| Doc | Contents |
|---|---|
| docs/AGENT-INSTALL.md | Guided installation & client configuration (Claude Desktop, Claude Code, Codex, OpenCode) |
| docs/ENV-VARS.md | Single source of truth for every environment variable |
| docs/DATABASE.md | Database access feature guide |
| docs/R-ANALYSIS.md | R analysis feature guide (Bioconductor in WebAssembly) |
| docs/BIOWASM-ANALYSIS.md | Biowasm analysis feature guide (samtools/bedtools/bcftools in WebAssembly) |
| docs/DEVELOPMENT.md | Build, test, publish workflow |
| docs/development/CI.md | CI pipeline, Dependabot automation, auto-merge safety model |
| src/server/README.md | Full tool schemas (params, enums, defaults) |
| agent-test/README.md | User-agent E2E tests for the analysis tools |
License
Licensed under the Apache License, Version 2.0. See NOTICE for attributions.
BioMCP-TS is adapted from the upstream BioMCP Rust project (MIT) with an agent-first development approach and enhancements — kudos to the original authors.
Reviews
No reviews yet
Be the first to review this server!
More Developer Tools MCP Servers
Fetch
Freeby Modelcontextprotocol · Developer Tools
Web content fetching and conversion for efficient LLM usage
Git
Freeby Modelcontextprotocol · Developer Tools
Read, search, and manipulate Git repositories programmatically
Toleno
Freeby Toleno · Developer Tools
Toleno Network MCP Server — Manage your Toleno mining account with Claude AI using natural language.
MCP Marketplace
Freeby mcp-marketplace · Developer Tools
Search and install MCP servers from inside your AI client.
mcp-creator-python
Freeby mcp-marketplace · Developer Tools
Create, build, and publish Python MCP servers to PyPI — conversationally.
FinAgent
Freeby mcp-marketplace · Finance
Free stock data and market news for any MCP-compatible AI assistant.